
JavaScript (261)
Add or Remove Cell Borders in Excel in React with JavaScript
2026-09-29 02:58:28 Written by liu taliaThe real dividers in a spreadsheet are not blank cells but borders: financial reports use lines of different weights to separate the header row from the totals, while data handed to a downstream system has to go out with the frames stripped off. Doing that by hand — selecting each block and opening Format Cells — is slow and hard to repeat. Spire.XLS for JavaScript does the same work in the browser on top of WebAssembly, using a virtual file system (VFS) for input and output files, so no back-end service is needed.
This article covers four feature points:
- Add a border to a selected cell or a cell range
- Add a border to the range that holds the data
- Add left, top, right, bottom and diagonal borders to a cell
- Remove the borders of a cell or a cell range
For installation and project setup, see Integrating Spire.XLS for JavaScript in a React Project. The examples below assume Spire.XLS is installed and the WebAssembly module has been initialised.
Add a border to a selected cell or a cell range
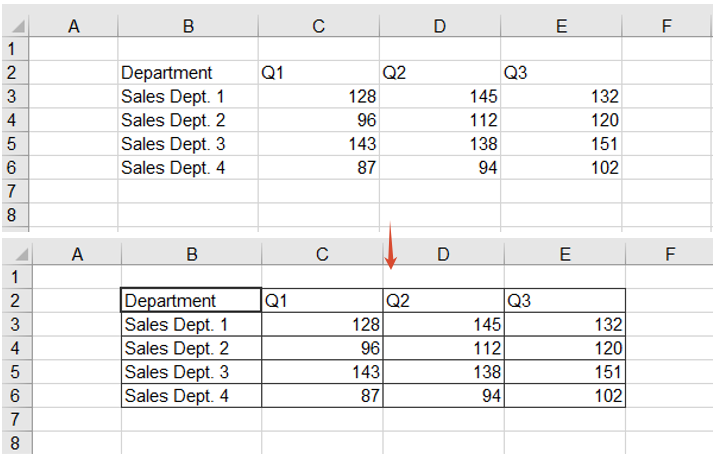
Given a table with no lines at all, the most direct approach is to put the frame back with BorderAround and BorderInside: the first one draws the outline, the second one the grid lines inside the range. Together they frame a whole block of data in one go, and they can also single out one cell — the header cell, say — so that it stands out from a sheet full of identical lines.
The steps are:
- Take the cell range you want to frame with
Range.get, by address - Call
BorderAroundto draw the outline, with the line style taken from theLineStyleTypeenumeration - Call
BorderInsideto add the separators between the cells inside the range - Take the header cell on its own and call
BorderAroundagain on it, this time with a medium line
The line style is passed in object notation, as { borderLine }.
function App() {
  const addBorderToCells = async () => {
    // Get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // Check that the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // Load the font and the input file into the VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'CellBorders.xlsx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}data/`);

    // Load the workbook and take the first worksheet
    const workbook = new xlsModule.Workbook();
    workbook.LoadFromFile({ fileName: inputFileName });
    const sheet = workbook.Worksheets.get(0);

    // Take the B2:E6 range, frame it with thin lines and add thin inner lines
    const dataRange = sheet.Range.get('B2:E6');
    dataRange.BorderAround({ borderLine: xlsModule.LineStyleType.Thin });
    dataRange.BorderInside({ borderLine: xlsModule.LineStyleType.Thin });

    // Give the B2 header cell a medium border on all four sides
    sheet.Range.get('B2').BorderAround({ borderLine: xlsModule.LineStyleType.Medium });

    // Save the result file
    const outputFileName = 'AddBorderToCells.xlsx';
    workbook.SaveToFile({ fileName: outputFileName, version: xlsModule.ExcelVersion.Version2010 });

    // Dispose of the workbook object to free resources
    workbook.Dispose();

    // Read the result file back out of the VFS and download it
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.spreadsheetml.sheet' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add or Remove Cell Borders</h1>
      <button onClick={addBorderToCells}>Add a border to a cell or range</button>
    </div>
  );
}

export default App;
The effect of adding a border to the data range and to the header cell:
Add a border to the range that holds the data
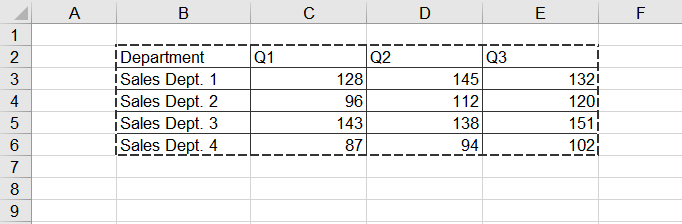
The previous section hard-codes the address B2:E6, which has to be edited as soon as rows or columns are added to the table. The AllocatedRange property returns the allocated range of a worksheet — the rectangle that actually holds the data — so the address maintains itself, and the outline can be given a different style from the header frame to set the table apart from the text around it.
The steps are:
- Get the range that holds the data through
AllocatedRange, with no address to maintain - Call
BorderAroundwith a medium dashed line, so the outline contrasts with the solid frames used elsewhere - Call
BorderInsideto add thin lines inside the range, keeping the rows separated
function App() {
  const addBorderToDataRange = async () => {
    const xlsModule = window.wasmModule?.spirexls;
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'CellBorders.xlsx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}data/`);

    const workbook = new xlsModule.Workbook();
    workbook.LoadFromFile({ fileName: inputFileName });
    const sheet = workbook.Worksheets.get(0);

    // AllocatedRange returns the range that holds the data, so no address is needed
    const dataRange = sheet.AllocatedRange;

    // Give the outline a medium dashed border and the inside thin lines
    dataRange.BorderAround({ borderLine: xlsModule.LineStyleType.MediumDashed });
    dataRange.BorderInside({ borderLine: xlsModule.LineStyleType.Thin });

    const outputFileName = 'AddBorderToDataRange.xlsx';
    workbook.SaveToFile({ fileName: outputFileName, version: xlsModule.ExcelVersion.Version2010 });
    workbook.Dispose();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.spreadsheetml.sheet' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add or Remove Cell Borders</h1>
      <button onClick={addBorderToDataRange}>Add a border to the data range</button>
    </div>
  );
}

export default App;
The effect of adding a dashed outline and thin inner lines to the data range:
Add left, top, right, bottom and diagonal borders to a cell
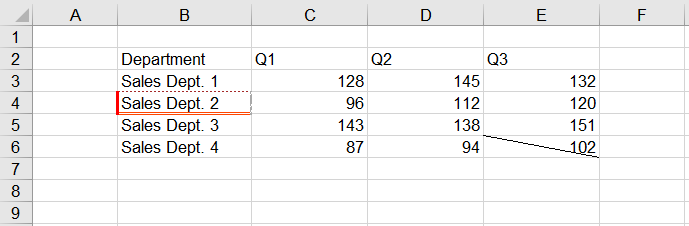
BorderAround gives all four edges the same style, which is not enough when the requirement is "a thick red line on the left and a double line along the bottom". Handling the edges one at a time solves it: Borders.get takes a single edge by its BordersLineType member, and its LineStyle and Color can then be set independently, so every edge can have its own line style and colour. The two diagonal directions are available the same way.
The steps are:
- Take the cell to style with
Range.get - Take the left, top, right and bottom edges through
Borders.get(BordersLineType.EdgeLeft)and its siblings - Set
LineStyleon each edge, using a thick line, a dotted line, a slanted dash-dot line and a double line - Set
Coloron each edge, using red, brown, dark grey and orange red - Take another cell, fetch its diagonal-down edge with
BordersLineType.DiagonalDownand set its line style
function App() {
  const addEdgeBorders = async () => {
    const xlsModule = window.wasmModule?.spirexls;
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'CellBorders.xlsx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}data/`);

    const workbook = new xlsModule.Workbook();
    workbook.LoadFromFile({ fileName: inputFileName });
    const sheet = workbook.Worksheets.get(0);

    // Give each of the four edges of B4 its own line style and colour
    const cell = sheet.Range.get('B4');
    const edgeSpecs = [
      ['EdgeLeft', xlsModule.LineStyleType.Thick, xlsModule.Color.get_Red()],
      ['EdgeTop', xlsModule.LineStyleType.Dotted, xlsModule.Color.get_Brown()],
      ['EdgeRight', xlsModule.LineStyleType.SlantedDashDot, xlsModule.Color.get_DarkGray()],
      ['EdgeBottom', xlsModule.LineStyleType.Double, xlsModule.Color.get_OrangeRed()],
    ];
    for (const [edge, lineStyle, color] of edgeSpecs) {
      const border = cell.Borders.get(xlsModule.BordersLineType[edge]);
      border.LineStyle = lineStyle;
      border.Color = color;
    }

    // Add a diagonal-down border to E6
    const diagonal = sheet.Range.get('E6').Borders.get(xlsModule.BordersLineType.DiagonalDown);
    diagonal.LineStyle = xlsModule.LineStyleType.Thin;

    const outputFileName = 'AddEdgeBorders.xlsx';
    workbook.SaveToFile({ fileName: outputFileName, version: xlsModule.ExcelVersion.Version2010 });
    workbook.Dispose();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.spreadsheetml.sheet' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add or Remove Cell Borders</h1>
      <button onClick={addEdgeBorders}>Set the four edges and a diagonal</button>
    </div>
  );
}

export default App;
The effect of styling the four edges of a cell and adding a diagonal line:
Remove the borders of a cell or a cell range
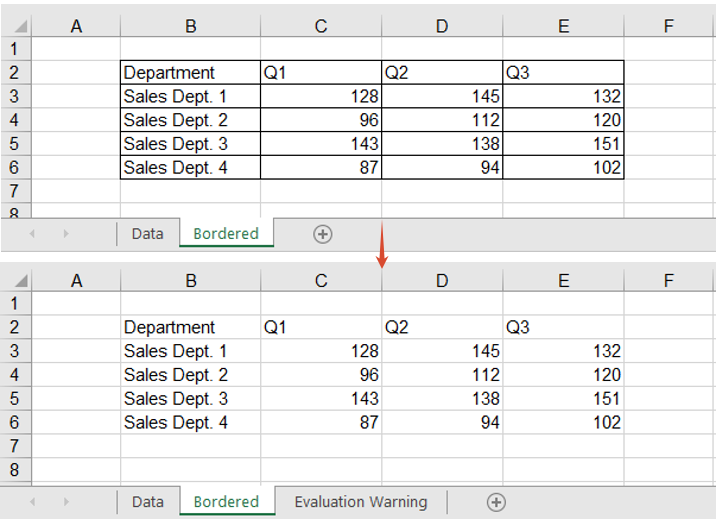
When an internal report goes out to a customer, or its data is fed to a downstream system, borders are often just noise: they make the data look like a finished report, and a parser that walks the sheet region by region can pick them up as content. Removing them is as simple as setting them — assign LineStyleType.None to the range's Borders.LineStyle and every line inside it goes at once.
The steps are:
- Take the worksheet that holds the framed report
- Take the cell range to clean up with
Range.get - Set the range's
Borders.LineStyletoLineStyleType.None, clearing every border inside it
function App() {
  const removeBorders = async () => {
    const xlsModule = window.wasmModule?.spirexls;
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'CellBorders.xlsx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}data/`);

    const workbook = new xlsModule.Workbook();
    workbook.LoadFromFile({ fileName: inputFileName });

    // The second worksheet holds the same report, already framed with borders
    const sheet = workbook.Worksheets.get(1);

    // Set every border in the B2:E6 range to None
    sheet.Range.get('B2:E6').Borders.LineStyle = xlsModule.LineStyleType.None;

    const outputFileName = 'RemoveBorders.xlsx';
    workbook.SaveToFile({ fileName: outputFileName, version: xlsModule.ExcelVersion.Version2010 });
    workbook.Dispose();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.spreadsheetml.sheet' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add or Remove Cell Borders</h1>
      <button onClick={removeBorders}>Remove cell borders</button>
    </div>
  );
}

export default App;
The effect of clearing every border inside the range:
FAQ
Setting a top edge on a whole range puts a line above every row
Cause: Borders.get(BordersLineType.EdgeTop) returns the top edge of every cell in the range, not the outline of the range itself. Used on B2:E6 as it stands, every row inside the range gets a top edge of its own, so four extra lines appear in the middle of the table.
Solution: narrow the range to a single row or column, and the edge that comes back sits on the outline. Take the top from the first row, the bottom from the last row, the left from the first column and the right from the last column:
// Top: the first row only
sheet.Range.get('B2:E2').Borders.get(xlsModule.BordersLineType.EdgeTop).LineStyle = xlsModule.LineStyleType.Thin;
// Bottom: the last row only
sheet.Range.get('B6:E6').Borders.get(xlsModule.BordersLineType.EdgeBottom).LineStyle = xlsModule.LineStyleType.Thin;
// Left: the first column only
sheet.Range.get('B2:B6').Borders.get(xlsModule.BordersLineType.EdgeLeft).LineStyle = xlsModule.LineStyleType.Thin;
// Right: the last column only
sheet.Range.get('E2:E6').Borders.get(xlsModule.BordersLineType.EdgeRight).LineStyle = xlsModule.LineStyleType.Thin;
BorderInside throws when it is called on a single cell
Cause: BorderInside means "the separators inside the range", and a single cell has no inside, so passing one throws This method doesn't support for single cell. No result file is written either.
Solution: use BorderAround to frame a single cell, or set its edges one at a time as in the previous section:
sheet.Range.get('B2').BorderAround({ borderLine: xlsModule.LineStyleType.Thin });
Get a Free License
Spire.XLS for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
A product rename, a wording change, a company name typed wrong in a template — edits like these are awkward once they land in a PDF. When the source document is not at hand, the only options are to export the whole page as an image and lay text over it, or to delete the original text in a reader and type a replacement in by hand. Contracts and manuals make this worse: the same name can be scattered across body text, bullet lists and closing notes, and fixing each one by hand is slow and easy to miss.
Spire.PDF for JavaScript loads, edits and saves PDF documents in the browser on WebAssembly, so a rename is only a matter of locating the text and writing it back, with files read and written through a virtual file system (VFS) and no backend involved. The four sections below cover replacing the first match, replacing every match (together with three switches: recoloring, match mode and replacement area), covering the original word with a background color, and drawing a rectangle over the original before redrawing the new word. In the sample the old and new names are the same length, so the layout does not shift after replacement.
This article covers four core features:
- Replace the First Match
- Replace All Matches
- Replace by Covering
- Draw a Rectangle to Cover the Original and Redraw the Text
For installation and project configuration, see Integrate Spire.PDF for JavaScript into a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Replace the First Match
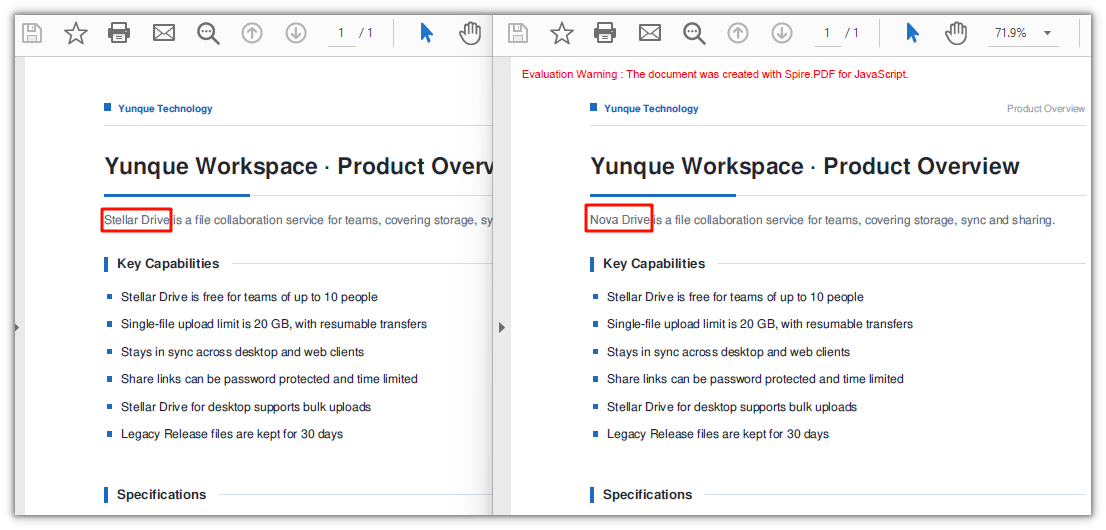
Spire.PDF for JavaScript provides the PdfTextReplacer class for turning text on a page into another piece of text. It is built per page, and ReplaceText replaces only the first match it finds, returning the number of replacements actually made (1 here); any remaining occurrences of the same name on the page are left as they are.
function App() {
  const replaceFirstMatch = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the font into the VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Load the PDF file to be processed into the VFS
    const inputFileName = 'ProductOverview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Take the first page; the replacement is limited to this page
    let page = doc.Pages.get_Item(0);

    // Create the text replacer and replace only the first match
    const replacer = new pdfModule.PdfTextReplacer(page);
    replacer.ReplaceText('Stellar Drive', 'Nova Drive');

    const outputFileName = 'ReplaceFirstMatch.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Replace the First Match</h1>
      <button onClick={replaceFirstMatch}>
        Replace
      </button>
    </div>
  );
}

export default App;
Only the first match is replaced:
Replace All Matches
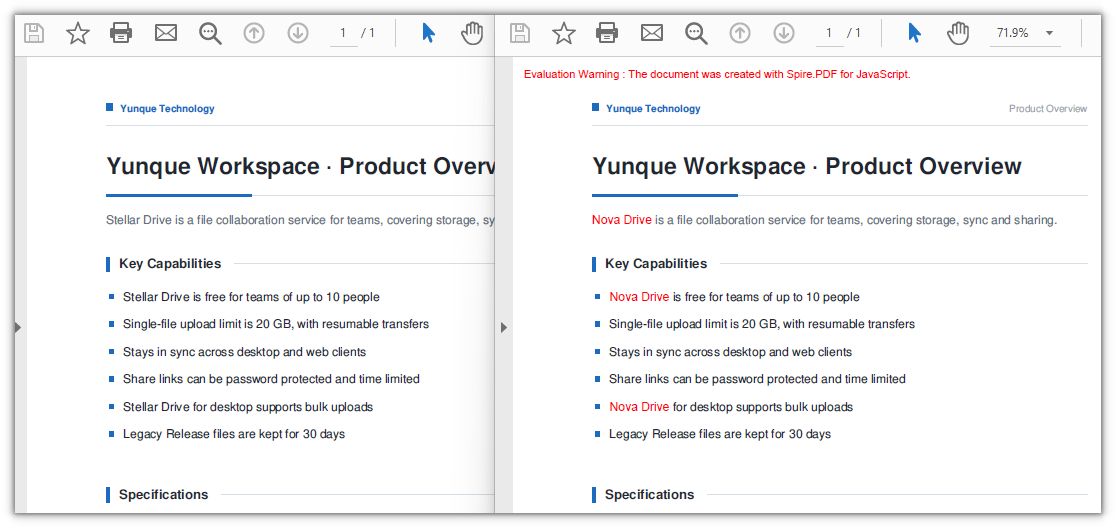
Spire.PDF for JavaScript also provides PdfTextReplacer.ReplaceAllText(), which swaps every matching piece of text on the page in one go. It takes the same arguments as ReplaceText and likewise returns the number of replacements. It also has a three-argument overload, ReplaceAllText(old, new, color), which recolors the text as it replaces it.
function App() {
  const replaceAllMatches = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the font into the VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Load the PDF file to be processed into the VFS
    const inputFileName = 'ProductOverview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    let page = doc.Pages.get_Item(0);

    // The third argument is a color, recoloring the new word as it is written
    const replacer = new pdfModule.PdfTextReplacer(page);
    replacer.ReplaceAllText('Stellar Drive', 'Nova Drive', pdfModule.Color.get_Red());

    const outputFileName = 'ReplaceAllMatches.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Replace All Matches</h1>
      <button onClick={replaceAllMatches}>
        Replace
      </button>
    </div>
  );
}

export default App;
All old name are replaced, and the new name is recolored red at the same time:
Beyond recoloring,
PdfTextReplacer.Optionshas two more switches.ReplaceTypedecides what counts as a match: by default only an identical string is accepted, and it can be switched toIgnoreCase,WholeWordorRegex.SetReplacementArealimits the replacement to a rectangle, whichPdfTextFindercan work out first:
const replacer = new pdfModule.PdfTextReplacer(page);
// Ignore case
replacer.Options.ReplaceType = pdfModule.ReplaceActionType.IgnoreCase;

// Limit the replacement to a rectangle
const finds = new pdfModule.PdfTextFinder(page).Find('Stellar Drive');
replacer.Options.SetReplacementArea(finds.get(0).Bounds[0]);

// Call it once the options are set
const count = replacer.ReplaceAllText('Stellar Drive', 'Nova Drive');
Replace by Covering
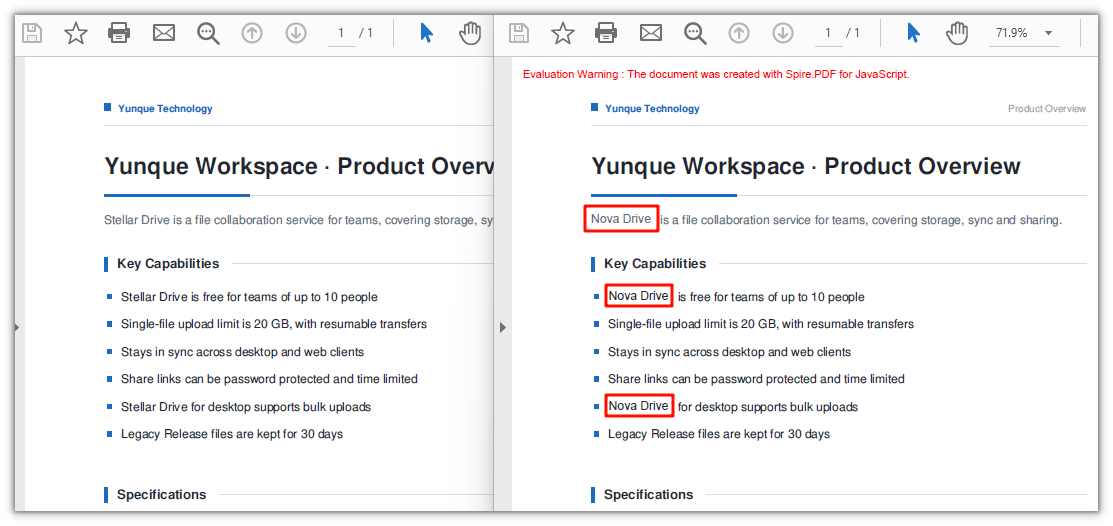
Spire.PDF for JavaScript also provides PdfTextFragment.ApplyRecoverString(), which covers a located piece of text in place: it lays a background color over the original and then writes the new text in the same position. It spares you from working out coordinates and redrawing by hand. The price is that only the background color can be chosen: the new text is drawn with the font resolved from the VFS and keeps the original foreground color, and with a white background the seam is invisible. When the font and the color need to change as well, see the redrawing approach in the next section.
function App() {
  const replaceByCovering = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the fonts used by the document into the VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Load the PDF file to be processed into the VFS
    const inputFileName = 'ProductOverview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    let page = doc.Pages.get_Item(0);

    // Locate the target text with a finder first
    const finder = new pdfModule.PdfTextFinder(page);
    const finds = finder.Find('Stellar Drive');

    // Cover each hit in turn: the second argument is the background color,
    // and the third one, true, writes the new text as Unicode
    for (let i = 0; i < finds.length; i++) {
      finds.get(i).ApplyRecoverString('Nova Drive', pdfModule.Color.get_White(), true);
    }

    const outputFileName = 'RecoverReplace.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Replace by Covering</h1>
      <button onClick={replaceByCovering}>
        Replace
      </button>
    </div>
  );
}

export default App;
A document where the original text is covered with a white background and the new word is written in its place:
Draw a Rectangle to Cover the Original and Redraw the Text
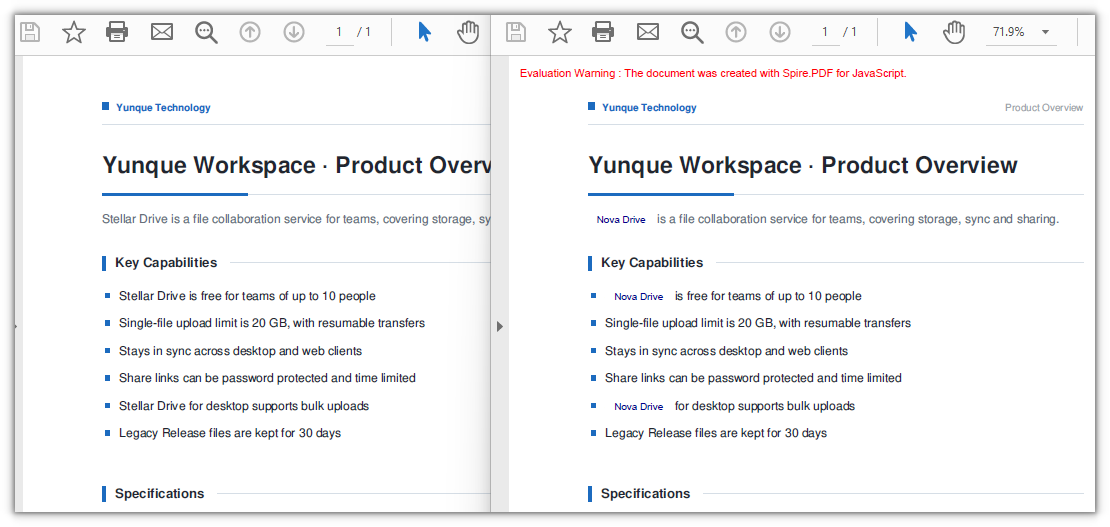
The first three sections all work on the text layer. This one takes a different tack: use PdfTextFinder to get the position of the keyword, draw a white rectangle to cover the original text, and then write the new text inside that rectangle. Compared with ApplyRecoverString, the extra freedom is that you choose the font, size and color yourself.
function App() {
  const replaceByDrawing = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the font into the VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Load the PDF file to be processed into the VFS
    const inputFileName = 'ProductOverview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    let page = doc.Pages.get_Item(0);

    // Locate the target text with a finder first
    const finder = new pdfModule.PdfTextFinder(page);
    const finds = finder.Find('Stellar Drive');

    // The white rectangle that covers the original, plus the new word's font and color
    const white = pdfModule.PdfBrushes.get_White();
    const FONT_SIZE = 9;
    const font = new pdfModule.PdfTrueTypeFont({ fontFile: '/Library/Fonts/ARIAL.TTF', size: FONT_SIZE });
    const brush = new pdfModule.PdfSolidBrush({ pdfRGBColor: new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_DarkBlue() }) });

    // Turn LineLimit off so the text is not clipped to the box
    const format = new pdfModule.PdfStringFormat();
    format.LineLimit = false;
    // Set the alignment of the text
    format.Alignment = pdfModule.PdfTextAlignment.Center;
    format.LineAlignment = pdfModule.PdfVerticalAlignment.Middle;

    for (let i = 0; i < finds.length; i++) {
      const rec = finds.get(i).Bounds[0];

      // Cover the original text with a white rectangle first
      page.Canvas.DrawRectangle({ brush: white, rectangle: rec });

      // Write the new word straight into the hit box
      page.Canvas.DrawString({ s: 'Nova Drive', font: font, brush: brush, layoutRectangle: rec, format: format });
    }

    const outputFileName = 'DrawRectangleAndText.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Draw a Rectangle to Cover the Original and Redraw the Text</h1>
      <button onClick={replaceByDrawing}>
        Replace
      </button>
    </div>
  );
}

export default App;
A document where a white rectangle covers the original text and the new word is written directly inside the hit box:
FAQ
The old name can still be found and copied after replacement
Cause: ApplyRecoverString is a visual-layer operation — it lays a background color over the original text and draws the new word on top, while the original text object stays in the text layer, so searching or copying in a reader still returns the old name. Measured on the covering replacement, the occurrence count of the old word is unchanged while the new word gains four hits.
Fix: When a real replacement at the content level is needed, switch to PdfTextReplacer; in its output the old word disappears from the text layer and the new word enters it. Measured, the four occurrences of the old word drop to 0 and the new word rises from 1 to 5:
// Content-level replacement: the old text no longer remains
const replacer = new pdfModule.PdfTextReplacer(page);
replacer.ReplaceAllText('Stellar Drive', 'Nova Drive');
Following the official sample's white rectangle plus DrawString redraw, the white background appears but the new text does not
Cause: The official sample follows the same approach as the fourth section here — locate the position with PdfTextFinder, draw a white rectangle to cover the original text, then paint the new text with Canvas.DrawString. The white rectangle is fine, but the redraw step has a trap:
- The rectangle overload of
DrawStringis governed byPdfStringFormat.LineLimit, which defaults totrueand clips the text to the box; the hit box hugs the glyphs tightly, so if its height is 11 points (exactly the font size) it cannot hold a full line height, and the whole line is clipped away — the new text appears neither on the page nor in the text layer.
Fix: Pass a PdfStringFormat with LineLimit turned off and the hit box can be used as the layout box as it is (which is what the fourth section does).
const format = new pdfModule.PdfStringFormat();
format.LineLimit = false;

page.Canvas.DrawString({ s: 'Nova Drive', font: font, brush: brush, layoutRectangle: rec, format: format });
Get a Free License
If you want to remove the evaluation message from the result document, or get past the feature limits, contact sales for a 30-day temporary license.
Many printers and print services only speak PCL (Printer Command Language). When the contract or manual at hand is a PDF, the old routes were to install a driver and save the file under a new format from desktop software, or to hand the file to a server that does the conversion — the first cannot be folded into a web workflow, and the second means the document leaves the user's device.
This article shows how to convert a PDF to PCL with Spire.PDF for JavaScript. Built on WebAssembly, it loads and saves PDF documents directly in the browser, so the whole conversion stays local and files are read and written through a virtual file system (VFS) with no backend service required.
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The following example assumes Spire.PDF is installed and the WebAssembly module has been initialized.
Convert PDF to PCL
To hand a document to a print pipeline that only accepts PCL, use PdfDocument.SaveToFile to write the whole document out as a PCL file — pass FileFormat.PCL as the second argument and the output is HP-PCL XL (PCL6).
function App() {
  const convertPdfToPcl = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // The conversion needs the Arial Unicode MS font, load it into the VFS first
    await window.spire.FetchFileToVFS('ARIAL UNICODE MS.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Load the PDF file to be converted into the VFS
    const inputFileName = 'Business_Data_Overview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Define the output file name
    const outputFileName = 'Business_Data_Overview.pcl';

    // Load the PDF document and pass FileFormat.PCL to write out a PCL file
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);
    doc.SaveToFile(outputFileName, pdfModule.FileFormat.PCL);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/octet-stream' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF to PCL</h1>
      <button onClick={convertPdfToPcl}>
        Start Converting
      </button>
    </div>
  );
}

export default App;
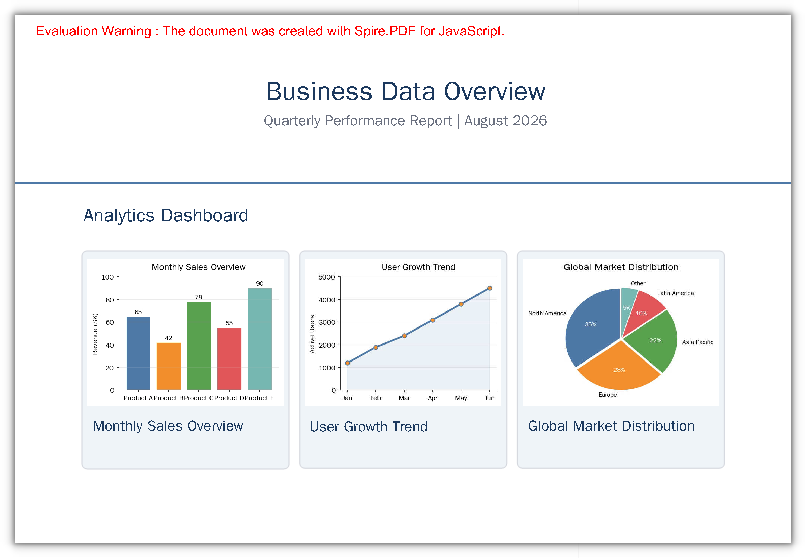
The generated PCL file, whose header states the PCL-XL language:
FAQ
The output file name ends with .pcl, so why is the file still a PDF
Reason: The single-argument overload SaveToFile(fileName) always writes in PDF format — the extension takes no part in deciding the format, so a file whose name ends with .pcl still comes out as a document whose content is PDF.
Solution: Pass the output format explicitly as the second argument:
// Single argument: writes PDF
doc.SaveToFile(outputFileName);

// FileFormat.PCL: writes a real PCL file
doc.SaveToFile(outputFileName, pdfModule.FileFormat.PCL);
What to do about Cannot found font(Arial) installed on the system.
Reason: Converting to PCL means turning the text on the page into font subsetting instructions a printer can read, and the converter looks for fonts in /Library/Fonts/ in the virtual file system — an empty directory raises this error.
Solution: Send the font into the VFS before loading the PDF:
// Placed before LoadFromFile, the font is already in the VFS when the conversion runs
await window.spire.FetchFileToVFS('ARIAL UNICODE MS.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
What format is the generated PCL file, and how do I open it
Reason: The output is PCL-XL (PCL6), and the file begins with ESC%-12345X@PJL ENTER LANGUAGE = PCLXL, followed by binary HP-PCL XL;2;0 data. It is not text, so opening it in an editor only shows garbage.
Solution: Hand it straight to a printer or print service that supports PCL; there is no need to open it by hand. To confirm the format is right, read the PJL declaration at the start of the file.
Get a Free License
If you wish to remove the evaluation message from the result document or remove feature limitations, please contact sales to obtain a temporary license valid for 30 days.
Convert PDF to Grayscale or Linearized PDF in React with JavaScript
2026-09-28 06:50:39 Written by Nina TangColor documents burn ink when printed, and once filed away that color is of no use; a PDF also stores its objects in the order they were written, so a reader has to download the whole file before it can render the first page — open a manual that runs to tens of megabytes and you stare at a blank screen first. Both jobs used to need desktop software, one file at a time, with no way into a web workflow.
This article uses Spire.PDF for JavaScript to convert PDF documents into grayscale and into linearized PDF files. Grayscaling changes the colors on the page, while linearization only changes how the objects are arranged inside the file, so the two do not affect each other. The library is built on WebAssembly and loads, modifies and saves PDF documents directly in the browser, reading and writing files through a virtual file system (VFS) with no backend service required.
This article covers two core features:
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The following examples assume Spire.PDF is installed and the WebAssembly module has been initialized.
Convert PDF to Grayscale
Grayscaling a document before printing or archiving saves color ink. Pass the input file to the PdfGrayConverter constructor and call ToGrayPdf to write out the grayscale document — the color images on the page are re-encoded as grayscale, and the text stays searchable.
function App() {
  const convertToGrayscale = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be converted into the VFS
    const inputFileName = 'Business_Data_Overview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Define the output file name
    const outputFileName = 'GrayscaleDocument.pdf';

    // Construct the grayscale converter from the input file and write out the grayscale document
    const converter = new pdfModule.PdfGrayConverter({ filePath: inputFileName });
    converter.ToGrayPdf({ filePath: outputFileName });
    converter.Dispose();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF to Grayscale</h1>
      <button onClick={convertToGrayscale}>
        Start Converting
      </button>
    </div>
  );
}

export default App;
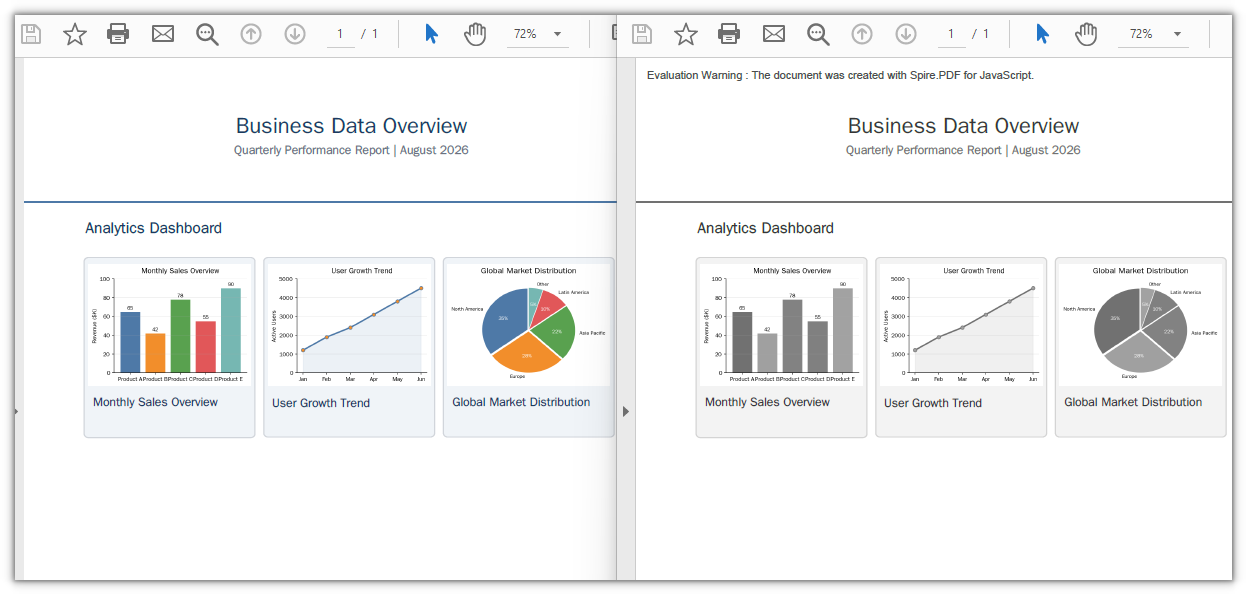
The sample document after grayscaling, with the color charts turned to grayscale
Linearize a PDF
Linearization is what fast web view is built on: a reader does not have to wait for the whole file to arrive before it renders the first page. The usage is the same as in the first feature — pass the input file to the PdfToLinearizedPdfConverter constructor and call ToLinearizedPdf to write out the result, and the document keeps its appearance and content unchanged.
function App() {
  const convertToLinearized = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be converted into the VFS
    const inputFileName = 'Business_Data_Overview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Define the output file name
    const outputFileName = 'LinearizedDocument.pdf';

    // Construct the linearization converter from the input file and write out the linearized document
    const converter = new pdfModule.PdfToLinearizedPdfConverter({ filePath: inputFileName });
    converter.ToLinearizedPdf({ filePath: outputFileName });
    converter.Dispose();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Linearize a PDF</h1>
      <button onClick={convertToLinearized}>
        Start Converting
      </button>
    </div>
  );
}

export default App;
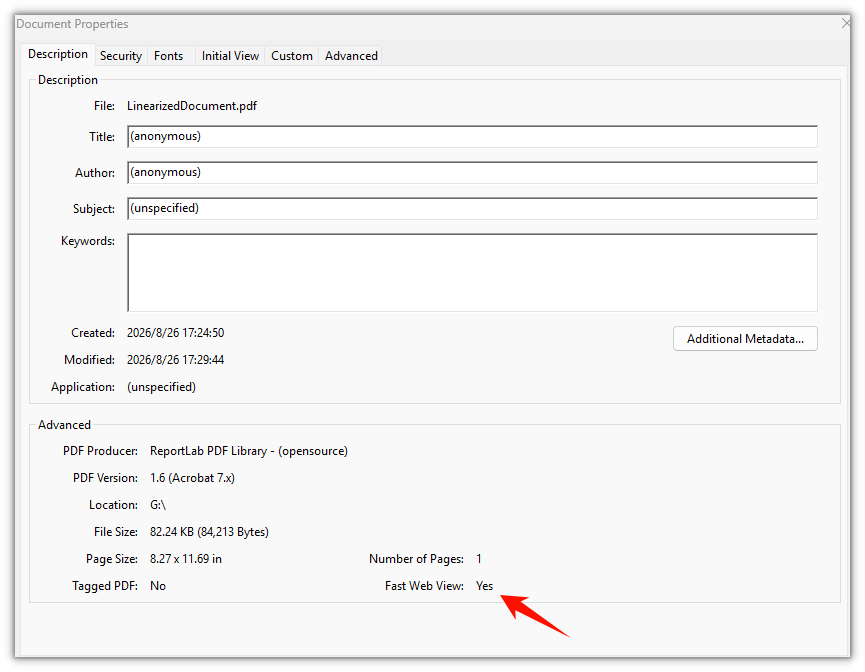
The linearized document looks no different on the page, the change is inside the file structure
FAQ
Why does the converted document contain an extra Evaluation Warning line
Reason: An unlicensed Spire.PDF inserts a line Evaluation Warning : The document was created with Spire.PDF for JavaScript. into the output document. It is appended per call — convert the same file twice and the warning appears twice.
Solution: Request a temporary 30-day license and the output document no longer carries the warning. See "Get a Free License" at the end of this article.
Why is the grayscale file smaller
Reason: Grayscaling works by re-encoding color images as single-channel DeviceGray images, and the space they take drops along with the channel count. The color images in the sample document were 3-channel PNGs totaling about 66 KB, and come out at about 31 KB; the whole file went from 82 KB down to 44 KB.
Solution: This is the normal result of image re-encoding and needs no extra handling. The page count and the text content are unchanged, the text is still searchable and copyable, and only the colors are rewritten.
Get a Free License
If you wish to remove the evaluation message from the result document or remove feature limitations, please contact sales to obtain a temporary license valid for 30 days.
Contracts, quotations and slide decks are often embedded straight into an Excel workbook: what you see on the sheet is an icon or a thumbnail, while the real document data sits in the xl/embeddings part of the package. Pulling those attachments out for archiving one by one means opening each object and saving a copy by hand.Spire.XLS for JavaScript does the job in the browser through WebAssembly, using a virtual file system (VFS) for the input and the output, with no backend service involved.
This article covers two feature points:
For installation and project configuration, see Integrating Spire.XLS for JavaScript in a React Project. The examples below assume Spire.XLS is installed and the WebAssembly module has finished initializing.
Read the OLE object information of a worksheet
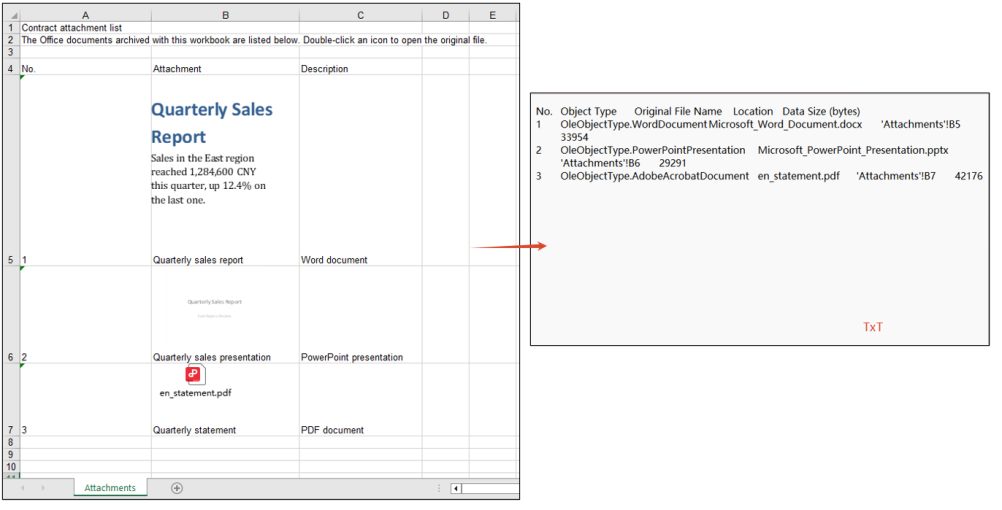
Before extracting anything it helps to know what a workbook actually carries. A listing sets out the kind, original name, cell and size of every embedded object in one place and serves as an attachment register, so archiving or handing the file over does not mean double-clicking each icon in turn.
The steps are:
- Use
HasOleObjectsto check whether the worksheet holds any embedded objects, and stop early if it does not - Walk every object of the worksheet through the
OleObjectscollection - Read four pieces of information off each object:
ObjectType: the kind of object, such asWordDocumentorPowerPointPresentationOleOriginName: the file name the object had before it was embeddedLocation: the cell the object sits on- the length of
OleData: the data size
- Join the four fields into one line per object and write the listing to
ListOleObjects.txt
The example below collects those fields into a plain text listing:
function App() {
  const listOleObjects = async () => {
    // Get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // Check if the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // Load the font and the input file into VFS
    await window.spire.FetchFileToVFS('simsun.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'OLEObjects.xlsx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}data/`);

    // Load the workbook and take the first worksheet
    const workbook = new xlsModule.Workbook();
    workbook.LoadFromFile({ fileName: inputFileName });
    const sheet = workbook.Worksheets.get(0);

    // Check whether the worksheet contains OLE objects
    if (!sheet.HasOleObjects) {
      alert('The worksheet contains no OLE objects.');
      return;
    }

    // Collect the listing as text: a header line, then one tab-separated line per object
    const lines = [['No.', 'Object Type', 'Original File Name', 'Location', 'Data Size (bytes)'].join('\t')];

    // Walk the OLE objects of the worksheet, one line per object
    let index = 1;
    for (const oleObject of sheet.OleObjects) {
      lines.push([
        index,
        String(oleObject.ObjectType),
        String(oleObject.OleOriginName),
        String(oleObject.Location.RangeAddress),
        oleObject.OleData.length,
      ].join('\t'));
      index += 1;
    }

    // Release the workbook object
    workbook.Dispose();

    // Write the listing to a text file in the VFS
    const outputFileName = 'ListOleObjects.txt';
    window.dotnetRuntime.Module.FS.writeFile(outputFileName, lines.join('\n'));

    // Read the result file from VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/plain;charset=utf-8' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>List OLE Objects</h1>
      <button onClick={listOleObjects}>List OLE objects</button>
    </div>
  );
}

export default App;
The effect of reading the OLE object information:
Extract OLE object payloads by type
A listing only says what is embedded; archiving the attachment itself means getting the document out. An OLE object carries its payload as a byte array, so writing those bytes out restores the document exactly as it was embedded, with no re-typesetting or format conversion.
The steps are:
- Use
HasOleObjectsto confirm the worksheet holds embedded objects - Walk every object in the
OleObjectscollection and decide the name and MIME type of the output file fromObjectType - Take the raw bytes of the object through
OleData, write them into the virtual file system, read them back and wrap them in a downloadable Blob - Dispose of the workbook once the walk is done, then trigger the downloads one by one
The example below walks every object of the worksheet and writes the Word, PowerPoint and PDF attachments out as .docx, .pptx and .pdf files, offering each one for download:
function App() {
  const extractOleObjects = async () => {
    // Get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // Check if the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // Load the font and the input file into VFS
    await window.spire.FetchFileToVFS('simsun.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'OLEObjects.xlsx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}data/`);

    // Load the workbook and take the first worksheet
    const workbook = new xlsModule.Workbook();
    workbook.LoadFromFile({ fileName: inputFileName });
    const sheet = workbook.Worksheets.get(0);

    // Collect the extracted files so the page can offer them for download
    const results = [];

    // Walk the OLE objects of the worksheet and write each one out in its own format
    if (sheet.HasOleObjects) {
      for (const oleObject of sheet.OleObjects) {
        const type = oleObject.ObjectType;
        let outputFileName = '';
        let mimeType = '';

        // Word document
        if (type === xlsModule.OleObjectType.WordDocument) {
          outputFileName = 'ExtractWord.docx';
          mimeType = 'application/vnd.openxmlformats-officedocument.wordprocessingml.document';
        }
        // PowerPoint presentation: .pptx and .sldx fall under two different enum members
        else if (
          type === xlsModule.OleObjectType.PowerPointPresentation ||
          type === xlsModule.OleObjectType.PowerPointSlide
        ) {
          outputFileName = 'ExtractPowerPoint.pptx';
          mimeType = 'application/vnd.openxmlformats-officedocument.presentationml.presentation';
        }
        // PDF document
        else if (type === xlsModule.OleObjectType.AdobeAcrobatDocument) {
          outputFileName = 'ExtractPdf.pdf';
          mimeType = 'application/pdf';
        }

        // Any other type is left alone
        if (!outputFileName) continue;

        // Write the raw data of the object into the virtual file system
        window.dotnetRuntime.Module.FS.writeFile(outputFileName, oleObject.OleData);
        const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
        results.push({
          name: outputFileName,
          url: URL.createObjectURL(new Blob([fileArray], { type: mimeType })),
        });
      }
    }

    // Release the workbook object
    workbook.Dispose();

    // Trigger the downloads one by one
    results.forEach(({ name, url }) => {
      const a = document.createElement('a');
      a.href = url;
      a.download = name;
      a.click();
      URL.revokeObjectURL(url);
    });
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Extract OLE Objects</h1>
      <button onClick={extractOleObjects}>Extract OLE objects by type</button>
    </div>
  );
}

export default App;
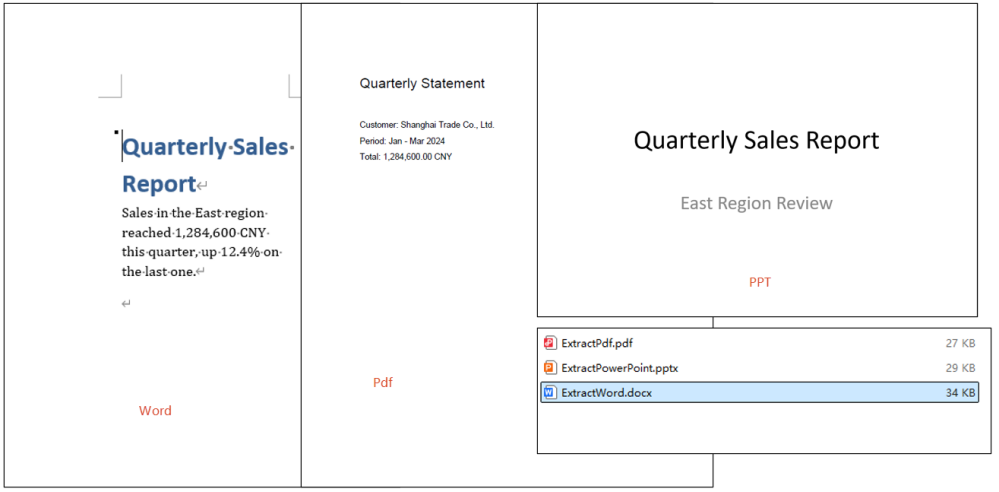
The effect of extracting the attachment documents:
FAQ
OleObjectType.PowerPointSlide never matches a PowerPoint attachment
Cause: OleObjectType splits objects by the real format of the embedded file. A .pptx presentation reports PowerPointPresentation; only slideshow formats such as .sldx and .ppt land on PowerPointSlide, so testing for the latter alone misses the vast majority of PowerPoint attachments.
Solution: match both enum members in the branch, for example:
else if (
  type === xlsModule.OleObjectType.PowerPointPresentation ||
  type === xlsModule.OleObjectType.PowerPointSlide
) {
  outputFileName = 'ExtractPowerPoint.pptx';
}
Only the attachments of the first worksheet come out
Cause: OleObjects is a per-worksheet collection. The example takes the first sheet through Worksheets.get(0) and walks the OleObjects of that sheet alone, so objects embedded on any other worksheet are never visited. When the attachments are spread over several sheets, the extraction silently comes up short, with no error to show for it.
Solution: walk the worksheets instead, taking the OleObjects of each one in turn:
for (let i = 0; i < workbook.Worksheets.Count; i++) {
  const worksheet = workbook.Worksheets.get(i);
  for (const oleObject of worksheet.OleObjects) {
    // write the attachment out by type
  }
}
Get a Free License
Spire.XLS for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Once a table has been turned into a PDF, the data is sealed up together with the layout. Send the same document to ten people and what comes back is ten separately filled-in PDFs; to move the contents of one onto a different template, the only way is to copy it off the screen one field at a time. The form fields themselves do have names and the values do hang off those names, but as soon as you leave a reader, that structure can no longer be pulled back out.
This article uses Spire.PDF for JavaScript to export the values in a form's fields to a data file, then import that data file back into a blank form. ExportData and ImportData both support Xml, Fdf, and XFdf — the three are nothing more than a difference of DataFormat enum values, called in exactly the same way, differing only in the structure of the file written out. The code below runs the whole flow with XML, with the FDF and XFDF versions listed alongside in comments; uncomment to switch. Spire.PDF for JavaScript reads and writes documents in the browser on top of WebAssembly, so the whole process happens locally, going through a virtual file system (VFS) to read and write files, with no backend involved.
This article covers two core features:
For installation and project configuration, see Integrate Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Export PDF Form Data
PdfFormWidget.ExportData writes the values in a form's fields out to a single data file, with the format given by the second parameter, DataFormat. The three formats hold the same set of field values; they differ in file structure:
| Data format | File structure |
|---|---|
DataFormat.Xml |
Adobe form data XML — the field name is the element name, the value is the element content |
DataFormat.Fdf |
Forms Data Format (FDF) — a text structure starting with %FDF-, where /T holds the field name and /V the value |
DataFormat.XFdf |
XFDF, standard XML — one <field name="…"> per field, with the value inside <value> |
The third parameter is the form name; for an unnamed AcroForm, pass an empty string.
function App() {
  const exportFormData = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be exported into the VFS
    const inputFileName = 'CustomerInformationForm.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    const doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Build a PdfFormWidget from the document's form handle to reach the data export API
    const formWidget = new pdfModule.PdfFormWidget(doc.Form.H);

    // This demo exports XML
    const dataFiles = [
      { fileName: 'FormData.xml', format: pdfModule.DataFormat.Xml },
      // { fileName: 'FormData.fdf', format: pdfModule.DataFormat.Fdf },
      // { fileName: 'FormData.xfdf', format: pdfModule.DataFormat.XFdf },
    ];

    for (const item of dataFiles) {
      // The third parameter is the form name; pass an empty string for an unnamed form
      formWidget.ExportData(item.fileName, item.format, '');
    }
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    for (const item of dataFiles) {
      const fileArray = window.dotnetRuntime.Module.FS.readFile(item.fileName);
      const blob = new Blob([fileArray], { type: 'application/octet-stream' });
      const url = URL.createObjectURL(blob);
      const a = document.createElement('a');
      a.href = url;
      a.download = item.fileName;
      a.click();
      URL.revokeObjectURL(url);
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Export Form Data</h1>
      <button onClick={exportFormData}>
        Export
      </button>
    </div>
  );
}

export default App;
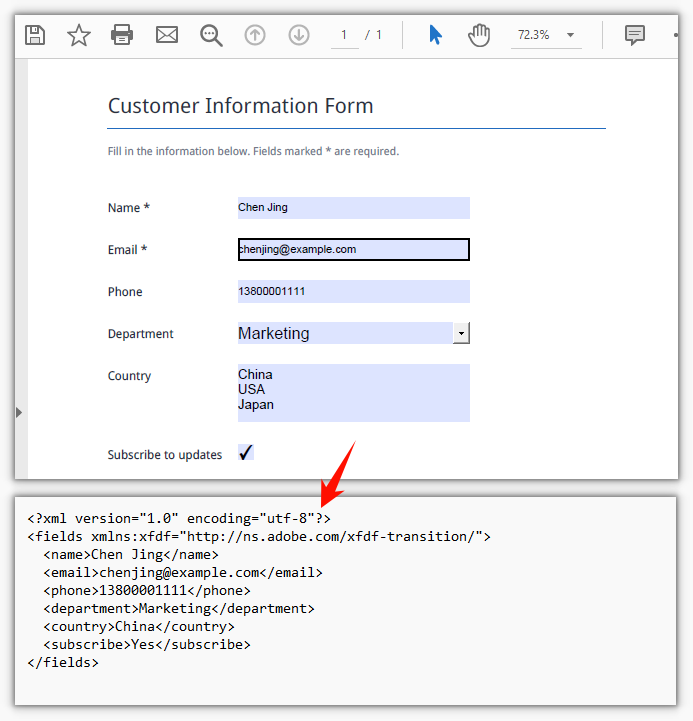
The exported XML form data file:
Import PDF Form Data
PdfFormWidget.ImportData reads a data file and writes the values back into the form fields by field name; the second parameter, DataFormat, only determines how the file is parsed and has nothing to do with the file extension — the same for all three formats.
What gets imported is the blank form. The template goes out empty, and once the data files come back the values are filled in one by one — with a lot of fields there is no need to key everything in a second time.
function App() {
  const importFormData = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the blank form to be filled into the VFS
    const inputFileName = 'BlankCustomerInformationForm.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // This demo refills from the XML data file
    const dataFiles = [
      { fileName: 'FormData.xml', format: pdfModule.DataFormat.Xml, outputFileName: 'ImportedXMLData.pdf' },
      // { fileName: 'FormData.fdf', format: pdfModule.DataFormat.Fdf, outputFileName: 'ImportedFDFData.pdf' },
      // { fileName: 'FormData.xfdf', format: pdfModule.DataFormat.XFdf, outputFileName: 'ImportedXFDFData.pdf' },
    ];

    for (const item of dataFiles) {
      // The data file also has to be loaded into the VFS first
      await window.spire.FetchFileToVFS(item.fileName, "", `${process.env.PUBLIC_URL}/data/`);

      const doc = new pdfModule.PdfDocument();
      doc.LoadFromFile(inputFileName);

      // Read the data file and write the values back into the fields by name
      const formWidget = new pdfModule.PdfFormWidget(doc.Form.H);
      formWidget.ImportData(item.fileName, item.format);

      doc.SaveToFile(item.outputFileName);
      doc.Close();

      // Read the generated file from the VFS and trigger the download
      const fileArray = window.dotnetRuntime.Module.FS.readFile(item.outputFileName);
      const blob = new Blob([fileArray], { type: 'application/pdf' });
      const url = URL.createObjectURL(blob);
      const a = document.createElement('a');
      a.href = url;
      a.download = item.outputFileName;
      a.click();
      URL.revokeObjectURL(url);
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Import Form Data</h1>
      <button onClick={importFormData}>
        Import
      </button>
    </div>
  );
}

export default App;
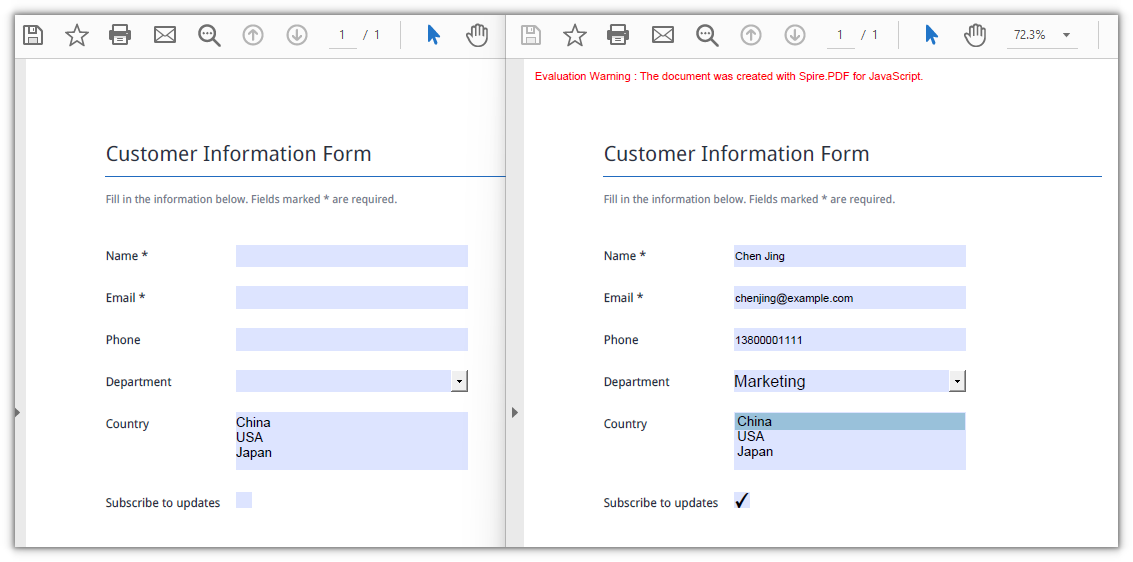
The form after the XML data has been imported:
FAQ
Some fields are still empty after import
Cause: Import matches by field name, so the names in the data file have to be exactly the same as the field names in the form, case and spaces included. A field that doesn't match is skipped outright — no error and no return value saying so; only the fields that do match get a value.
Solution: Walk the field collection first and print out the real names, then check the data file against them:
const fields = formWidget.FieldsWidget;
for (let i = 0; i < fields.Count; i++) {
  console.log(fields.get_Item({ index: i }).Name);
}
Which of the three data formats should you choose
Cause: All three hold the same field values; the difference is structure and tool support. Fdf is the smallest, starts with %FDF-, and suits passing data between form programs only; XFdf and Xml are both XML, so they can be opened and read directly and diffed with text tools, which makes them safer for moving between tools; Xml puts the field name right in the element name, the most straightforward structure of the three.
Solution: Use Fdf for round trips inside a program; use XFdf when the file goes into version control, needs a human eye, or has to talk to another system; use Xml when all you need is a readable list of field names and values.
Import throws Xml_MessageWithErrorPosition or "not a valid FDF file"
Cause: ImportData parses the file as whatever format the second parameter names, and never looks at the extension. When the content doesn't match the format, it fails at the first step: XML reports Xml_MessageWithErrorPosition, Xml_InvalidRootData, and a non-FDF file reports The source is not a valid FDF file because it does not start with "%FDF-".
Solution: Pass the DataFormat that matches the file's real format, and use the original exported data file rather than another format after re-saving it.
Get a Free License
If you want to remove the evaluation message from the result document, or to get rid of the feature limitations, contact sales for a temporary license valid for 30 days.
A form-based PDF keeps its whole value in what was filled in, but once the file is filed away or handed over, that data is locked inside the layout. To find out what a field holds you have to open a reader and copy it out one by one; with a few dozen fields, transcribing by hand is slow and easy to get wrong. Before those values can be validated, imported into a database, or used to track an order, the program has to be able to read them out first.
This article shows how to extract form field values from an existing PDF with Spire.PDF for JavaScript: walk the field collection, determine each field's type, then read the current value of each text box, list box, combo box, radio button, and check box by type. Spire.PDF for JavaScript is built on WebAssembly and opens and parses documents in the browser, so the whole read happens locally. Files are read and written through a virtual file system (VFS), with no backend involved.
This article covers one core feature:
For installation and project configuration, see Integrate Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Extract All Form Field Values
Spire.PDF for JavaScript provides PdfFormWidget to take over the form fields already present in a document; FieldsWidget is its field collection, and fields can be pulled out one by one by index. The value properties are not uniform across field types: a text box keeps its value on Text, a check box is judged by Checked, list boxes and combo boxes split into an option collection and a selected value, and a radio button is read straight from Value. So once a field is in hand, dispatch on its type and then read the matching value, writing the type name into the result alongside it — you never need to know in advance which fields the document contains.
function App() {
  const getAllFieldValues = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be read into the VFS
    const inputFileName = 'ApplicationForm.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    const doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Build a PdfFormWidget from the document's form handle; FieldsWidget is its field collection
    const formWidget = new pdfModule.PdfFormWidget(doc.Form.H);
    const fields = formWidget.FieldsWidget;

    let report = '';

    // Walk the field collection, check each type, and read the matching value
    for (let i = 0; i < fields.Count; i++) {
      const field = fields.get_Item({ index: i });

      // Both the type name and the value are filled in by the type dispatch
      let type = 'Unknown';
      let value = '(Unrecognized field type)';

      if (field instanceof pdfModule.PdfTextBoxFieldWidget) {
        // Text box field: read Text directly
        type = 'TextBox';
        value = field.Text;
      } else if (field instanceof pdfModule.PdfListBoxWidgetFieldWidget) {
        // List box field: Values holds every option, SelectedValue is the current one
        const options = [];
        for (let j = 0; j < field.Values.Count; j++) {
          options.push(field.Values.get_Item(j).Value);
        }
        type = 'ListBox';
        value = `Selected ${field.SelectedValue}, options ${options.join(', ')}`;
      } else if (field instanceof pdfModule.PdfComboBoxWidgetFieldWidget) {
        // Combo box field: like a list box, it has an option collection and a selected value
        const options = [];
        for (let j = 0; j < field.Values.Count; j++) {
          options.push(field.Values.get_Item(j).Value);
        }
        type = 'ComboBox';
        value = `Selected ${field.SelectedValue}, options ${options.join(', ')}`;
      } else if (field instanceof pdfModule.PdfRadioButtonListFieldWidget) {
        // Radio button field: Value is the selected item
        type = 'RadioButton';
        value = `Selected ${field.Value}`;
      } else if (field instanceof pdfModule.PdfCheckBoxWidgetFieldWidget) {
        // Check box field: Checked gives the state, not Value
        type = 'CheckBox';
        value = field.Checked ? 'Checked' : 'Not checked';
      }

      report += `Field "${field.Name}" (${type}): ${value}\n`;
    }

    const outputFileName = 'AllFieldValues.txt';
    window.dotnetRuntime.Module.FS.writeFile(outputFileName, report);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/plain' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Extract Form Field Values</h1>
      <button onClick={getAllFieldValues}>
        Extract values
      </button>
    </div>
  );
}

export default App;
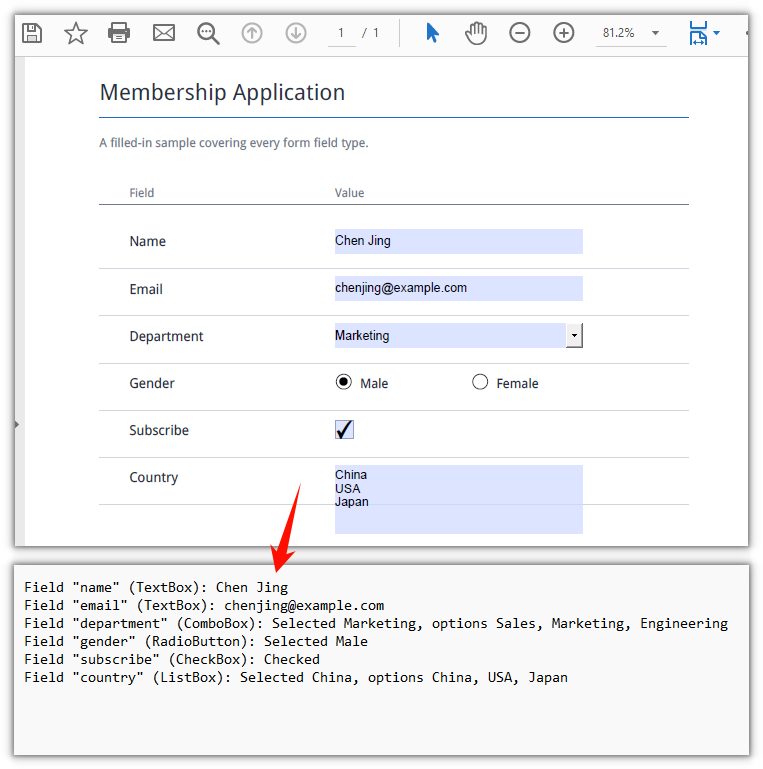
The values collected by walking every form field:
FAQ
A check box's Value doesn't give you its state
Cause: The check box widget (PdfCheckBoxWidgetFieldWidget) has no Value property — reading it gets you undefined. A check box tracks its state through export values: Off when it is not ticked, Yes or a custom export value when it is. A string value cannot tell you whether the box is checked.
Solution: Use Checked for the state:
// Check the state with Checked, not Value
const checked = field.Checked;
Should a list box or combo box be read with SelectedValue or Values
Cause: For these two fields Values is the full option set — walking it gives you every choice, and each entry is a PdfListWidgetItem whose .Value is the option text, so the item has to be unwrapped one more time; the item the user actually selected lives on SelectedValue. Treat Values as the value and what you get is not the filled-in result.
Solution: Read SelectedValue for the current value; walk Values only when you need to show the available range:
// The text of the currently selected item
const selected = field.SelectedValue;

// Every available option
const options = [];
for (let j = 0; j < field.Values.Count; j++) {
  options.push(field.Values.get_Item(j).Value);
}
Loading an encrypted PDF throws "Can not open an encrypted document. The password is invalid."
Cause: Reading a form means the document has to open first; when the document is password-protected, LoadFromFile without the password throws during loading, and no empty document comes back.
Solution: Pass the open password as the second argument to LoadFromFile:
doc.LoadFromFile(inputFileName, 'spire123');
Get a Free License
If you want to remove the evaluation message from the result document, or to get rid of the feature limitations, contact sales for a temporary license valid for 30 days.
Once a table has been turned into a PDF, the data is sealed up together with the layout. Send the same document to ten people and what comes back is ten separately filled-in PDFs; to move the contents of one onto a different template, the only way is to copy it off the screen one field at a time. The form fields themselves do have names and the values do hang off those names, but as soon as you leave a reader, that structure can no longer be pulled back out.
This article uses Spire.PDF for JavaScript to export the values in a form's fields to a data file, then import that data file back into a blank form. ExportData and ImportData both support Xml, Fdf, and XFdf — the three are nothing more than a difference of DataFormat enum values, called in exactly the same way, differing only in the structure of the file written out. The code below runs the whole flow with XML, with the FDF and XFDF versions listed alongside in comments; uncomment to switch. Spire.PDF for JavaScript reads and writes documents in the browser on top of WebAssembly, so the whole process happens locally, going through a virtual file system (VFS) to read and write files, with no backend involved.
This article covers two core features:
For installation and project configuration, see Integrate Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Export PDF Form Data
PdfFormWidget.ExportData writes the values in a form's fields out to a single data file, with the format given by the second parameter, DataFormat. The three formats hold the same set of field values; they differ in file structure:
| Data format | File structure |
|---|---|
DataFormat.Xml |
Adobe form data XML — the field name is the element name, the value is the element content |
DataFormat.Fdf |
Forms Data Format (FDF) — a text structure starting with %FDF-, where /T holds the field name and /V the value |
DataFormat.XFdf |
XFDF, standard XML — one <field name="…"> per field, with the value inside <value> |
The third parameter is the form name; for an unnamed AcroForm, pass an empty string.
function App() {
  const exportFormData = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be exported into the VFS
    const inputFileName = 'CustomerInformationForm.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    const doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Build a PdfFormWidget from the document's form handle to reach the data export API
    const formWidget = new pdfModule.PdfFormWidget(doc.Form.H);

    // This demo exports XML
    const dataFiles = [
      { fileName: 'FormData.xml', format: pdfModule.DataFormat.Xml },
      // { fileName: 'FormData.fdf', format: pdfModule.DataFormat.Fdf },
      // { fileName: 'FormData.xfdf', format: pdfModule.DataFormat.XFdf },
    ];

    for (const item of dataFiles) {
      // The third parameter is the form name; pass an empty string for an unnamed form
      formWidget.ExportData(item.fileName, item.format, '');
    }
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    for (const item of dataFiles) {
      const fileArray = window.dotnetRuntime.Module.FS.readFile(item.fileName);
      const blob = new Blob([fileArray], { type: 'application/octet-stream' });
      const url = URL.createObjectURL(blob);
      const a = document.createElement('a');
      a.href = url;
      a.download = item.fileName;
      a.click();
      URL.revokeObjectURL(url);
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Export Form Data</h1>
      <button onClick={exportFormData}>
        Export
      </button>
    </div>
  );
}

export default App;
The exported XML form data file:
Import PDF Form Data
PdfFormWidget.ImportData reads a data file and writes the values back into the form fields by field name; the second parameter, DataFormat, only determines how the file is parsed and has nothing to do with the file extension — the same for all three formats.
What gets imported is the blank form. The template goes out empty, and once the data files come back the values are filled in one by one — with a lot of fields there is no need to key everything in a second time.
function App() {
  const importFormData = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the blank form to be filled into the VFS
    const inputFileName = 'BlankCustomerInformationForm.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // This demo refills from the XML data file
    const dataFiles = [
      { fileName: 'FormData.xml', format: pdfModule.DataFormat.Xml, outputFileName: 'ImportedXMLData.pdf' },
      // { fileName: 'FormData.fdf', format: pdfModule.DataFormat.Fdf, outputFileName: 'ImportedFDFData.pdf' },
      // { fileName: 'FormData.xfdf', format: pdfModule.DataFormat.XFdf, outputFileName: 'ImportedXFDFData.pdf' },
    ];

    for (const item of dataFiles) {
      // The data file also has to be loaded into the VFS first
      await window.spire.FetchFileToVFS(item.fileName, "", `${process.env.PUBLIC_URL}/data/`);

      const doc = new pdfModule.PdfDocument();
      doc.LoadFromFile(inputFileName);

      // Read the data file and write the values back into the fields by name
      const formWidget = new pdfModule.PdfFormWidget(doc.Form.H);
      formWidget.ImportData(item.fileName, item.format);

      doc.SaveToFile(item.outputFileName);
      doc.Close();

      // Read the generated file from the VFS and trigger the download
      const fileArray = window.dotnetRuntime.Module.FS.readFile(item.outputFileName);
      const blob = new Blob([fileArray], { type: 'application/pdf' });
      const url = URL.createObjectURL(blob);
      const a = document.createElement('a');
      a.href = url;
      a.download = item.outputFileName;
      a.click();
      URL.revokeObjectURL(url);
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Import Form Data</h1>
      <button onClick={importFormData}>
        Import
      </button>
    </div>
  );
}

export default App;
The form after the XML data has been imported:
FAQ
Some fields are still empty after import
Cause: Import matches by field name, so the names in the data file have to be exactly the same as the field names in the form, case and spaces included. A field that doesn't match is skipped outright — no error and no return value saying so; only the fields that do match get a value.
Solution: Walk the field collection first and print out the real names, then check the data file against them:
const fields = formWidget.FieldsWidget;
for (let i = 0; i < fields.Count; i++) {
  console.log(fields.get_Item({ index: i }).Name);
}
Which of the three data formats should you choose
Cause: All three hold the same field values; the difference is structure and tool support. Fdf is the smallest, starts with %FDF-, and suits passing data between form programs only; XFdf and Xml are both XML, so they can be opened and read directly and diffed with text tools, which makes them safer for moving between tools; Xml puts the field name right in the element name, the most straightforward structure of the three.
Solution: Use Fdf for round trips inside a program; use XFdf when the file goes into version control, needs a human eye, or has to talk to another system; use Xml when all you need is a readable list of field names and values.
Import throws Xml_MessageWithErrorPosition or "not a valid FDF file"
Cause: ImportData parses the file as whatever format the second parameter names, and never looks at the extension. When the content doesn't match the format, it fails at the first step: XML reports Xml_MessageWithErrorPosition, Xml_InvalidRootData, and a non-FDF file reports The source is not a valid FDF file because it does not start with "%FDF-".
Solution: Pass the DataFormat that matches the file's real format, and use the original exported data file rather than another format after re-saving it.
Get a Free License
If you want to remove the evaluation message from the result document, or to get rid of the feature limitations, contact sales for a temporary license valid for 30 days.
JavaScript can generate PDF files programmatically by creating a document, adding pages, drawing text and other elements, and saving the document. In a React application, this workflow can run entirely in the browser with Spire.PDF for JavaScript and WebAssembly, without requiring a backend server.
At a high level, JavaScript PDF generation consists of five steps: create the document, add pages, add content, save the PDF, and download the generated file. This tutorial uses React as the example environment, but the PDF-generation workflow itself is JavaScript-based and applies to any frontend framework.
Here, “generating a PDF” means creating a PDF document programmatically from scratch, rather than printing an existing HTML page to PDF. JavaScript applications can generate PDFs through HTML-to-PDF conversion, canvas-based rendering, or programmatic PDF construction. This tutorial focuses on programmatic PDF generation with Spire.PDF for JavaScript.
What You Need
This tutorial assumes that Spire.PDF for JavaScript has already been installed and initialized in your React project. For setup details, see How to Integrate Spire.PDF for JavaScript in a React Project. You also need the WebAssembly resources configured so that the PDF module is available through window.spirepdf (Spire.Office for JavaScript 11.7.0 or later).
How to Generate a PDF in JavaScript
Create PdfDocument -> Add Page -> Draw Content -> Save -> Download
1. Create a PDF document
Start by creating a PdfDocument object. This is the in-memory representation of the PDF file you will build.
const pdf = window.spirepdf;
let doc = new pdf.PdfDocument();
2. Add a page
A PDF document needs at least one page. Call Pages.Add() to create a blank page with a default size.
let page = doc.Pages.Add();
3. Add text and other content
The page has a Canvas property that exposes drawing methods. Use DrawString to add text, DrawImage to add images, DrawLine to draw lines, and DrawRectangle to draw filled or outlined rectangles. Coordinates are measured in points (1 point = 1/72 inch) from the top-left corner.
let font = new pdf.PdfFont({ fontFamily: pdf.PdfFontFamily.Helvetica, size: 12 });
let brush = new pdf.PdfSolidBrush({ pdfRGBColor: new pdf.PdfRGBColor(0, 0, 0) });
page.Canvas.DrawString({ s: "Hello, World!", font: font, brush: brush, x: 50, y: 50 });
4. Save the generated PDF
Once all content is in place, call SaveToFile to write the PDF to the WebAssembly virtual file system (VFS). The VFS is an in-browser file system that Spire.PDF uses to manage input and output files without touching the real disk or a server.
doc.SaveToFile({ fileName: 'Output.pdf' });
doc.Close();
5. Download the PDF in the browser
After saving to the VFS, read the file back as a byte array, wrap it in a Blob, and trigger a download by creating a temporary anchor element. This pattern is used in every Spire.PDF for JavaScript example.
const fileArray = window.dotnetRuntime.Module.FS.readFile('Output.pdf');
const blob = new Blob([fileArray], { type: 'application/pdf' });
const url = URL.createObjectURL(blob);
const a = document.createElement('a');
a.href = url;
a.download = 'Output.pdf';
a.click();
URL.revokeObjectURL(url);
Programmatic PDF generation is useful when you need precise control over the document structure, page layout, text, graphics, or metadata. If you already have a web page or HTML template and simply need to convert that layout into a PDF, an JavaScript HTML-to-PDF workflow may be a better fit.
The next section puts these steps together in a complete example that generates a PDF from JavaScript data.
Generate an Invoice PDF from JavaScript Data
Real applications generate structured documents — invoices, reports, quotations — from application data, not hardcoded strings. In a React application, the invoice object could come from form input, component state, or an API response; the PDF generation code only needs the data needed for the document layout. This example defines an invoice as a JavaScript object and renders a print-ready PDF from it: a bleed header, a billed-to block, a line-item table, a totals cascade, and payment details. It combines DrawString, DrawRectangle, DrawLine, and PdfGrid into one complete runnable React component.
function App() {
  const generateInvoicePdf = async () => {
    // spire.office 11.7.0 hangs the engine off window.spirepdf.
    const pdf = window.spirepdf;
    if (!pdf) return alert('Spire.PDF is not ready yet');

    // ── The invoice, as data. Swap this object and the layout follows. ────
    const invoice = {
      number: 'INV-2026-0148', issued: '23 September 2026',
      due: '23 October 2026', po: 'PO-ACME-88231', terms: 'Net 30',
      seller: ['NIMBUS SOFTWARE LTD.', 'Cloud platforms for manufacturing teams',
        '12 Kingsway, London WC2B 6UN, United Kingdom'],
      buyer: ['Acme Manufacturing Co.', 'Attn: Sarah Chen, Procurement',
        '1400 Harbor Boulevard, Suite 320', 'Long Beach, CA 90802', 'United States'],
      // [description, quantity, unit price] — the amount is derived below
      items: [
        ['CloudDesk Pro — annual subscription (25 seats)', 25, 120],
        ['Implementation & onboarding (remote, 16 hours)', 16, 95],
        ['Priority support — Premium tier (12 months)', 1, 2400],
        ['Additional object storage (500 GB per year)', 1, 480],
      ],
      discountRate: 0.05, taxRate: 0.08,
      bank: ['Barclays Bank PLC · Sort code 20-00-00 · Account 5571 2043',
        'IBAN GB29 BARC 2000 0055 7120 43 · SWIFT BARCGB22'],
      remark: ['Quote the invoice number as the payment reference.',
        'Amounts unpaid after the due date accrue interest at 1.5% per month.'],
      legal:
        'Nimbus Software Ltd. · 12 Kingsway, London WC2B 6UN · VAT GB 412 8876 21 · Company No. 09882417',
      contact: 'billing@nimbussoftware.com · +44 20 7946 0812 · nimbussoftware.com',
    };

    const round = (n) => Math.round(n * 100) / 100;
    const subtotal = round(invoice.items.reduce((sum, [, qty, unit]) => sum + qty * unit, 0));
    const discount = -round(subtotal * invoice.discountRate);
    const tax = round((subtotal + discount) * invoice.taxRate);
    const total = round(subtotal + discount + tax);
    const money = (n) =>
      '$' + Math.abs(n).toLocaleString('en-US', { minimumFractionDigits: 2, maximumFractionDigits: 2 });
    const pct = (rate) => Math.round(rate * 100) + '%';

    // ── Document ──────────────────────────────────────────────────────────
    const doc = new pdf.PdfDocument();
    doc.PageSettings.Margins.All = 0; // before Pages.Add(), or the origin stays at the margin
    const page = doc.Pages.Add();

    // Text is dropped past the canvas client area, so lay out against it.
    const W = page.Canvas.ClientSize.Width;
    const H = page.Canvas.ClientSize.Height;
    const PAD = 28;
    const EDGE = W - PAD;

    // ── Drawing toolkit ───────────────────────────────────────────────────
    // Object notation selects the PdfFont / PdfSolidBrush / PdfPen overload —
    // the positional constructors all report "Ambiguous call" here.
    const rgb = (c) => new pdf.PdfRGBColor(c[0], c[1], c[2]);
    const paint = (c) => new pdf.PdfSolidBrush({ pdfRGBColor: rgb(c) });
    const font = (size, bold) =>
      new pdf.PdfFont({
        fontFamily: pdf.PdfFontFamily.Helvetica,
        size,
        ...(bold ? { style: pdf.PdfFontStyle.Bold } : {}),
      });
    // DrawString's first parameter is `s`, and it has no alignment option in
    // point mode — measure the string when it has to be right-aligned.
    const text = (s, f, colour, x, y, align) => {
      const dx = align === 'right' ? f.MeasureString({ text: s }).Width : 0;
      page.Canvas.DrawString({ s, font: f, brush: paint(colour), x: x - dx, y });
    };
    const box = (colour, x, y, w, h) =>
      page.Canvas.DrawRectangle({ brush: paint(colour), x, y, width: w, height: h });

    const INK = [26, 31, 43], NAVY = [23, 54, 93], ACCENT = [47, 111, 181];
    const MUTED = [107, 114, 128], RULE = [220, 225, 232], ZEBRA = [246, 248, 251];
    const SOFT = [238, 243, 249], WHITE = [255, 255, 255], ON_NAVY = [186, 200, 220];
    const fHero = font(26, true), fBrand = font(17, true), fTitle = font(11, true);
    const fBody = font(9.5), fBold = font(9.5, true), fSmall = font(8.5);
    const fLabel = font(7.5, true), fFoot = font(7.5), fCell = font(9), fHead = font(8, true);

    // ── Header band, bleeding to the sheet edges ──────────────────────────
    box(NAVY, 0, 0, W, 106);
    box(ACCENT, 0, 106, W, 3.5);
    text(invoice.seller[0], fBrand, WHITE, PAD, 30);
    text(invoice.seller[1], fSmall, ON_NAVY, PAD, 52);
    text(invoice.seller[2], fFoot, ON_NAVY, PAD, 68);
    text('INVOICE', fHero, WHITE, EDGE, 22, 'right');
    text(invoice.number, fBody, ON_NAVY, EDGE, 56, 'right');
    text(`Issued ${invoice.issued}`, fFoot, ON_NAVY, EDGE, 74, 'right');

    // ── Billed to / invoice details ───────────────────────────────────────
    const top = 158;
    text('BILL TO', fLabel, MUTED, PAD, top);
    text(invoice.buyer[0], fBold, INK, PAD, top + 17);
    invoice.buyer.slice(2).forEach((line, i) => text(line, fBody, MUTED, PAD, top + 35 + i * 14));
    text(invoice.buyer[1], fSmall, MUTED, PAD, top + 83);

    const details = [
      ['Invoice No.', invoice.number], ['Issue date', invoice.issued], ['Due date', invoice.due],
      ['PO number', invoice.po], ['Payment terms', invoice.terms],
    ];
    text('INVOICE DETAILS', fLabel, MUTED, EDGE, top, 'right');
    details.forEach(([key, value], i) => {
      text(key, fSmall, MUTED, EDGE - 128, top + 20 + i * 16);
      text(value, fBold, INK, EDGE, top + 20 + i * 16, 'right');
    });

    const tableY = top + 106;
    page.Canvas.DrawLine({
      pen: new pdf.PdfPen({ pdfRGBColor: rgb(RULE), width: 0.75 }),
      x1: PAD, y1: tableY, x2: EDGE, y2: tableY,
    });

    // ── Line items ────────────────────────────────────────────────────────
    const grid = new pdf.PdfGrid();
    grid.Columns.Add(4);
    [255, 44, 112, 128].forEach((w, i) => (grid.Columns.get_Item(i).Width = w));

    const alignRight = new pdf.PdfStringFormat({ alignment: pdf.PdfTextAlignment.Right });
    [1, 2, 3].forEach((i) => (grid.Columns.get_Item(i).Format = alignRight));

    // Cell padding is subtracted from row.Height — leave room for one line box
    // or every cell renders blank, with no error at all.
    const padding = new pdf.PdfPaddings();
    padding.Left = padding.Right = 8;
    padding.Top = padding.Bottom = 2;
    grid.Style.CellPadding = padding;
    grid.Style.Font = fCell;

    const hairline = new pdf.PdfBorders();
    hairline.All = new pdf.PdfPen({ pdfRGBColor: rgb(RULE), width: 0.5 });

    try { grid.Headers.Add(1); } catch {}
    const head = grid.Headers.get_Item(0);
    head.Height = 26;
    head.Style.BackgroundBrush = paint(NAVY);
    head.Style.TextBrush = paint(WHITE);
    head.Style.Font = fHead;
    ['DESCRIPTION', 'QTY', 'UNIT PRICE', 'AMOUNT'].forEach((label, i) => {
      const cell = head.Cells.get_Item(i);
      cell.Value = new pdf.String(label); // .Value is a .NET object — box the string
      if (i) cell.StringFormat = alignRight;
      cell.Style.Borders = hairline;
    });

    invoice.items.forEach(([description, qty, unit], r) => {
      const row = grid.Rows.Add();
      row.Height = 26;
      if (r % 2) row.Style.BackgroundBrush = paint(ZEBRA);
      [description, String(qty), money(unit), money(qty * unit)].forEach((value, i) => {
        const cell = row.Cells.get_Item(i);
        cell.Value = new pdf.String(value);
        cell.Style.Borders = hairline;
      });
    });

    const layout = new pdf.PdfGridLayoutFormat();
    layout.Layout = pdf.PdfLayoutType.Paginate;
    // The parameter is `format`, not `layout`.
    const tableBottom = grid.Draw({ page, x: PAD, y: tableY + 26, format: layout }).Bounds.Bottom;

    // ── Totals cascade ────────────────────────────────────────────────────
    let y = tableBottom + 22;
    const summary = [
      ['Subtotal', money(subtotal)],
      [`Discount · partner rate ${pct(invoice.discountRate)}`, '-' + money(discount)],
      [`Sales tax · ${pct(invoice.taxRate)}`, money(tax)],
    ];
    summary.forEach(([label, value], i) => {
      text(label, fBody, MUTED, EDGE - 220, y + i * 18);
      text(value, fBody, INK, EDGE, y + i * 18, 'right');
    });
    y += 58;

    box(NAVY, EDGE - 220, y, 220, 34);
    text('TOTAL DUE', fTitle, WHITE, EDGE - 204, y + 11);
    text(money(total), font(14, true), WHITE, EDGE - 14, y + 8, 'right');
    y += 34;

    // ── Payment details ───────────────────────────────────────────────────
    const cardTop = y + 34;
    box(SOFT, PAD, cardTop, W - 2 * PAD, 104);
    box(ACCENT, PAD, cardTop, 3, 104);
    text('PAYMENT DETAILS', fLabel, ACCENT, PAD + 18, cardTop + 16);
    text(invoice.bank[0], fBody, INK, PAD + 18, cardTop + 34);
    text(invoice.bank[1], fBody, INK, PAD + 18, cardTop + 50);
    invoice.remark.forEach((line, i) => text(line, fSmall, MUTED, PAD + 18, cardTop + 72 + i * 14));

    // ── Footer band, mirroring the header ─────────────────────────────────
    box(NAVY, 0, H - 58, W, 58);
    text(invoice.legal, fFoot, ON_NAVY, PAD, H - 41);
    text(invoice.contact, fFoot, ON_NAVY, PAD, H - 27);
    text('Page 1 of 1', fFoot, ON_NAVY, EDGE, H - 41, 'right');
    text(invoice.number, fFoot, ON_NAVY, EDGE, H - 27, 'right');

    // ── Save and download ─────────────────────────────────────────────────
    const fileName = 'Invoice.pdf';
    doc.SaveToFile({ fileName });
    doc.Close();

    const bytes = window.dotnetRuntime.Module.FS.readFile(fileName);
    const url = URL.createObjectURL(new Blob([bytes], { type: 'application/pdf' }));
    Object.assign(document.createElement('a'), { href: url, download: fileName }).click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Generate Invoice PDF</h1>
      <button onClick={generateInvoicePdf}>Generate Invoice PDF</button>
    </div>
  );
}

export default App;
Invoice PDF generated from JavaScript data
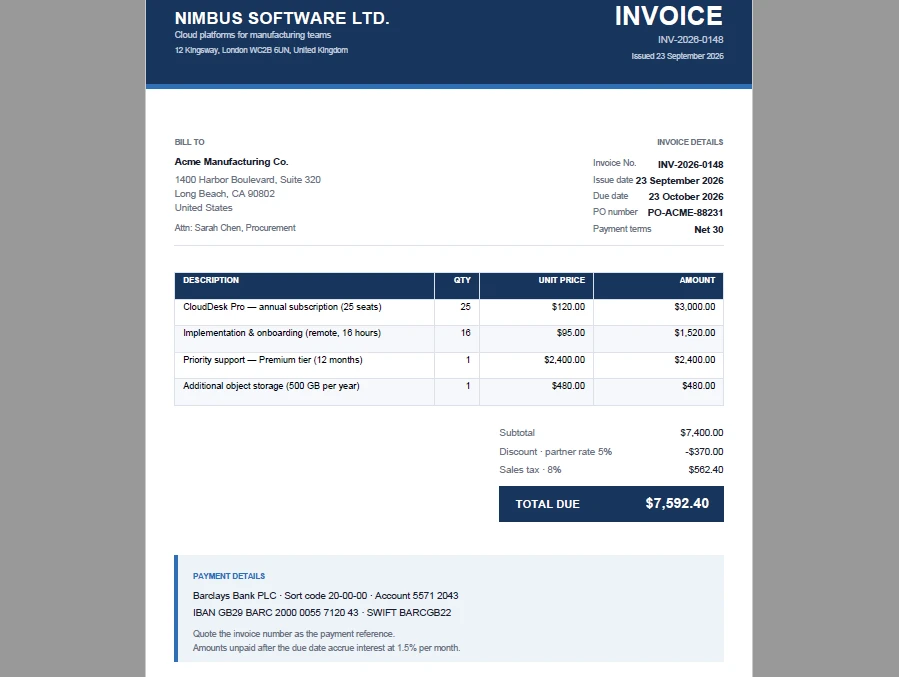
What the code does:
- Defines an
invoiceobject with the seller, the customer, the invoice metadata, and anitemsarray — the shape a React app would receive from a form, an API response, or component state. - Derives
subtotal,discount,tax, andtotalfrom that data withreduce, so the figures printed on the PDF always match the figures in the app. - Sets
Margins.Allto0before callingPages.Add(). The canvas origin sits at the page's margin origin, so this is what makes(0, 0)the top-left corner of the sheet and lets the header and footer bands bleed to the edges. - Lays the page out against
Canvas.ClientSizeinstead ofSize, because text drawn past the client area is dropped rather than clipped. - Draws the header band, the billed-to and invoice-details blocks, the totals cascade, and the payment box with
DrawRectangle,DrawLine, andDrawString. Right-aligned strings are measured withMeasureStringfirst, sinceDrawStringhas no alignment option when you draw at a point. - Builds the line-item table with
PdfGrid: fixed column widths, a styled header row, zebra-striped body rows, and right-aligned numeric columns driven by aPdfStringFormat. - Saves the document to the VFS and downloads it with the blob-and-anchor pattern from step 5.
The same pattern works for any structured document — replace the invoice object with report data, quotation data, or receipt data, and the five-step workflow stays the same.
Add More Content to the PDF
After creating the basic document, you can extend the same workflow with other PDF elements depending on the document you need to generate.
| Element | Typical use | Tutorial |
|---|---|---|
| Text | Titles, labels, paragraphs | Covered in this tutorial |
| Images | Logos, signatures, charts | Add Images to a PDF |
| Tables | Invoices, reports, statements | Document Operation guide |
| Shapes | Borders, separators, diagrams | Draw Shapes in PDF |
| Headers & Footers | Page numbers, repeating headers | Page Setting guide |
| Form fields | Interactive forms, editable documents | Form Field guide |
The five-step workflow does not change — only the content you draw in step 3 differs.
Generate PDFs in the Browser with WebAssembly
Spire.PDF for JavaScript runs its PDF processing engine through WebAssembly. Once the WASM module loads, your application can create, edit, and save PDFs on the client side. Files move through an in-browser Virtual File System (VFS):
JavaScript -> Spire.PDF WebAssembly -> VFS -> Blob -> Download
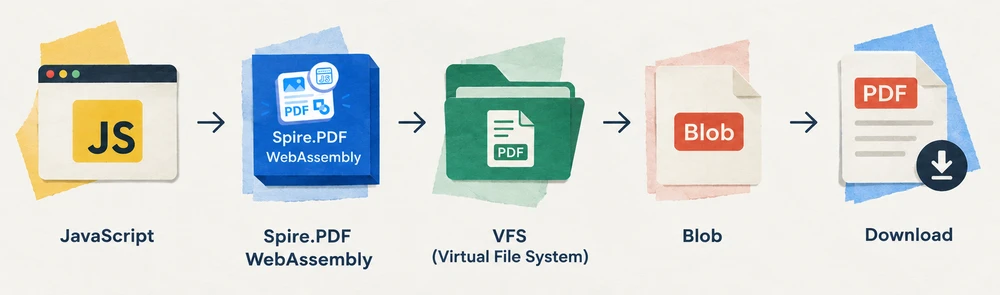
This means no PDF-generation backend is required. The browser handles document creation, rendering, and file output locally. The generated PDF is read from the VFS as a byte array and downloaded as a standard Blob.
The trade-off is the initial WASM download size, which is a one-time cost per session. For applications that generate documents frequently, subsequent generations are fast since the module is already loaded. For very large or complex PDFs, client-side performance depends on the user's device and available memory.
Common Use Cases
Common use cases include invoices, reports, quotations, certificates, receipts, and other structured business documents generated from application data. The specific layout changes, but the underlying workflow — create, add page, draw, save, download — remains the same.
Troubleshooting
WASM Module Not Initialized
If window.spirepdf is undefined, ensure the WebAssembly runtime is fully initialized before using the API:
const commonModule = await import('/node_modules/spire.office/spire.common.js');
await commonModule.initializeWasm();
await import('/node_modules/spire.office/spire.pdf.js');
Generated PDF Cannot Be Downloaded
If the download does not trigger or the file is empty, verify that SaveToFile was called before reading from the VFS. The file must exist in the VFS before FS.readFile can read it:
doc.SaveToFile({ fileName: 'Output.pdf' });
doc.Close();

// Only read after saving
const fileArray = window.dotnetRuntime.Module.FS.readFile('Output.pdf');
Conclusion
Spire.PDF for JavaScript provides a practical way to generate PDF files directly in the browser using JavaScript and WebAssembly. The five-step workflow — create, add page, draw, save, download — handles everything from simple text documents to structured invoices with tables and totals. You can apply for a 30-day free license to evaluate all features before purchasing.
Get the Page Count of a PDF Document in React Using JavaScript
2026-09-24 03:04:24 Written by Nina TangValidating the page count before an upload, estimating paper before a batch print, knowing the document's size before splitting it by page — in each of these cases what you need is a single number: how many pages the document has. Getting that number in the browser isn't straightforward. A rendering library only draws the pages, so you end up counting them yourself; sidestep that layer and the file has to go to a server to be parsed.
This article shows how to get the page count of a PDF document with Spire.PDF for JavaScript. It loads and parses PDF documents directly in the browser on top of WebAssembly, so everything happens locally. Files are read and written through a virtual file system (VFS), with no backend involved. This article walks through counting the total number of pages in a document.
For installation and project setup, see Integrate Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module has been initialized.
Get the Page Count of a PDF Document
Once the document is loaded, doc.Pages is its page collection, and Count gives the number of pages in that collection — the document's total page count. There is no need to loop over the pages and tally them up.
function App() {
  const getPageCount = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be counted into the VFS
    const inputFileName = 'Multipage_Document.pdf';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    const doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Pages is the document's page collection; Count is the total page count
    const pageCount = doc.Pages.Count;

    // Write the result to the VFS
    const outputFileName = 'PageCountResult.txt';
    const report = `Document: ${inputFileName}\r\nTotal pages: ${pageCount}`;
    window.dotnetRuntime.Module.FS.writeFile(outputFileName, report);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/plain' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Get PDF Page Count</h1>
      <button onClick={getPageCount}>
        Count Pages
      </button>
    </div>
  );
}

export default App;
The result is written to a text file that records the document's total page count:
FAQ
The page number shown in a reader doesn't match the total page count
Cause: Pages.Count counts physical pages — how many pages the document actually contains. The number shown in a reader comes from page labels (/PageLabels), which can be configured separately: excluding the cover from numbering, using roman numerals for the table of contents, restarting the body at 1. As a result, the 5th physical page may display as iii or 1 in a reader.
Solution: If what you need is the displayed number, read the page's own PageLabel instead of Count:
// What label the 5th physical page displays in a reader
const page = doc.Pages.get_Item(4);
console.log(page.PageLabel);
When the document has no page labels set, PageLabel returns an empty string — in that case the displayed number matches the physical page order, so Count is the answer.
Loading an encrypted PDF to count pages throws "Can not open an encrypted document. The password is invalid."
Cause: The document is protected by an open password, and without it LoadFromFile cannot read the content at all, so the page count is out of reach as well. This check happens at load time — it is thrown before Pages.Count is ever read.
Solution: Pass the open password as the second argument to LoadFromFile, then read the page count:
// The second argument is the open password
doc.LoadFromFile(inputFileName, 'spire123');
const pageCount = doc.Pages.Count;
Using Count as a loop bound throws an index-out-of-range error on the last page
Cause: Pages is zero-indexed, so the valid range is 0 to Count - 1. When the loop is written as i <= doc.Pages.Count, the final pass tries to fetch page number Count, and get_Item throws an out-of-range error — underneath it is .NET's ArgumentOutOfRangeException, which the WASM runtime wraps as a JS Error with the message ArgumentOutOfRange_IndexMustBeLess Arg_ParamName_Name, index. The error's name is just the generic Error, so match on that message.
Solution: Use < in the loop condition:
// The upper bound is Count - 1, so use < rather than <=
for (let i = 0; i < doc.Pages.Count; i++) {
  const page = doc.Pages.get_Item(i);
}
Get a Free License
If you want to remove the evaluation message from result documents, or lift the feature limits, contact sales for a 30-day temporary license.
