
JavaScript (260)
Autofit Row Heights and Column Widths in React with JavaScript
2026-09-18 01:55:27 Written by liu taliaOnce the data is in, a table usually needs one last pass before it is usable: a product name squeezed into a sliver of a column, a paragraph of remarks running along a single line until the next non-empty cell cuts it off. Dragging column borders and row dividers by hand is slow, and once there are enough columns it is easy to miss a few. Spire.XLS for JavaScript performs this work directly in the browser through WebAssembly, managing input and output files with a virtual file system (VFS) and requiring no backend service.
This article covers two key features:
- Autofit the Height of a Single Row and the Width of a Single Column
- Autofit the Heights of Multiple Rows and the Widths of Multiple Columns
For installation and project setup, see Integrating Spire.XLS for JavaScript in a React Project. The examples below assume Spire.XLS is already installed and the WebAssembly module has been initialized.
Autofit the Height of a Single Row and the Width of a Single Column
AutoFitRow works out the height of the given row from its content, and AutoFitColumn works out the width of the given column the same way. Each one affects only the row or the column it is pointed at and leaves the rest of the table untouched, which is what you want when a single overflow is the only thing in the way.
Note that row height autofit only means anything for content that needs to wrap: with wrapping turned off the text always sits on one line and the height simply follows the font size, so there is no taller value to calculate. The steps are:
- Load the workbook and get the first worksheet.
- Autofit the height of that row with
AutoFitRow. - Autofit the width of that column with
AutoFitColumn. - Save the workbook.
Here is a complete code example that autofits the height of a single row and the width of a single column in React:
function App() {
  const autoFitSingleRowColumn = async () => {
    // Get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // Check whether the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // Load the font into the VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Load the Excel file into the VFS
    const inputFileName = 'AutoFitRowsAndColumns.xlsx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/static/data/`);

    // Load the workbook
    const workbook = new xlsModule.Workbook();
    workbook.LoadFromFile(inputFileName);

    // Get the first worksheet
    const sheet = workbook.Worksheets.get(0);

    // Autofit the height of row 2
    sheet.AutoFitRow(2);

    // Autofit the width of column 4
    sheet.AutoFitColumn(4);

    // Save the workbook
    const outputFileName = "AutoFitSingleRowColumn.xlsx";
    workbook.SaveToFile(outputFileName);

    // Dispose of the workbook object to free resources
    workbook.Dispose();

    // Read the result file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "application/vnd.openxmlformats-officedocument.spreadsheetml.sheet" });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Autofit Row Height and Column Width</h1>
      <button onClick={autoFitSingleRowColumn}>Start</button>
    </div>
  );
}

export default App;
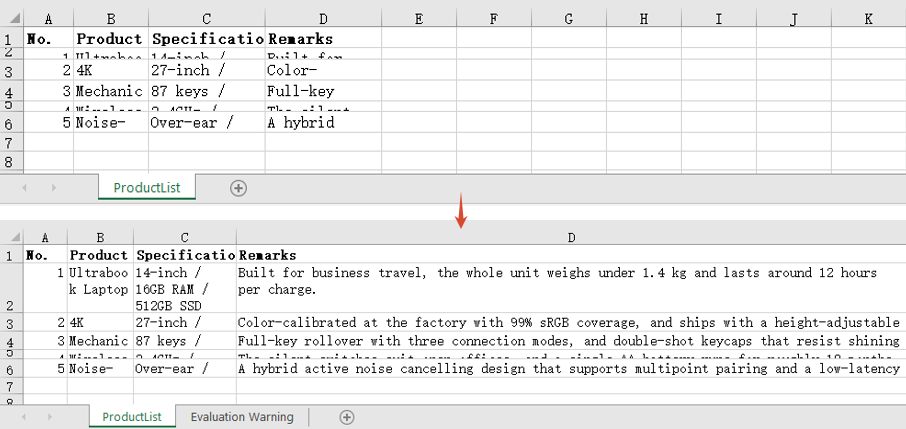
After running, the effect of autofitting a single row height and a single column width:
Autofit the Heights of Multiple Rows and the Widths of Multiple Columns
When the whole table needs tidying, calling the methods row by row is not realistic. Calling AutoFitRows or AutoFitColumns on a range recalculates every row and every column the range covers from its own content, so a single call lines up the whole block — the kind of pass you want before exporting a report. The steps are:
- Load the workbook and get the first worksheet.
- Autofit the heights of the rows with
AutoFitRows. - Autofit the widths of the columns with
AutoFitColumns. - Save the workbook.
Here is a complete code example that autofits the heights of multiple rows and the widths of multiple columns in React:
function App() {
  const autoFitMultipleRowsColumns = async () => {
    // Get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // Check whether the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // Load the font into the VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Load the Excel file into the VFS
    const inputFileName = 'AutoFitRowsAndColumns.xlsx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/static/data/`);

    // Load the workbook
    const workbook = new xlsModule.Workbook();
    workbook.LoadFromFile(inputFileName);

    // Get the first worksheet
    const sheet = workbook.Worksheets.get(0);

    // Get the used range of the worksheet
    const range = sheet.AllocatedRange;

    // Autofit the height of every row in the range
    range.AutoFitRows();

    // Autofit the width of every column in the range
    range.AutoFitColumns();

    // Save the workbook
    const outputFileName = "AutoFitMultipleRowsColumns.xlsx";
    workbook.SaveToFile(outputFileName);

    // Dispose of the workbook object to free resources
    workbook.Dispose();

    // Read the result file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "application/vnd.openxmlformats-officedocument.spreadsheetml.sheet" });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Autofit Row Height and Column Width</h1>
      <button onClick={autoFitMultipleRowsColumns}>Start</button>
    </div>
  );
}

export default App;
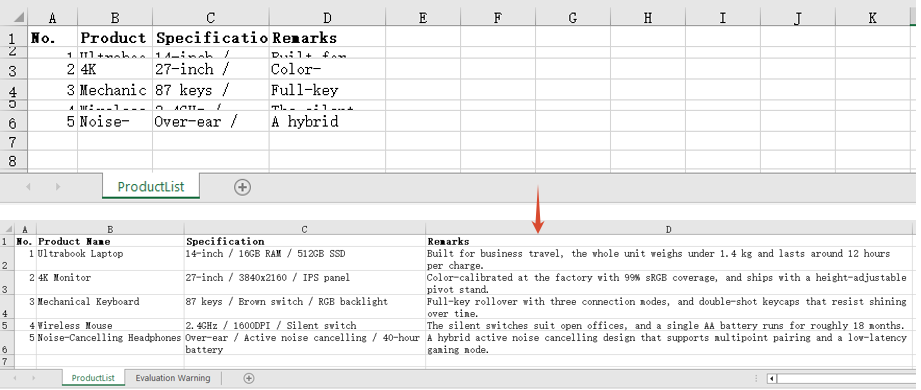
After running, the effect of autofitting multiple row heights and multiple column widths:
FAQ
I called AutoFitRow() and the row height did not change at all?
Cause: Row height autofit only applies to content that needs to wrap. With wrapping turned off the text stays on a single line and the height follows the font size, so autofit arrives at the same value as the existing height and appears to have done nothing.
Solution: Set WrapText to true first, then autofit the row height:
// With wrapping off, autofitting the row height changes nothing
sheet.Range.get("D2").Style.WrapText = false;
sheet.AutoFitRow(2);

// With wrapping on, the height is recalculated from the wrapped line count
sheet.Range.get("D2").Style.WrapText = true;
sheet.AutoFitRow(2);
AutoFitColumns() has no effect on merged cells?
Cause: Column width autofit measures the content of individual cells. In a merged range only the top-left cell actually holds text and every other position in the range is empty, so the width it works out is only enough for that top-left content.
Solution: Set the width of a merged range by hand with ColumnWidth:
// A7:D7 is a merged range, so autofit cannot work out its combined width
sheet.Range.get("A7:D7").Merge();
sheet.Range.get("A7:D7").AutoFitColumns();

// Set the column width by hand so the merged text fits
sheet.Range.get("A7").ColumnWidth = 40;
Get a Free License
Spire.XLS for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
A scanned page that landed sideways, a landscape table sandwiched between portrait pages, or a document you want turned as a whole before printing — none of these need to be re-laid out. The rotation angle is a property of the PDF page itself; changing it only affects how the page is displayed, and the content on the page stays as it is.
Spire.PDF for JavaScript loads, modifies and saves PDF documents directly in the browser based on WebAssembly, reading and writing files through a virtual file system (VFS), with no backend service required.
This article covers two core features:
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The following examples assume Spire.PDF is installed and the WebAssembly module has been initialized.
Rotate a New Page
To give every page in a section the same orientation, one setting on the section is enough: section.PageSettings.Rotate takes PdfPageRotateAngle.RotateAngle90, and all pages in that section are rotated 90 degrees clockwise. RotateAngle180 and RotateAngle270 are also available, and leaving it unset means no rotation.
function App() {
  const createRotatedPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the font into the VFS for the page text
    await window.spire.FetchFileToVFS('ARIAL UNICODE MS.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Create a blank document
    const doc = new pdfModule.PdfDocument();

    // Add a section; every page in it shares a 90-degree clockwise rotation
    const section = doc.Sections.Add();
    section.PageSettings.Size = pdfModule.PdfPageSize.A4();
    section.PageSettings.Rotate = pdfModule.PdfPageRotateAngle.RotateAngle90;

    // Add a page to the section
    const page = section.Pages.Add();

    // Draw a line of text on the page
    const font = new pdfModule.PdfTrueTypeFont({ fontFile: '/Library/Fonts/ARIAL UNICODE MS.TTF', size: 14 });
    page.Canvas.DrawString({
      s: 'This page is set to rotate 90 degrees at creation time',
      font: font,
      brush: pdfModule.PdfBrushes.get_Black(),
      x: 40,
      y: 60,
      format: new pdfModule.PdfStringFormat({ alignment: pdfModule.PdfTextAlignment.Left })
    });

    // Save and read back from the VFS to trigger the download
    const outputFileName = 'RotatedDocument.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Create a Rotated PDF</h1>
      <button onClick={createRotatedPdf}>
        Start Creating
      </button>
    </div>
  );
}

export default App;
If you only want to pass the angle while creating a page, the overload
doc.Pages.Add(size, margins, rotation)works as well.
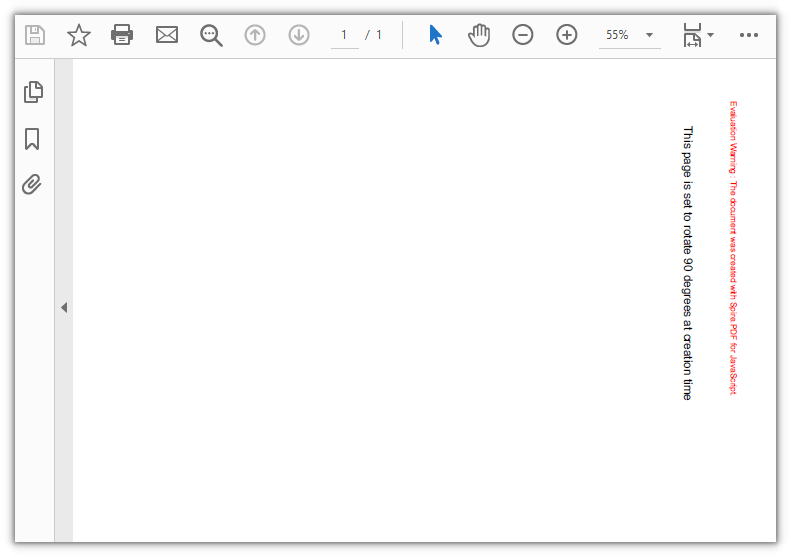
The A4 page is set to a 90-degree rotation at creation time:
Rotate an Existing Page
To change the orientation of an existing document, note that the angle lives in the page's own Rotation property: read the current value first, then add this call's rotation to it. What gets written back is the enum value of PdfPageRotateAngle (0 for no rotation, 1 for 90 degrees), not the angle itself.
function App() {
  const rotateExistingPage = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be processed into the VFS
    const inputFileName = 'Multipage_Document.pdf';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    const doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Take the first page and add this call's rotation to its current angle
    const page = doc.Pages.get_Item(0);
    let rotation = page.Rotation.value + pdfModule.PdfPageRotateAngle.RotateAngle90.value;

    // The enum value only runs from 0 to 3; 4 means a full turn, back to no rotation
    if (rotation === 4) {
      rotation = 0;
    }
    page.Rotation = rotation;

    // Save and read back from the VFS to trigger the download
    const outputFileName = 'RotatedPage.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Rotate a Specific Page</h1>
      <button onClick={rotateExistingPage}>
        Start Rotating
      </button>
    </div>
  );
}

export default App;
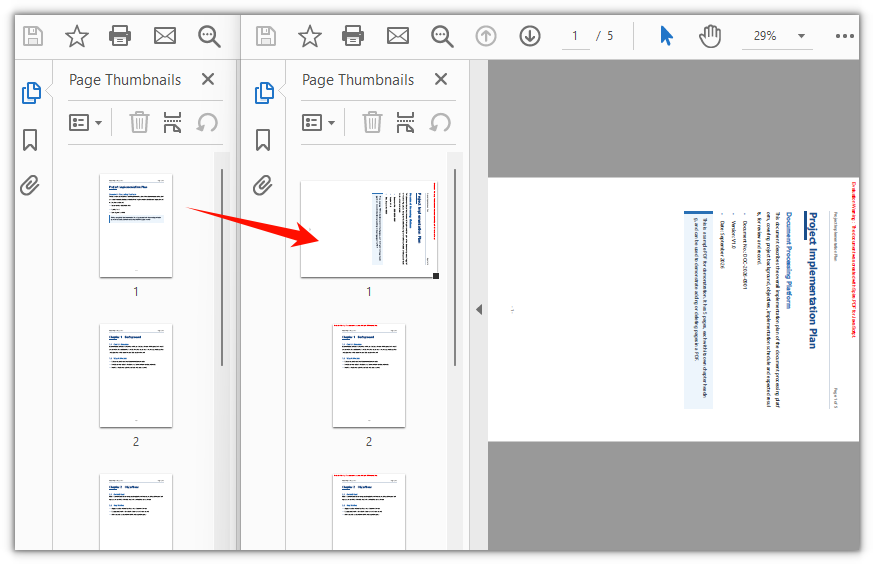
Only the first page is rotated 90 degrees, the remaining pages keep their orientation:
FAQ
Why does assigning to Rotation report "Value is not an integer"
Cause: The write side of page.Rotation only accepts an integer. Passing a PdfPageRotateAngle enum object directly throws Assert failed: Value is not an integer: PdfPageRotateAngle.RotateAngle90 (object).
Solution: Take the enum's value and assign that:
page.Rotation = pdfModule.PdfPageRotateAngle.RotateAngle90.value;
Why does the page end up rotated 180 degrees after I pass 90
Cause: The enum values of PdfPageRotateAngle are 0, 1, 2 and 3, standing for 0, 90, 180 and 270 degrees. That value is what the write side expects, not the angle. Writing page.Rotation = 90 throws no error but does not give you 90 degrees, and looking the value up with PdfPageRotateAngle.fromValue(90) throws Invalid value for spirepdfPdfPageRotateAngle.
Solution: Convert to the enum value before writing:
// 90 degrees
page.Rotation = pdfModule.PdfPageRotateAngle.RotateAngle90.value;

// 180 degrees
page.Rotation = pdfModule.PdfPageRotateAngle.RotateAngle180.value;
Why does the rotation argument on section.Pages.Add(...) have no effect
Cause: The overload that takes a rotation argument, Add(size, margins, rotation), only works on doc.Pages. On section.Pages the argument is ignored, and the page orientation is decided by the PageSettings.Rotate of the section it belongs to. The /Rotate entry in the file stays 0, the page is not rotated, and no error is raised.
Solution: Pick one of the two forms below, and do not pass the argument to section.Pages:
// Form 1: set it on the section, applying to every page in that section
section.PageSettings.Rotate = pdfModule.PdfPageRotateAngle.RotateAngle90;
section.Pages.Add();

// Form 2: create the page on doc.Pages and pass the angle
const page = doc.Pages.Add(
  pdfModule.PdfPageSize.A4(),
  new pdfModule.PdfMargins(),
  pdfModule.PdfPageRotateAngle.RotateAngle90
);
A page can still be adjusted on its own after it has been created; page.Rotation overrides the section setting:
// Rotate only the second page to 180 degrees, leaving the rest untouched
doc.Pages.get_Item(1).Rotation = pdfModule.PdfPageRotateAngle.RotateAngle180.value;
Get a Free License
If you wish to remove the evaluation message from the result document or remove feature limitations, please contact sales to obtain a temporary license valid for 30 days.
Adding annotations to a PDF, pulling data out of a region, or drawing a border around an image all start with knowing where the target element sits on the page. A PDF has no ready-made coordinate table: text is a series of drawing instructions, images are objects in the page resources, and the position information is scattered across their own matrices and rectangles. In the past you either wrote your own parser to pull those numbers out, or sent the file back to a server to handle.
Spire.PDF for JavaScript loads and parses PDF documents in the browser with WebAssembly and reads and writes files through a virtual file system (VFS), with no backend involved.
This article covers two core features:
For installation and project setup, see How to Integrate Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Coordinate system
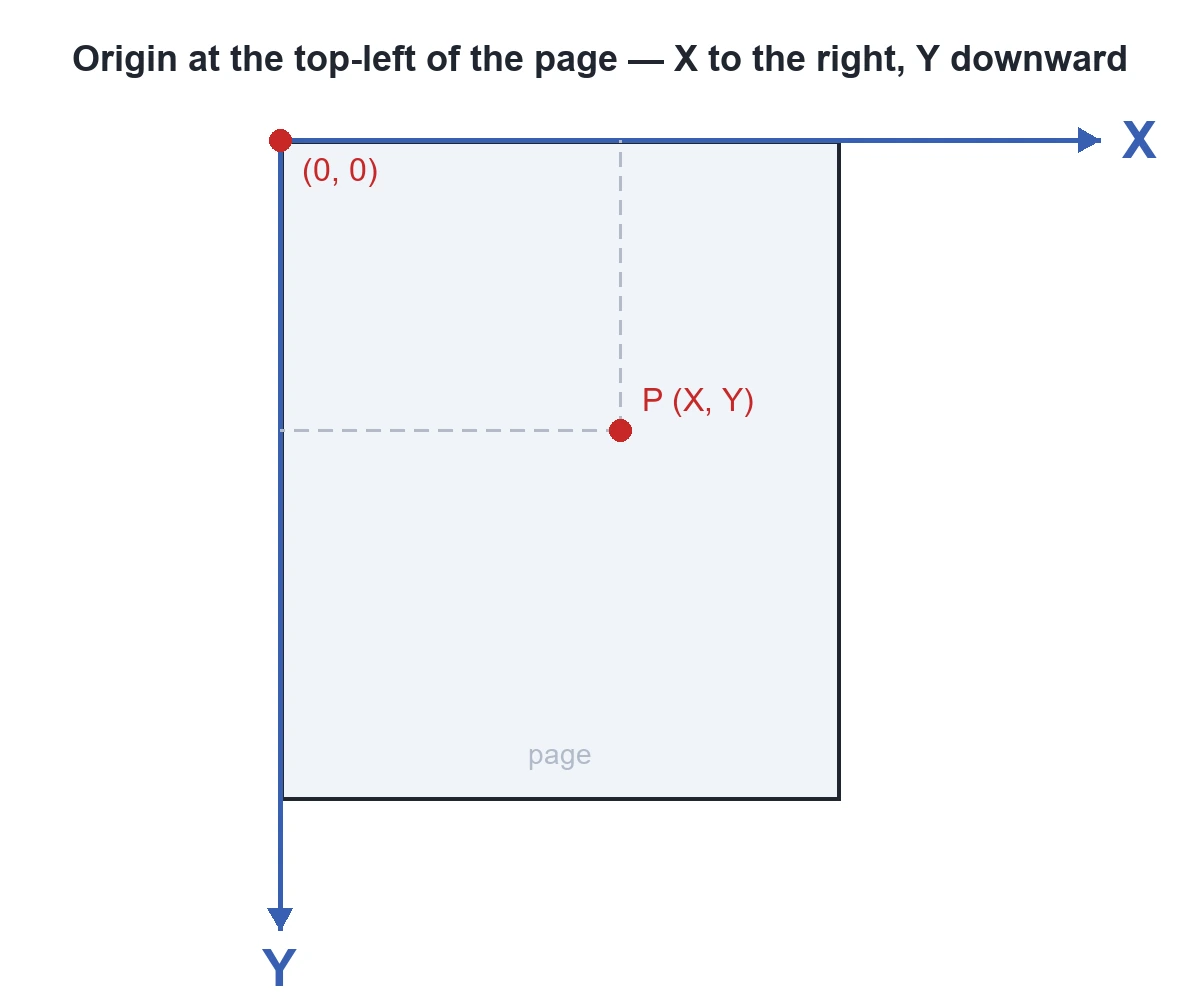
When Spire.PDF works with an existing PDF document, the origin of the coordinate system is at the top-left corner of the page. The X axis extends horizontally to the right from the origin, and the Y axis extends vertically downward from the origin (as shown below). Values are in points (1 point = 1/72 inch), and both Positions and Bounds in the two features below report coordinates in this system.
Get the coordinates of specified text
Spire.PDF for JavaScript provides PdfTextFinder to look up text on a page by content, and every match reports the coordinates of where it lands. The search works one page at a time, so a multi-page document has to be processed page by page.
function App() {
  const getTextCoordinates = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to process into the VFS
    const inputFileName = 'Flowers.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Get page 1
    let page = doc.Pages.get_Item(0);

    // Create a text finder and search for the given text, ignoring case
    let finder = new pdfModule.PdfTextFinder(page);
    finder.Options.Parameter = pdfModule.TextFindParameter.IgnoreCase;
    let results = finder.Find('Rose');

    // Collect the coordinates of each match
    let report = '';
    for (let i = 0; i < results.length; i++) {
      let find = results.get(i);
      let position = find.Positions[0];

      report += 'Match ' + (i + 1) + ': ' + find.Text + '\n';
      report += '  Coordinates: X = ' + position.X + ', Y = ' + position.Y + '\n';
    }

    // Write the report into the VFS
    const outputFileName = 'TextCoordinates.txt';
    window.dotnetRuntime.Module.FS.writeFile(outputFileName, new TextEncoder().encode(report));
    doc.Close();

    // Read the generated file back from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/plain' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Get Text Coordinates</h1>
      <button onClick={getTextCoordinates}>
        Get
      </button>
    </div>
  );
}

export default App;
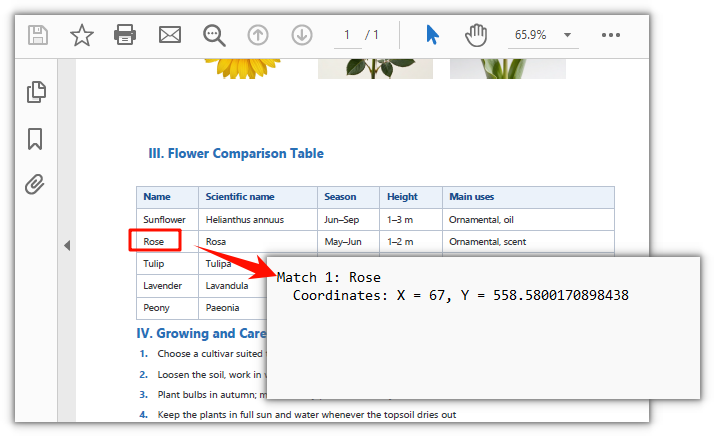
Coordinates of the matched text
Get the coordinates of images on a page
Spire.PDF for JavaScript also provides PdfImageHelper to read the position of every image on a page. Images are already registered in the page resources, so the Bounds you get back gives the top-left coordinates directly. This also works one page at a time.
function App() {
  const getImageCoordinates = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to process into the VFS
    const inputFileName = 'Flowers.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Get page 1
    let page = doc.Pages.get_Item(0);

    // Create an image helper and get the image info of this page
    let helper = new pdfModule.PdfImageHelper();
    let images = helper.GetImagesInfo(page);

    // Collect the coordinates of each image
    let report = '';
    for (let i = 0; i < images.length; i++) {
      let bounds = images[i].Bounds;

      report += 'Image ' + (i + 1) + ':' + '\n';
      report += '  Coordinates: X = ' + bounds.X + ', Y = ' + bounds.Y + '\n';
    }

    // Write the report into the VFS
    const outputFileName = 'ImageCoordinates.txt';
    window.dotnetRuntime.Module.FS.writeFile(outputFileName, new TextEncoder().encode(report));
    doc.Close();

    // Read the generated file back from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/plain' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Get Image Coordinates</h1>
      <button onClick={getImageCoordinates}>
        Get
      </button>
    </div>
  );
}

export default App;
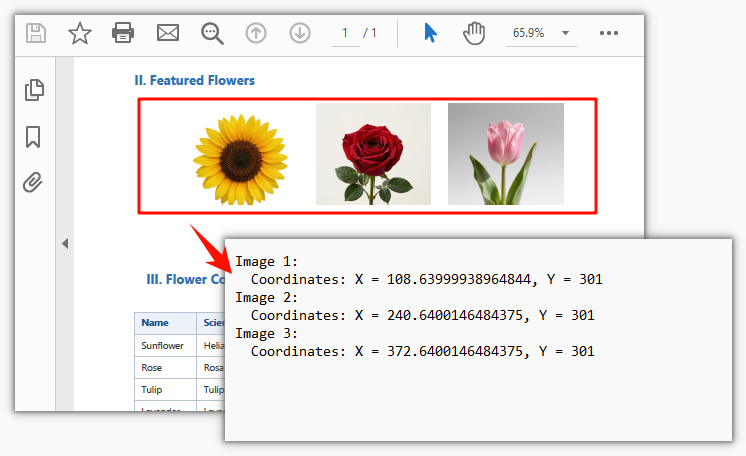
Coordinates of the three flower images on the page
FAQ
A different letter case stops it from matching
Cause: The matching behavior of Find() is determined by Options.Parameter. The default value TextFindParameter.None searches by substring and is case-sensitive, so Rose and rose are treated as two different things.
Fix: Switch to the value you need. TextFindParameter is a flags enum, so values can be combined with bitwise OR:
// Ignore case
finder.Options.Parameter = pdfModule.TextFindParameter.IgnoreCase;

// Match whole words only, ignoring case
finder.Options.Parameter = pdfModule.TextFindParameter.WholeWord | pdfModule.TextFindParameter.IgnoreCase;

// Search with a regular expression: match Rosa or Tulipa in one pass
finder.Options.Parameter = pdfModule.TextFindParameter.Regex;
let results = finder.Find('Rosa|Tulipa');
The coordinates don't match what the PDF reader shows
Cause: Positions and Bounds use the page coordinate system described above; inside a PDF file (/MediaBox, content streams) the origin is at the bottom-left with Y increasing upward, so the two conventions differ by a full page height and a direct comparison will be off by the whole page.
Fix: Work with the top-left origin consistently. To convert to pixels, multiply by dpi / 72 — the factor is 1.333 at 96 dpi. The values you get are floating-point numbers, so round to two decimals before comparing if you need an exact match.
The image info doesn't include the shapes I can see on the page
Cause: GetImagesInfo returns the bitmap objects in the page resources. Lines, table borders, and color blocks drawn with vector instructions are not images; conversely, a full-page scan is a single image covering the page, and the text inside it cannot be searched.
Fix: Start by using the X and Y from Bounds to confirm where each image actually sits on the page. Lines and shapes drawn with vector instructions are not returned by GetImagesInfo, and text inside a scanned page cannot be found either — to locate those, use text extraction (PdfTextExtractor) or bring in OCR separately.
Get a Free License
If you want to remove the evaluation message from the result documents or get past the feature limits, contact sales for a 30-day temporary license.
Modify, Hide and Delete Named Ranges in React with JavaScript
2026-09-17 05:55:53 Written by liu taliaA named range is not something you set up once and forget. As the data table is restructured, the original name may no longer fit, and the referred range can go stale when rows are added or removed. Some named ranges exist only as an intermediate helper for a formula and have no business showing up in the Name Manager. And named ranges that are no longer used, if kept forever, turn the name list into something long and hard to search. Modifying, hiding and deleting are therefore just as much a part of working with named ranges as creating them. Spire.XLS for JavaScript provides a complete named range management API and can perform all of the above in the browser through WebAssembly, with no backend service required.
This article covers three key features:
For installation and project setup, see Integrating Spire.XLS for JavaScript in a React Project. The examples below assume Spire.XLS is already installed and the WebAssembly module has been initialized.
Modify a Named Range
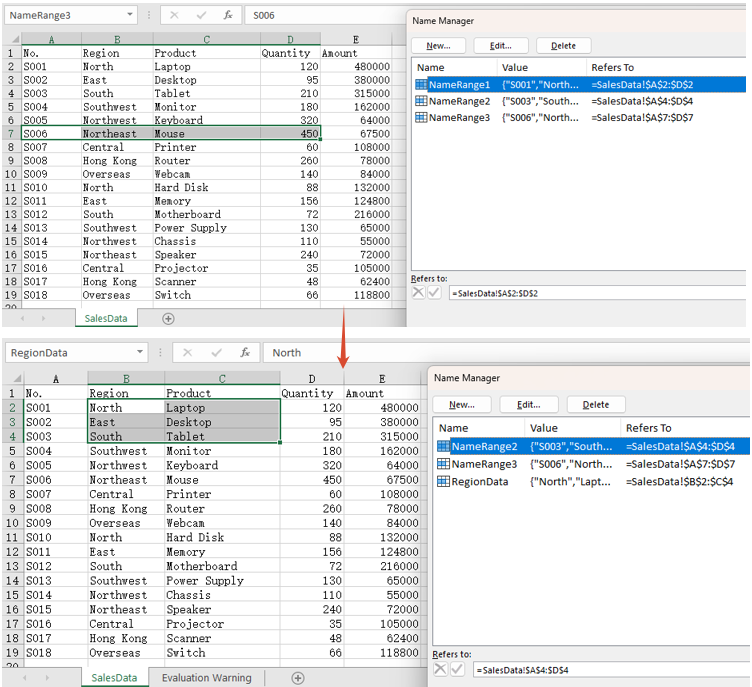
Modifying covers two independent aspects: the name itself and the referred range. The name is reassigned through the Name property and the referred range through the RefersToRange property. The two can be changed separately, or together as in the example below. The steps are:
- Load the workbook and get the first worksheet.
- Take the named range to modify with
workbook.NameRanges.get(0). - Set
Nameto the new name. - Point
RefersToRangeat the new cell range. - Save the workbook.
The following is a complete code example that shows how to modify a named range in React:
function App() {
  const modifyNamedRange = async () => {
    // Get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // Check if the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // Load the font into VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Load the Excel file into VFS
    const inputFileName = 'AllNamedRanges.xlsx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/static/data/`);

    // Load the workbook
    const workbook = new xlsModule.Workbook();
    workbook.LoadFromFile(inputFileName);

    // Get the first worksheet
    let sheet = workbook.Worksheets.get(0);

    // Change the name of the named range
    workbook.NameRanges.get(0).Name = "RegionData";

    // Change the cell range the named range refers to
    workbook.NameRanges.get(0).RefersToRange = sheet.Range.get("B2:C4");

    // Save the workbook
    const outputFileName = 'ModifyNamedRange.xlsx';
    workbook.SaveToFile(outputFileName);

    // Release resources
    workbook.Dispose();

    // Read the result file from VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "application/vnd.openxmlformats-officedocument.spreadsheetml.sheet" });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Modify Named Range</h1>
      <button onClick={modifyNamedRange}>Start</button>
    </div>
  );
}

export default App;
After running, the effect of modifying a named range:
Hide a Named Range
Set the Visible property to false and the named range is hidden. A hidden named range is still stored in the workbook and formulas that refer to it are unaffected — it simply no longer appears in Excel's Name Manager and name box, which keeps the name list tidy. After hiding it, the example below also writes the formula =SUM(NameRange1) into cell F2: the formula still calculates normally, which is exactly what shows that the named range is only hidden, not deleted. The steps are:
- Load the workbook and get the first worksheet.
- Take the named range to hide.
- Set
Visibletofalse. - Write a formula that refers to the named range into a cell, to confirm it still works.
- Save the workbook.
The following is a complete code example that shows how to hide a named range in React:
function App() {
  const hideNamedRange = async () => {
    // Get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // Check if the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // Load the font into VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Load the Excel file into VFS
    const inputFileName = 'AllNamedRanges.xlsx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/static/data/`);

    // Load the workbook
    const workbook = new xlsModule.Workbook();
    workbook.LoadFromFile(inputFileName);

    // Get the first worksheet
    let sheet = workbook.Worksheets.get(0);

    // Hide the first named range
    workbook.NameRanges.get(0).Visible = false;

    // Write a formula that refers to the hidden named range, proving it still exists and works
    sheet.Range.get("F1").Text = "Sum After Hiding";
    sheet.Range.get("F2").Formula = "=SUM(NameRange1)";

    // Calculate the formulas so the saved file shows the result as soon as it is opened
    workbook.CalculateAllValue();

    // Save the workbook
    const outputFileName = 'HideNamedRange.xlsx';
    workbook.SaveToFile(outputFileName);

    // Release resources
    workbook.Dispose();

    // Read the result file from VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "application/vnd.openxmlformats-officedocument.spreadsheetml.sheet" });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Hide Named Range</h1>
      <button onClick={hideNamedRange}>Start</button>
    </div>
  );
}

export default App;
After running, the effect of hiding a named range:
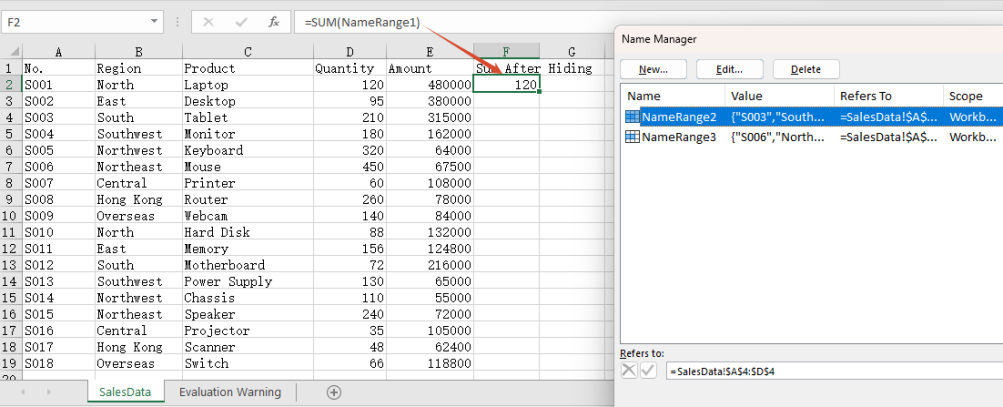
Note: The formula in cell F2 refers to the hidden NameRange1, and it still calculates 120. That shows the named range has only been hidden from view, not removed from the workbook.
Delete a Named Range
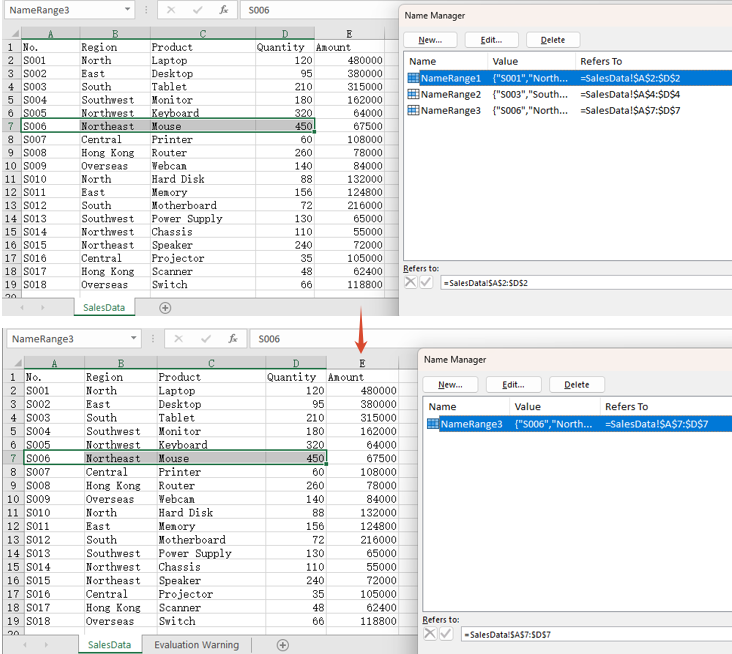
There are two ways to delete a named range: call Remove() when the name is known, or RemoveAt() when the position is known. Both remove the named range from the workbook entirely. The steps are:
- Load the workbook.
- Call
Remove()to delete a named range by name. - Call
RemoveAt()to delete a named range by index. - Save the workbook.
The following is a complete code example that shows how to delete a named range in React:
function App() {
  const deleteNamedRange = async () => {
    // Get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // Check if the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // Load the font into VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Load the Excel file into VFS
    const inputFileName = 'AllNamedRanges.xlsx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/static/data/`);

    // Load the workbook
    const workbook = new xlsModule.Workbook();
    workbook.LoadFromFile(inputFileName);

    // Delete a named range by name
    workbook.NameRanges.Remove("NameRange2");

    // Delete a named range by index
    workbook.NameRanges.RemoveAt(0);

    // Save the workbook
    const outputFileName = 'DeleteNamedRange.xlsx';
    workbook.SaveToFile(outputFileName);

    // Release resources
    workbook.Dispose();

    // Read the result file from VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "application/vnd.openxmlformats-officedocument.spreadsheetml.sheet" });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Delete Named Range</h1>
      <button onClick={deleteNamedRange}>Start</button>
    </div>
  );
}

export default App;
After running, the effect of deleting a named range:
FAQ
Why is the result of a formula missing when the saved file is opened?
Cause: Setting only the Formula property of a cell does not make Spire calculate it. The saved file then contains the formula itself but no calculated result value, so the cell comes up blank when the file is opened.
Solution: Call workbook.CalculateAllValue() before saving, to evaluate the formulas first:
// Calculate all formulas so the result value is written into the saved file
workbook.CalculateAllValue();
Can I pass a named range object to the delete API?
Cause: Remove() takes a name string. Passing a NameRange object does not match the expected type and throws Assert failed: Value is not a String, and nothing is deleted.
Solution: Pass the name when it is known, or the index when the position is known:
// Delete by name
workbook.NameRanges.Remove("NameRange2");

// Delete by index
workbook.NameRanges.RemoveAt(0);
Get a Free License
Spire.XLS for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Set the Alignment, Indent, Orientation and Wrapping of Excel Cell Text in React with JavaScript
2026-09-17 05:55:07 Written by liu taliaHow readable a table is often has nothing to do with the data itself and everything to do with how the text sits inside its cells. Titles need to be centred, amounts need to be pushed right, multi-line descriptions need to be indented, a long sentence in a narrow column needs to fold, and a header set at an angle fits more information into limited column width. All of these are cell text layout settings. Spire.XLS for JavaScript performs them directly in the browser through WebAssembly, managing input and output files with a virtual file system (VFS) and requiring no backend service.
This article covers four key features:
- Set the Alignment of Text
- Set the Indent of Text
- Set the Orientation of Text
- Set the Wrapping of Text
For installation and project setup, see Integrating Spire.XLS for JavaScript in a React Project. The examples below assume Spire.XLS is already installed and the WebAssembly module has been initialized.
Set the Alignment of Text
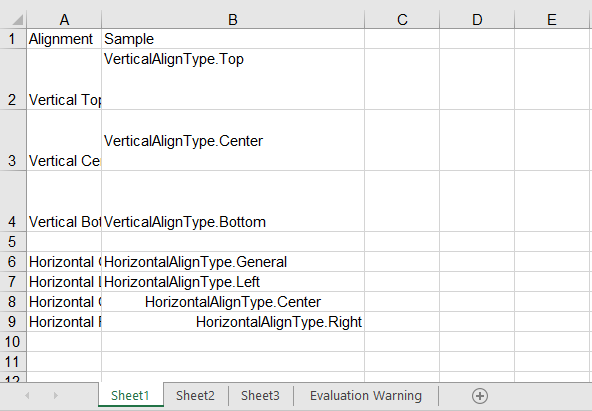
Alignment works along two axes. Vertical alignment decides where the text sits within the height of the cell and is set through the VerticalAlignment property, which accepts Top, Center, Bottom and others. Horizontal alignment decides where the text sits within the width of the cell and is set through the HorizontalAlignment property, which accepts General, Left, Center, Right and others. The two are independent and can be combined freely. The steps are as follows:
- Create a workbook and get the first worksheet.
- Write the sample text.
- Set the vertical alignment through
VerticalAlignment. - Set the horizontal alignment through
HorizontalAlignment. - Save the workbook.
Here is a complete code example that sets the alignment of cell text in React:
function App() {
  const setTextAlignment = async () => {
    // Get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // Check if the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // Load the font into VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Create a new workbook
    const workbook = new xlsModule.Workbook();

    // Get the first worksheet
    const sheet = workbook.Worksheets.get(0);

    // Write the sample text for vertical alignment
    sheet.Range.get("A1").Text = "Alignment";
    sheet.Range.get("B1").Text = "Sample";
    sheet.Range.get("A2").Text = "Vertical Top";
    sheet.Range.get("B2").Text = "VerticalAlignType.Top";
    sheet.Range.get("A3").Text = "Vertical Center";
    sheet.Range.get("B3").Text = "VerticalAlignType.Center";
    sheet.Range.get("A4").Text = "Vertical Bottom";
    sheet.Range.get("B4").Text = "VerticalAlignType.Bottom";

    // Write the sample text for horizontal alignment
    sheet.Range.get("A6").Text = "Horizontal General";
    sheet.Range.get("B6").Text = "HorizontalAlignType.General";
    sheet.Range.get("A7").Text = "Horizontal Left";
    sheet.Range.get("B7").Text = "HorizontalAlignType.Left";
    sheet.Range.get("A8").Text = "Horizontal Center";
    sheet.Range.get("B8").Text = "HorizontalAlignType.Center";
    sheet.Range.get("A9").Text = "Horizontal Right";
    sheet.Range.get("B9").Text = "HorizontalAlignType.Right";

    // Set the vertical alignment
    sheet.Range.get("B2").Style.VerticalAlignment = xlsModule.VerticalAlignType.Top;
    sheet.Range.get("B3").Style.VerticalAlignment = xlsModule.VerticalAlignType.Center;
    sheet.Range.get("B4").Style.VerticalAlignment = xlsModule.VerticalAlignType.Bottom;

    // Set the horizontal alignment
    sheet.Range.get("B6").Style.HorizontalAlignment = xlsModule.HorizontalAlignType.General;
    sheet.Range.get("B7").Style.HorizontalAlignment = xlsModule.HorizontalAlignType.Left;
    sheet.Range.get("B8").Style.HorizontalAlignment = xlsModule.HorizontalAlignType.Center;
    sheet.Range.get("B9").Style.HorizontalAlignment = xlsModule.HorizontalAlignType.Right;

    // Widen column B and raise rows 2-4 so the alignment differences are visible
    sheet.Range.get("B1:B9").ColumnWidth = 32;
    sheet.Range.get("A2:B4").RowHeight = 40;

    // Save the workbook
    const outputFileName = "TextAlignment.xlsx";
    workbook.SaveToFile(outputFileName);

    // Release resources
    workbook.Dispose();

    // Read the result file from VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "application/vnd.openxmlformats-officedocument.spreadsheetml.sheet" });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Set Text Alignment</h1>
      <button onClick={setTextAlignment}>Start</button>
    </div>
  );
}

export default App;
Vertical alignment is only visible once the row is tall enough, which is why the example sets rows 2-4 to a height of 40; horizontal alignment is at its clearest once the column is wide enough.
After running, the effect of setting the alignment of text:
Set the Indent of Text
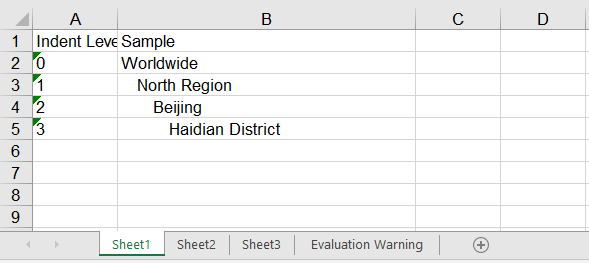
Indentation leaves blank space on the left (or right) inside a cell, which suits data that has a hierarchy, such as "region → city". The indent level is set through the IndentLevel property, where one level is roughly one character wide. The steps are as follows:
- Create a workbook and get the first worksheet.
- Write the sample text.
- Set the horizontal alignment to left so the indentation takes effect.
- Set an increasing indent level through
IndentLevel. - Save the workbook.
Here is a complete code example that sets the indent of cell text in React:
function App() {
  const setTextIndent = async () => {
    // Get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // Check if the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // Load the font into VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Create a new workbook
    const workbook = new xlsModule.Workbook();

    // Get the first worksheet
    const sheet = workbook.Worksheets.get(0);

    // Write the sample text
    sheet.Range.get("A1").Text = "Indent Level";
    sheet.Range.get("B1").Text = "Sample";
    sheet.Range.get("A2").Text = "0";
    sheet.Range.get("B2").Text = "Worldwide";
    sheet.Range.get("A3").Text = "1";
    sheet.Range.get("B3").Text = "North Region";
    sheet.Range.get("A4").Text = "2";
    sheet.Range.get("B4").Text = "Beijing";
    sheet.Range.get("A5").Text = "3";
    sheet.Range.get("B5").Text = "Haidian District";

    // Indentation only takes effect together with left alignment
    sheet.Range.get("B2:B5").Style.HorizontalAlignment = xlsModule.HorizontalAlignType.Left;

    // Set the indentation level of the text
    sheet.Range.get("B2").Style.IndentLevel = 0;
    sheet.Range.get("B3").Style.IndentLevel = 1;
    sheet.Range.get("B4").Style.IndentLevel = 2;
    sheet.Range.get("B5").Style.IndentLevel = 3;

    // Widen column B so the indentation differences are visible
    sheet.Range.get("B1:B5").ColumnWidth = 32;

    // Save the workbook
    const outputFileName = "Indentation.xlsx";
    workbook.SaveToFile(outputFileName);

    // Release resources
    workbook.Dispose();

    // Read the result file from VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "application/vnd.openxmlformats-officedocument.spreadsheetml.sheet" });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Set Text Indent</h1>
      <button onClick={setTextIndent}>Start</button>
    </div>
  );
}

export default App;
The four rows step in one level at a time, forming exactly the hierarchy "Worldwide → North Region → Beijing → Haidian District". Cell B5 has an IndentLevel of 3, so its text starts about three characters in from the left edge.
After running, the effect of setting the indent of text:
Set the Orientation of Text
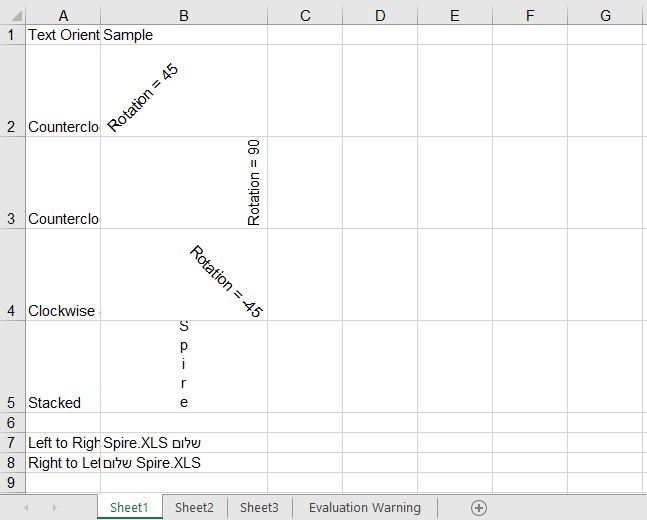
Text orientation covers two independent settings. The first is the rotation angle, set through the Rotation property, where values 0 to 90 are degrees counterclockwise and -1 to -90 are degrees clockwise. There is also the special value 255, which stacks the text vertically one character per line; rotation is often used to fit a long header into a narrow column. The second is the reading order, set through the ReadingOrder property, which accepts LeftToRight, RightToLeft and Context. It decides which direction the mixed content in a cell is laid out from, and is used for languages written from right to left such as Arabic and Hebrew. Rotated or stacked text takes up far more height than usual, so the row height has to be raised at the same time to keep the text inside the cell. The steps are as follows:
- Create a workbook and get the first worksheet.
- Write the sample text.
- Set the rotation angle through
Rotation. - Set the reading order through
ReadingOrder. - Save the workbook.
Here is a complete code example that sets the orientation of cell text in React:
function App() {
  const setTextOrientation = async () => {
    // Get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // Check if the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // Load the font into VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Create a new workbook
    const workbook = new xlsModule.Workbook();

    // Get the first worksheet
    const sheet = workbook.Worksheets.get(0);

    // Write the sample text for the rotation angle
    sheet.Range.get("A1").Text = "Text Orientation";
    sheet.Range.get("B1").Text = "Sample";
    sheet.Range.get("A2").Text = "Counterclockwise 45";
    sheet.Range.get("B2").Text = "Rotation = 45";
    sheet.Range.get("A3").Text = "Counterclockwise 90";
    sheet.Range.get("B3").Text = "Rotation = 90";
    sheet.Range.get("A4").Text = "Clockwise 45";
    sheet.Range.get("B4").Text = "Rotation = -45";
    sheet.Range.get("A5").Text = "Stacked";
    sheet.Range.get("B5").Text = "Spire";

    // Write the sample text for the reading order: Latin mixed with Hebrew, so the
    // difference between the two directions is actually visible
    sheet.Range.get("A7").Text = "Left to Right";
    sheet.Range.get("B7").Text = "Spire.XLS שלום";
    sheet.Range.get("A8").Text = "Right to Left";
    sheet.Range.get("B8").Text = "Spire.XLS שלום";

    // Set the rotation angle of the text; 255 stacks the text vertically
    sheet.Range.get("B2").Style.Rotation = 45;
    sheet.Range.get("B3").Style.Rotation = 90;
    sheet.Range.get("B4").Style.Rotation = -45;
    sheet.Range.get("B5").Style.Rotation = 255;

    // Set the reading order of the text
    sheet.Range.get("B7").Style.ReadingOrder = xlsModule.ReadingOrderType.LeftToRight;
    sheet.Range.get("B8").Style.ReadingOrder = xlsModule.ReadingOrderType.RightToLeft;

    // Widen column B and raise rows 2-5 so the rotated and stacked text fits
    sheet.Range.get("B1:B8").ColumnWidth = 20;
    sheet.Range.get("A2:B5").RowHeight = 60;

    // Save the workbook
    const outputFileName = "TextOrientation.xlsx";
    workbook.SaveToFile(outputFileName);

    // Release resources
    workbook.Dispose();

    // Read the result file from VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "application/vnd.openxmlformats-officedocument.spreadsheetml.sheet" });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Set Text Orientation</h1>
      <button onClick={setTextOrientation}>Start</button>
    </div>
  );
}

export default App;
In the example, B2, B3 and B4 are rotated 45 degrees, 90 degrees and -45 degrees respectively, and B5 uses a Rotation of 255, which stacks the text into a column running top to bottom; all five rows are given a height of 60. B7 and B8 hold the same mixed Latin and Hebrew string with opposite reading orders, and the Hebrew ends up on opposite sides in the two rows — which is exactly what reading order does to mixed content.
After running, the effect of setting the orientation of text:
Set the Wrapping of Text
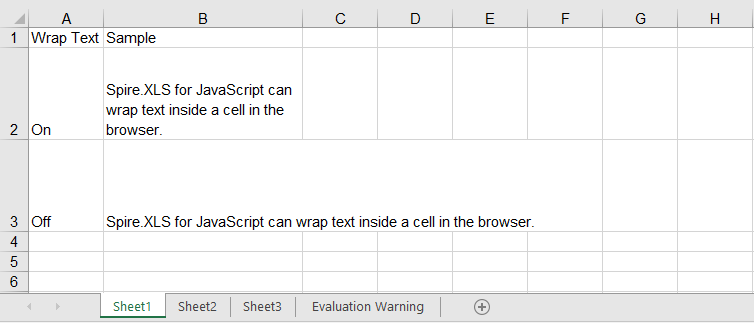
When a piece of text is longer than the column, it spills over onto the neighbouring empty cell by default, and is cut off as soon as that neighbour has content of its own. Setting the WrapText property to true folds the text inside the cell instead; setting it to false returns the text to a single line. As with rotation, wrapping only changes how the text is laid out and does not adjust the row height by itself, so the row height is usually raised as well to show every folded line in full. The steps are as follows:
- Create a workbook and get the first worksheet.
- Write a long piece of text.
- Turn wrapping on or off through
WrapText. - Adjust the column width and row height so the folding is fully visible.
- Save the workbook.
Here is a complete code example that sets the wrapping of cell text in React:
function App() {
  const setTextWrap = async () => {
    // Get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // Check if the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // Load the font into VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Create a new workbook
    const workbook = new xlsModule.Workbook();

    // Get the first worksheet
    const sheet = workbook.Worksheets.get(0);

    // Write the sample text
    sheet.Range.get("A1").Text = "Wrap Text";
    sheet.Range.get("B1").Text = "Sample";
    sheet.Range.get("A2").Text = "On";
    sheet.Range.get("B2").Text = "Spire.XLS for JavaScript can wrap text inside a cell in the browser.";
    sheet.Range.get("A3").Text = "Off";
    sheet.Range.get("B3").Text = "Spire.XLS for JavaScript can wrap text inside a cell in the browser.";

    // Turn wrapping on so the text folds inside the cell when it is wider than the column
    sheet.Range.get("B2").Style.WrapText = true;

    // Turn wrapping off so the text stays on a single line
    sheet.Range.get("B3").Style.WrapText = false;

    // Narrow column B and raise rows 2-3 so the wrapping is visible
    sheet.Range.get("B1:B3").ColumnWidth = 24;
    sheet.Range.get("A2:B3").RowHeight = 60;

    // Save the workbook
    const outputFileName = "WrapText.xlsx";
    workbook.SaveToFile(outputFileName);

    // Release resources
    workbook.Dispose();

    // Read the result file from VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "application/vnd.openxmlformats-officedocument.spreadsheetml.sheet" });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Set Text Wrap</h1>
      <button onClick={setTextWrap}>Start</button>
    </div>
  );
}

export default App;
B2 and B3 hold the very same sentence; the only difference is the value of WrapText. B2 folds into several lines and shows in full, while B3 stays on one line. The cell to the right of B3 is empty, so the text spills into it; if there were content there, the overflow would simply be cut off.
After running, the effect of setting the wrapping of text:
FAQ
I set IndentLevel and the text is not indented at all?
Cause: Indentation is only displayed when the horizontal alignment is a non-General value such as Left or Right. Cells default to General alignment, and IndentLevel is ignored outright in that case — so setting only the indent level shows no change.
Solution: Set HorizontalAlignment first, then IndentLevel:
// Indentation only takes effect together with left alignment
sheet.Range.get("B2").Style.HorizontalAlignment = xlsModule.HorizontalAlignType.Left;
sheet.Range.get("B3").Style.HorizontalAlignment = xlsModule.HorizontalAlignType.Left;

// Set the indent level of the text
sheet.Range.get("B2").Style.IndentLevel = 1;
sheet.Range.get("B3").Style.IndentLevel = 2;
I want the text stacked vertically, one character per line — why does Rotation = 90 not do it?
Cause: The 0 to 90 and -1 to -90 ranges of Rotation only deal with the rotation angle. 90 merely lays the text on its side; it never breaks it into a column of single characters.
Solution: Stacked text needs the special value 255:
// 90 degrees simply rotates the text
sheet.Range.get("B2").Style.Rotation = 90;

// 255 stacks the text vertically, one character per line
sheet.Range.get("B3").Style.Rotation = 255;
Get a Free License
Spire.XLS for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
PDF keeps its layout stable and is easy to distribute, but the cost is that the content is locked inside the page structure — changing a single word often means redoing the whole layout. Markdown takes a different path: plain text with a clear hierarchy that drops straight into Git repositories and knowledge bases, and is also easy to hand to a large language model for summarization or question answering. Converting a PDF to Markdown is essentially turning the content back into editable, structured text.
Spire.PDF for JavaScript is built on WebAssembly, so PDFs can be loaded, converted and saved entirely in the browser, with input and output managed through a virtual file system (VFS) and no backend service required. There are two entry points for conversion: set the output format of PdfDocument.SaveToFile to FileFormat.Markdown for a one-step result, or use PdfToMarkdownConverter, which exposes MarkdownOptions so you can fine-tune the details of the conversion.
This article covers two core features:
For installation and project configuration, refer to Integrate Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is already installed and the WebAssembly module is initialized.
Convert PDF to Markdown
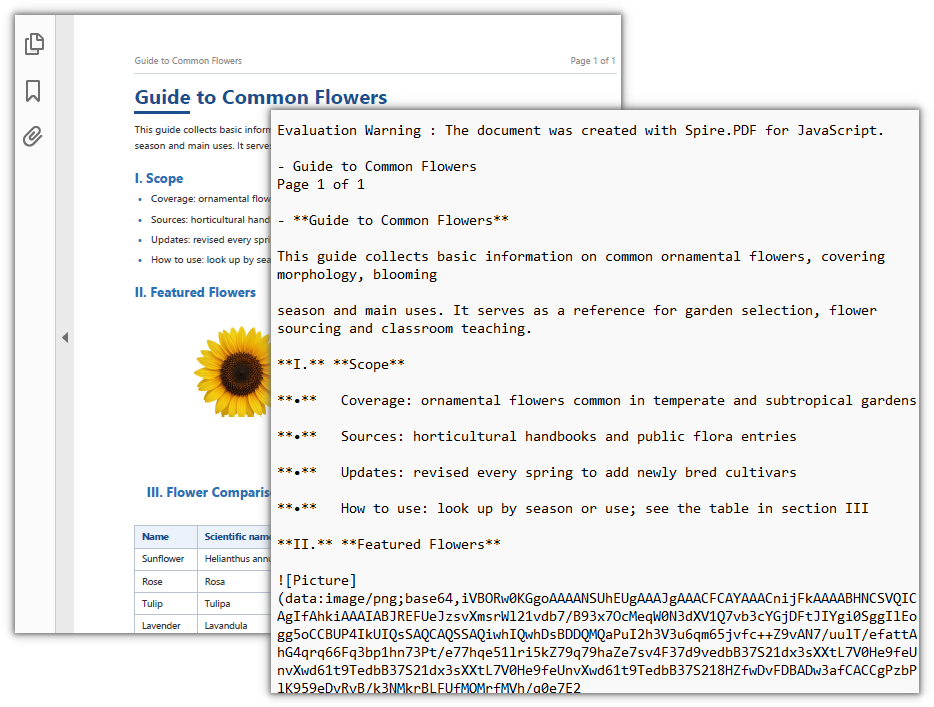
PdfDocument.SaveToFile can also output Markdown: set fileFormat to FileFormat.Markdown, and the headings, paragraphs and lists in the PDF are organized into Markdown text according to their original hierarchy. Images in the document are extracted as well by default.
function App() {
  const convertPdfToMarkdown = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file into the virtual file system
    const inputFileName = 'Flowers.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Load the font into the virtual file system (the WebAssembly environment has no system fonts)
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Create a PdfDocument object and load the PDF
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Define the output file name and convert to Markdown format
    const outputFileName = 'ConvertedResult.md';
    doc.SaveToFile({ fileName: outputFileName, fileFormat: pdfModule.FileFormat.Markdown });
    doc.Close();

    // Read the generated file from the VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/markdown' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF to Markdown</h1>
      <button onClick={convertPdfToMarkdown}>
        Convert
      </button>
    </div>
  );
}

export default App;
Markdown file after converting PDF to Markdown
Convert text only and skip images
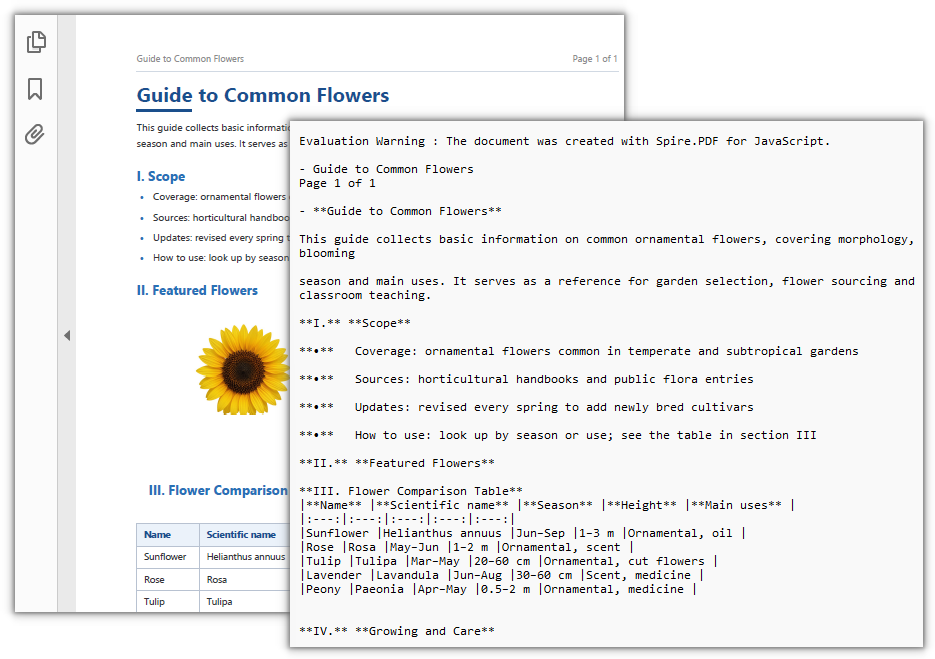
If you only want the text, PdfToMarkdownConverter is more direct. It extracts the images in the document by default; set MarkdownOptions.IgnoreImage to true and the output contains plain text only.
function App() {
  const convertPdfToTextOnlyMarkdown = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file into the virtual file system
    const inputFileName = 'Flowers.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Load the font into the virtual file system (the WebAssembly environment has no system fonts)
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Create the converter and set it to ignore images
    const converter = new pdfModule.PdfToMarkdownConverter(inputFileName);
    converter.MarkdownOptions.IgnoreImage = true;

    // Define the output file name and run the conversion
    const outputFileName = 'TextOnlyResult.md';
    converter.ConvertToMarkdown(outputFileName);
    converter.Dispose();

    // Read the generated file from the VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/markdown' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF to Text-only Markdown</h1>
      <button onClick={convertPdfToTextOnlyMarkdown}>
        Convert
      </button>
    </div>
  );
}

export default App;
Conversion result with text only and images skipped
Frequently Asked Questions
Where do the heading and list levels come from after conversion
Reason: A PDF has no semantic markers such as "heading" or "list" — only individual text fragments with coordinates. The converter has to infer the original structure from layout clues such as font size, font weight, indentation and line spacing.
Solution: Spire.PDF judges the levels from those clues and outputs the corresponding Markdown markers. If the source document has a loose layout (for example, distinguishing headings with spaces instead of actual font size differences), the inferred result may be poor. In that case, adjust the layout of the source PDF first, or proofread the converted output manually:
// Load the PDF and convert it to Markdown for inspection
let doc = new pdfModule.PdfDocument();
doc.LoadFromFile(inputFileName);
doc.SaveToFile({ fileName: outputFileName, fileFormat: pdfModule.FileFormat.Markdown });
doc.Close();
Why are the images gone after I set IgnoreImage
Reason: MarkdownOptions.IgnoreImage means exactly "skip images during conversion". Once it is set to true, images are neither extracted as separate files nor referenced in the Markdown output.
Solution: If you want both the text and the images, remove the property or set it to false, and the converter will handle images as usual:
// Keep images (default behavior)
const converter = new pdfModule.PdfToMarkdownConverter(inputFileName);
converter.MarkdownOptions.IgnoreImage = false;
converter.ConvertToMarkdown(outputFileName);
converter.Dispose();
The conversion of a scanned document comes out blank
Reason: A scanned document is a full-page image with no text layer, so the converter can extract no text from it and the output is nearly empty.
Solution: Such PDFs need OCR first to recognize the image into a text layer, and only then can Spire.PDF convert them. The check is simple: open the file in a reader and try to select the text. If nothing can be selected, it is a scanned document:
// Read the result back from the VFS to confirm whether text was actually produced
const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
console.log('Output size:', fileArray.length, 'bytes');
Get a Free License
If you would like to remove the evaluation message from the result document or lift feature restrictions, please contact sales for a 30-day temporary license.
The same PDF can look different to everyone who opens it: one viewer starts centered, another pins the toolbar and menu bar to the top, one shows a single page at a time, another puts two pages side by side. When the document is a manual, a brochure, or a report meant for other people, the author usually wants control over those defaults — centered on open, minimal interface, straight into a two-column view. This behavior comes from the document's own viewer preferences, written into the PDF catalog and shipped with the file, so no viewer-side configuration is needed.
Spire.PDF for JavaScript loads, modifies, and saves PDF documents in the browser through WebAssembly. Viewer preferences are read and written through PdfDocument.ViewerPreferences, and files move in and out through a virtual file system (VFS), with no backend involved.
This article covers two features:
For installation and project setup, see Integrate Spire.PDF for JavaScript in a React project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Set window and interface preferences
A few boolean switches on ViewerPreferences decide how the reader looks when it opens the document. All of them default to false, which leaves the reader's own interface untouched:
CenterWindowcenters the reader windowDisplayTitledecides whether the title bar uses the document title (with no title metadata in the document, the reader falls back to the file name)FitWindowdecides whether the window is scaled to fit the first pageHideMenubarhides the menu barHideToolbarhides the toolbarHideWindowUIhides interface elements such as scroll bars, leaving only the page content
function App() {
  const setWindowPreferences = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to process into the VFS
    const inputFileName = 'FinancialStatement2025.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Center the reader window
    doc.ViewerPreferences.CenterWindow = true;
    // Do not use the document title in the title bar (keep showing the file name)
    doc.ViewerPreferences.DisplayTitle = false;
    // Do not scale the window to fit the first page
    doc.ViewerPreferences.FitWindow = false;
    // Hide the menu bar
    doc.ViewerPreferences.HideMenubar = true;
    // Hide the toolbar
    doc.ViewerPreferences.HideToolbar = true;
    // Hide interface elements such as scroll bars, leaving only the page content
    doc.ViewerPreferences.HideWindowUI = true;

    const outputFileName = 'WindowPreferences.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Window and Interface Preferences</h1>
      <button onClick={setWindowPreferences}>
        Apply
      </button>
    </div>
  );
}

export default App;
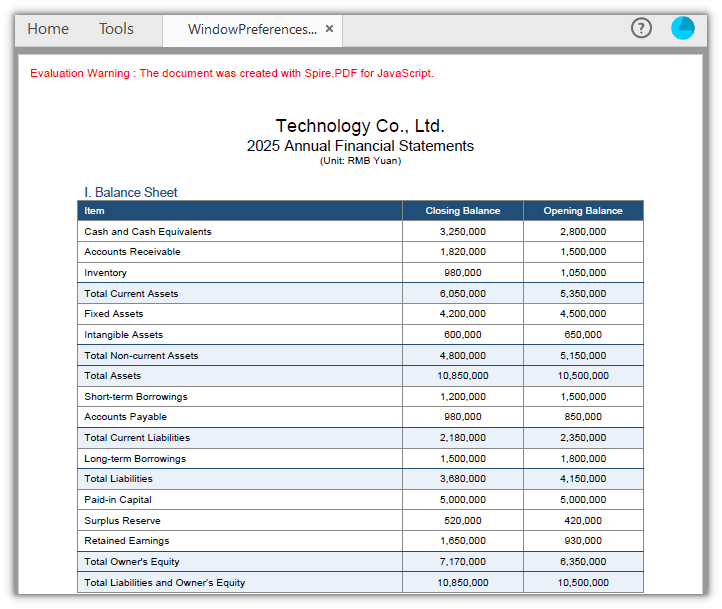
A PDF document with the window centered and the toolbar and menu bar hidden
Set page layout and opening display mode
How pages are arranged, and what appears first on open, are also decided by enum properties on ViewerPreferences. Their defaults are SinglePage and UseNone:
PageLayoutcontrols how pages are arranged:SinglePageshows one page at a time,TwoColumnLeftputs two pages side by side with odd-numbered pages on the leftPageModecontrols what the document shows first:UseNonegoes straight to the page content,UseThumbsexpands a thumbnail panel in the sidebar
function App() {
  const setPageLayout = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to process into the VFS
    const inputFileName = 'FinancialStatement2025.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Show two pages side by side, with odd-numbered pages on the left
    doc.ViewerPreferences.PageLayout = pdfModule.PdfPageLayout.TwoColumnLeft;
    // Expand the thumbnail panel when the document opens
    doc.ViewerPreferences.PageMode = pdfModule.PdfPageMode.UseThumbs;

    const outputFileName = 'PageLayoutSettings.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Page Layout and Display Mode</h1>
      <button onClick={setPageLayout}>
        Apply
      </button>
    </div>
  );
}

export default App;
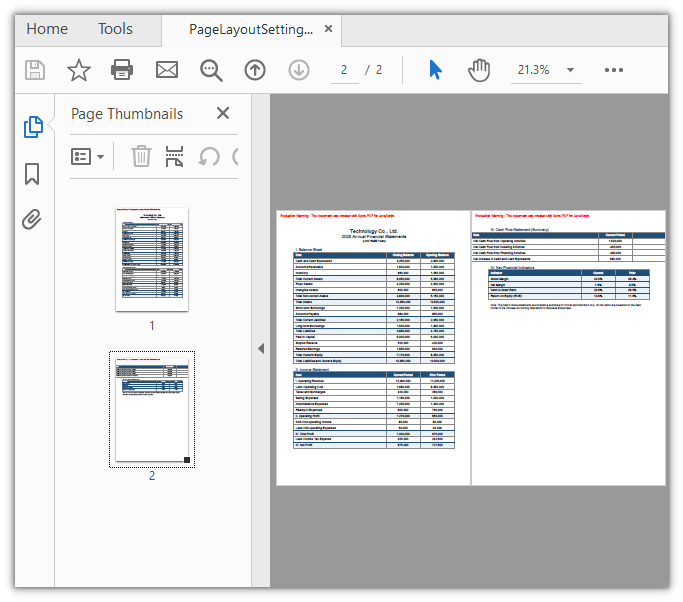
A PDF document that opens in two columns with the thumbnail panel expanded on the left
FAQ
I set the preferences but the document looks the same on open
Cause: Per the PDF specification, /ViewerPreferences is a hint to the reader, not a requirement. The built-in browser PDF viewers and many lightweight readers implement only a small part of it, and interface entries such as HideToolbar, HideMenubar, and PageLayout are often ignored outright. Adobe Acrobat also overrides the document values with the view state it remembers when "Restore last view settings" is turned on.
Solution: Open the file in Adobe Acrobat Reader to verify, and in Preferences → Documents make sure "Restore last view settings when reopening documents" is cleared. When troubleshooting, rule out the reader itself first, then check whether the settings made it into the file — the preferences only reach disk after SaveToFile, and calling Close() before saving discards the changes.
What is the difference between PageLayout and PageMode
Cause: The two property names are close and both affect how the document looks on open, so they are easy to mix up. They govern different things: PageLayout decides how pages are arranged, PageMode decides which panel shows first.
Solution: Pick one value for each as needed; the two do not affect each other:
// Page arrangement: single page, continuous single column, two columns, two pages
doc.ViewerPreferences.PageLayout = pdfModule.PdfPageLayout.TwoColumnLeft;

// Panel shown first on open: pages only, thumbnails, bookmark outlines
doc.ViewerPreferences.PageMode = pdfModule.PdfPageMode.UseThumbs;
PdfPageLayout accepts SinglePage, OneColumn, TwoColumnLeft, TwoColumnRight, TwoPageLeft, and TwoPageRight; PdfPageMode accepts UseNone, UseOutlines, UseThumbs, FullScreen, UseOC, and UseAttachments.
Can hiding the toolbar stop users from printing or saving a copy
Cause: No. HideToolbar, HideMenubar, and HideWindowUI only affect how the reader interface is displayed; they have nothing to do with the permissions for printing, copying, or saving a copy. Opening the file in a reader that ignores the setting, or using the menu directly, still allows both.
Solution: Restricting operations takes a permissions password — use PdfPasswordSecurityPolicy together with PdfDocumentPrivilege to turn off printing, copying, and the like. Those restrictions are enforced by the document's encryption dictionary, and readers honor them. Viewer preferences govern how it looks; permission settings govern what is allowed.
Get a Free License
If you want to remove the evaluation message from the result document or lift the feature limits, contact sales for a temporary 30-day license.
Order numbers, tracking numbers, and asset IDs are easy to mistype when someone enters them by hand. Printing them as barcodes on the document lets a scanner read them in one pass and brings the error rate down. Getting a barcode onto a PDF from a web app used to mean generating a barcode image on the server and compositing it back into the document, which sends the file on a round trip.
Spire.PDF for JavaScript creates, modifies, and saves PDF documents in the browser through WebAssembly. Barcodes are drawn straight onto the page by 1D barcode objects such as PdfCode128BBarcode and PdfCode39Barcode, and files are read and written through a virtual file system (VFS), so the document never has to be uploaded to a server.
This article covers two features:
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The following examples assume Spire.PDF is installed and the WebAssembly module has been initialized.
Supported barcode types
The ten 1D barcode classes all derive from PdfBarcode; they differ in the characters they accept and in how densely they encode, so use the table below to pick one:
| Class | Symbology | Characters supported |
|---|---|---|
PdfCodabarBarcode |
Codabar | Digits and - $ : / . + |
PdfCode11Barcode |
Code 11 | Digits and - |
PdfCode32Barcode |
Code 32 | Digits, common in pharmaceutical codes |
PdfCode39Barcode |
Code 39 | Digits, uppercase letters, space and - . $ / + % |
PdfCode39ExtendedBarcode |
Code 39 Extended | Full ASCII, represented by multi-character combinations |
PdfCode93Barcode |
Code 93 | Same character set as Code 39, higher density |
PdfCode93ExtendedBarcode |
Code 93 Extended | Full ASCII |
PdfCode128ABarcode |
Code 128A | Digits, uppercase letters, symbols and control characters |
PdfCode128BBarcode |
Code 128B | Digits, upper- and lowercase letters and symbols |
PdfCode128CBarcode |
Code 128C | Digits in pairs, the highest density |
function App() {
  const drawBarcodeTypes = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the font file into the VFS for the type name above each barcode
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Create the PDF document and add a page
    const doc = new pdfModule.PdfDocument();
    const page = doc.Pages.Add();

    // Font, color, and alignment for the type names; green sets them apart from the black bars
    const labelFont = new pdfModule.PdfTrueTypeFont({ fontFile: '/Library/Fonts/ARIAL.TTF', size: 12 });
    const labelBrush = new pdfModule.PdfSolidBrush({ pdfRGBColor: new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_Green() }) });
    const labelFormat = new pdfModule.PdfStringFormat({ alignment: pdfModule.PdfTextAlignment.Left });

    // The data to encode, the barcode class to use for each, and the type name shown above it
    const items = [
      { Barcode: pdfModule.PdfCodabarBarcode, label: 'Codabar', text: '00:12-3456/7890' },
      { Barcode: pdfModule.PdfCode11Barcode, label: 'Code 11', text: '123-4567890' },
      { Barcode: pdfModule.PdfCode32Barcode, label: 'Code 32', text: '16273849' },
      { Barcode: pdfModule.PdfCode39Barcode, label: 'Code 39', text: 'ORDER-2026-0007' },
      { Barcode: pdfModule.PdfCode39ExtendedBarcode, label: 'Code 39 Extended', text: 'Order 2026-0007' },
      { Barcode: pdfModule.PdfCode93Barcode, label: 'Code 93', text: 'ORDER-2026-0007' },
      { Barcode: pdfModule.PdfCode93ExtendedBarcode, label: 'Code 93 Extended', text: 'Order 2026-0007' },
      { Barcode: pdfModule.PdfCode128ABarcode, label: 'Code 128A', text: 'INVOICE 2026' },
      { Barcode: pdfModule.PdfCode128BBarcode, label: 'Code 128B', text: 'Order-2026-0001' },
      { Barcode: pdfModule.PdfCode128CBarcode, label: 'Code 128C', text: '20260001' },
    ];

    // Draw from the top of the page, one below the other
    let y = 20;
    for (const item of items) {
      // Label the barcode above it with the symbology it uses
      page.Canvas.DrawString({ s: `${item.label}:`, font: labelFont, brush: labelBrush, x: 20, y: y, format: labelFormat });

      // Create the barcode object from the text to encode
      const barcode = new item.Barcode({ text: item.text });

      // Show the readable text below the barcode
      barcode.TextDisplayLocation = pdfModule.TextLocation.Bottom;

      // Narrow the bars so all ten barcodes fit on one page
      barcode.BarHeight = 25;

      // Draw below the type name; this coordinate is the top-left corner of the barcode
      barcode.Draw({ page: page, location: new pdfModule.PointF(20, y + labelFont.Size + 4) });

      // Use the bottom edge of the area actually occupied to place the next one
      y = barcode.Bounds.Bottom + 10;
    }

    // Save the document
    const outputFileName = 'BarcodeTypes_result.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Drawing Multiple Barcode Types</h1>
      <button onClick={drawBarcodeTypes}>
        Draw Barcodes
      </button>
    </div>
  );
}

export default App;
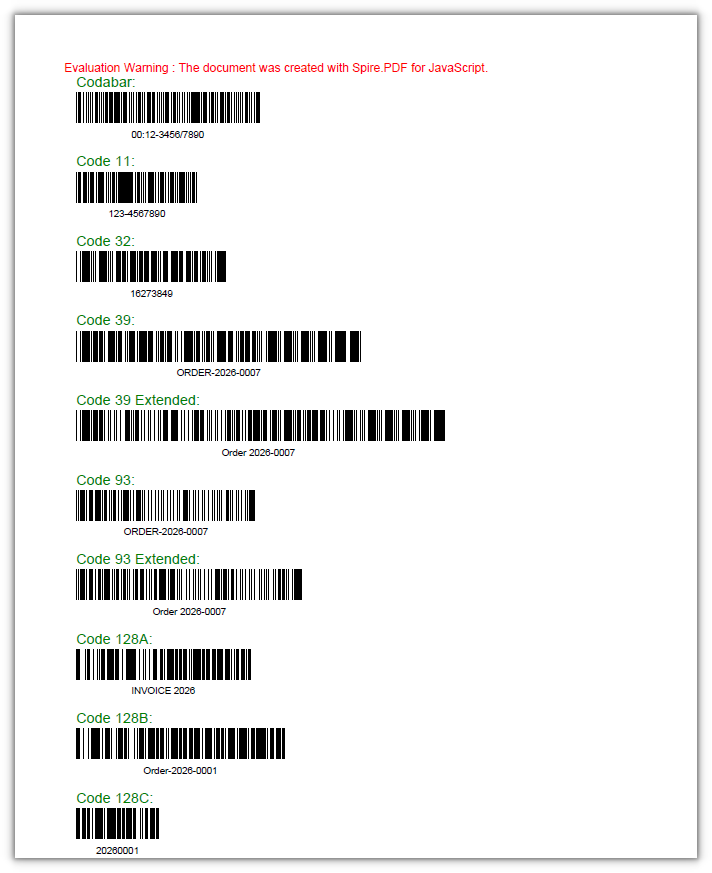
Ten barcode types on one page, each labeled above with its symbology and below with the readable text
Customizing the barcode appearance
The default look is black bars on white with the text underneath, and each part of it can be overridden, from the colors and the bar height to the quiet zone and the label font. BarColor and TextColor color the bars and the text separately, BackColor fills the area behind the barcode, BarHeight, NarrowBarWidth, and BarcodeToTextGapHeight control the dimensions, and QuietZone is the blank space the barcode needs around it.
function App() {
  const customizeBarcode = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the font file into the VFS for the barcode label
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Create the PDF document and add a page
    const doc = new pdfModule.PdfDocument();
    const page = doc.Pages.Add();

    // The first barcode keeps the default look, for comparison
    const plain = new pdfModule.PdfCode39Barcode({ text: 'ORDER-2026-0007' });
    plain.TextDisplayLocation = pdfModule.TextLocation.Bottom;
    plain.Draw({ page: page, location: new pdfModule.PointF(20, 20) });

    // The second one has each property set explicitly
    const barcode = new pdfModule.PdfCode39Barcode({ text: 'ORDER-2026-0007' });
    barcode.TextDisplayLocation = pdfModule.TextLocation.Bottom;

    // Set the bars, the text, and the background separately
    barcode.BarColor = new pdfModule.PdfRGBColor({ color: pdfModule.Color.FromArgb(0, 60, 160) });
    barcode.TextColor = new pdfModule.PdfRGBColor({ color: pdfModule.Color.FromArgb(200, 0, 0) });
    barcode.BackColor = new pdfModule.PdfRGBColor({ color: pdfModule.Color.FromArgb(255, 255, 0) });

    // Bar height, narrow bar width, and the gap between the bars and the text
    barcode.BarHeight = 45;
    barcode.NarrowBarWidth = 1.6;
    barcode.BarcodeToTextGapHeight = 4;

    // Center the text and leave 5 points of blank space on each side
    barcode.TextAlignment = pdfModule.PdfBarcodeTextAlignment.Center;
    barcode.QuietZone.Top = 5;
    barcode.QuietZone.Bottom = 5;
    barcode.QuietZone.Left = 5;
    barcode.QuietZone.Right = 5;

    // Switch the label to 12-point Arial
    barcode.Font = new pdfModule.PdfTrueTypeFont({ fontFile: '/Library/Fonts/ARIAL.TTF', size: 12 });

    // Place it below the first barcode
    barcode.Draw({ page: page, location: new pdfModule.PointF(20, plain.Bounds.Bottom + 30) });

    // Save the document
    const outputFileName = 'CustomBarcodeStyle_result.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Customizing the Barcode Style</h1>
      <button onClick={customizeBarcode}>
        Apply Styling
      </button>
    </div>
  );
}

export default App;
The lower barcode uses different bar colors, bar height, quiet zone, and label font
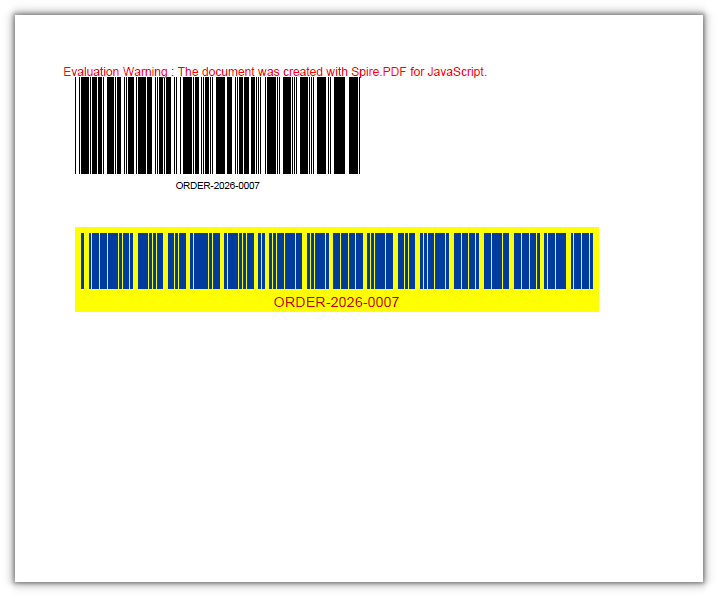
FAQ
PdfRGBColor reports "Ambiguous call" when it is constructed
Cause: the constructor of PdfRGBColor only accepts a Color object. Passing the three RGB components directly, as in new pdfModule.PdfRGBColor(0, 60, 160) or { r: 0, g: 60, b: 160 }, matches several overloads and throws Ambiguous call: arguments (object) match multiple overloads.
Solution: build a Color with Color.FromArgb first, then hand it to PdfRGBColor:
// Correct: produce a Color object first
barcode.BarColor = new pdfModule.PdfRGBColor({ color: pdfModule.Color.FromArgb(0, 60, 160) });

// A predefined color works too
barcode.TextColor = new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_Blue() });
The same data produces barcodes of different lengths
Cause: symbologies encode at different densities, so the same text comes out shorter with Code128 than with Code39, and shorter still with Code128C. Raising NarrowBarWidth widens the whole barcode as well.
Solution: when the layout has to be fixed, use the Draw overload that takes a RectangleF to confine the barcode to an area, or adjust NarrowBarWidth across the board:
// However long the data is, the barcode stays inside the same rectangle
barcode.Draw({ page: page, rect: new pdfModule.RectangleF(20, 20, 250, 80) });
Can I add a QR code to a PDF
Cause: the 1D barcode classes Spire.PDF for JavaScript ships are PdfCodabarBarcode, PdfCode39Barcode, PdfCode128BBarcode, and the like. There is no QR code class, so a name such as PdfQRCodeBarcode evaluates to undefined.
Solution: generate the QR code as an image in the front end, then draw it into the page with PdfImage.FromStream and page.Canvas.DrawImage, leaving positioning and scaling to the canvas:
// qrBytes holds the PNG bytes of a QR code generated in the front end
const image = pdfModule.PdfImage.FromStream(new pdfModule.Stream(qrBytes));
page.Canvas.DrawImage({ image: image, x: 20, y: 20, width: 100, height: 100 });
Get a Free License
If you want to remove the evaluation message from the resulting documents, or to get rid of the feature limitations, please contact our sales team to obtain a temporary license valid for 30 days.
Detecting PDF Encryption and Verifying the Correct Password in React with JavaScript
2026-09-17 03:09:27 Written by Nina TangSome of the PDFs users upload are password protected. If the code processes them without checking first, it either throws and stops, or writes out an incomplete result. Checking at the entry point is cheaper than debugging afterwards: is the document encrypted, which password does it need, and are the candidate passwords in hand correct?
Spire.PDF for JavaScript reads PDF documents in the browser through WebAssembly and manages input files in a virtual file system (VFS), so no backend is involved. PdfDocument.IsPasswordProtected() is a static method: it reads the file directly, without opening the document and without a password. Once a document is loaded, PdfDocument.Security records whether the password used this time is in UserPassword or OwnerPassword, which identifies the role of that password.
This article covers three features:
- Checking whether a PDF is password protected
- Checking whether a document requires an open password
- Verifying candidate passwords and confirming the password role
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The following examples assume Spire.PDF is installed and the WebAssembly module has been initialized.
Checking whether a PDF is password protected
PdfDocument.IsPasswordProtected() takes a file name in the virtual file system and returns a boolean. It checks whether the document carries an encryption dictionary, so it needs neither an opened document nor a password. It reads a path inside the virtual file system, so window.spire.FetchFileToVFS() must run first; otherwise it throws File doesn't exist.
function App() {
  const checkPasswordProtection = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // File names to check
    const plainFileName = 'ContractTemplate.pdf';
    const lockedFileName = 'EncryptedContract.pdf';

    // The static method reads the virtual file system, so load the files first
    await window.spire.FetchFileToVFS(plainFileName, "", `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS(lockedFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Check each file without opening the document or supplying a password
    const reportLines = [];
    for (const fileName of [plainFileName, lockedFileName]) {
      const isProtected = pdfModule.PdfDocument.IsPasswordProtected(fileName);
      reportLines.push(`${fileName}: ${isProtected ? 'password protected' : 'not encrypted'}`);
    }

    // Write the report into the virtual file system, then export it
    const outputFileName = 'EncryptionCheckResult.txt';
    const report = reportLines.join('\r\n');
    window.dotnetRuntime.Module.FS.writeFile(outputFileName, new TextEncoder().encode(report));

    // Read the generated file back from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/plain;charset=utf-8' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Checking Whether a PDF Is Password Protected</h1>
      <button onClick={checkPasswordProtection}>
        Run Check
      </button>
    </div>
  );
}

export default App;
Exported report: ContractTemplate.pdf is not encrypted, EncryptedContract.pdf is password protected
Checking whether a document requires an open password
IsPasswordProtected() returning true only means the document carries an encryption dictionary, not that a password is required to open it: a document with only a permission password still opens without one. To tell the two apart, call LoadFromFile() once without a password. A thrown exception means an open password is missing; a successful load means the document is merely restricted.
function App() {
  const checkOpenPassword = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // File names to check
    const fileNames = ['ContractTemplate.pdf', 'EncryptedContract.pdf'];
    for (const fileName of fileNames) {
      await window.spire.FetchFileToVFS(fileName, "", `${process.env.PUBLIC_URL}/data/`);
    }

    // Load without a password: a thrown exception means an open password is required
    const reportLines = [];
    for (const fileName of fileNames) {
      try {
        const doc = new pdfModule.PdfDocument();
        doc.LoadFromFile(fileName);
        reportLines.push(`${fileName}: ${doc.IsEncrypted ? 'opens directly, but the document is still restricted by permissions' : 'not encrypted, opens directly'}`);
        doc.Close();
      } catch (error) {
        reportLines.push(`${fileName}: open password required`);
      }
    }

    // Write the report into the virtual file system, then export it
    const outputFileName = 'OpenPasswordCheck.txt';
    const report = reportLines.join('\r\n');
    window.dotnetRuntime.Module.FS.writeFile(outputFileName, new TextEncoder().encode(report));

    // Read the generated file back from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/plain;charset=utf-8' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Checking Whether a Document Requires an Open Password</h1>
      <button onClick={checkOpenPassword}>
        Run Check
      </button>
    </div>
  );
}

export default App;
Exported result: ContractTemplate.pdf opens directly, EncryptedContract.pdf requires an open password
Verifying candidate passwords and confirming the password role
Whether a password is correct is answered by whether LoadFromFile() loads successfully. On failure it always throws Can not open an encrypted document. The password is invalid., without distinguishing "no password supplied" from "wrong password". So check first whether the document is encrypted, skip the ones that are not, try passwords one by one on the encrypted ones, then read PdfDocument.Security to see whether the password used this time landed in UserPassword or OwnerPassword and confirm whether it is the open password or the permission password.
function App() {
  const verifyPassword = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Files to verify and candidate passwords
    const fileNames = ['ContractTemplate.pdf', 'EncryptedContract.pdf'];
    const candidates = ['wrong123', 'spire123', 'owner123'];

    // Both the static method and loading read the virtual file system, so load the files first
    for (const fileName of fileNames) {
      await window.spire.FetchFileToVFS(fileName, "", `${process.env.PUBLIC_URL}/data/`);
    }

    const reportLines = [];
    for (const fileName of fileNames) {
      // An unencrypted document needs no password verification
      if (!pdfModule.PdfDocument.IsPasswordProtected(fileName)) {
        reportLines.push(`${fileName}: this PDF document is not encrypted, no password verification needed`);
        continue;
      }

      // Encrypted: try each candidate; loading successfully means the password is correct
      for (const password of candidates) {
        try {
          const doc = new pdfModule.PdfDocument();
          doc.LoadFromFile(fileName, password);

          // Security records the password used this time, which gives its role
          const role = doc.Security.UserPassword ? 'open password' : 'permission password';
          reportLines.push(`${fileName}: password "${password}" is correct (${role})`);
          doc.Close();
        } catch (error) {
          reportLines.push(`${fileName}: password "${password}" is incorrect`);
        }
      }
    }

    // Write the report into the virtual file system, then export it
    const outputFileName = 'PasswordVerificationResult.txt';
    const report = reportLines.join('\r\n');
    window.dotnetRuntime.Module.FS.writeFile(outputFileName, new TextEncoder().encode(report));

    // Read the generated file back from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/plain;charset=utf-8' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Verifying Candidate Passwords and Confirming the Password Role</h1>
      <button onClick={verifyPassword}>
        Run Verification
      </button>
    </div>
  );
}

export default App;
Exported result: the incorrect password is rejected, spire123 is the open password, owner123 is the permission password
FAQ
IsPasswordProtected() throws File doesn't exist
Cause: the method reads a path inside the virtual file system, not an address the browser can fetch directly. When the file has not been loaded into the virtual file system, Spire.PDF cannot find the target and throws File doesn't exist Arg_ParamName_Name, fileName.
Solution: load the file into the virtual file system with FetchFileToVFS before calling the method, using the same name you pass afterwards:
// Load into the virtual file system first, then check
await window.spire.FetchFileToVFS('EncryptedContract.pdf', "", `${process.env.PUBLIC_URL}/data/`);
const isProtected = pdfModule.PdfDocument.IsPasswordProtected('EncryptedContract.pdf');
The document needs a password, but the error says the password is invalid
Cause: Spire.PDF returns the same message, Can not open an encrypted document. The password is invalid., for "no password supplied" and for "wrong password". The error text alone cannot tell them apart.
Solution: work in three steps. Use IsPasswordProtected() to check whether the document carries an encryption dictionary, load it without a password to separate "open password required" from "restricted by permissions only", and only then try candidate passwords, deciding correctness by whether an exception is thrown:
// Loading without a password fails → an open password is required; retry with a password → a throw means a miss
try {
  const doc = new pdfModule.PdfDocument();
  doc.LoadFromFile(fileName, password);
  // Loaded: read Security to confirm the role
} catch (error) {
  // Failed to load: this password does not work
}
Reading Security.Permissions after loading throws
Cause: the permission bits are a combination of several flags and do not necessarily match a member of the PdfPermissionsFlags enumeration, so reading them throws Invalid value for spirepdfPdfPermissionsFlags. In the same version, HasExtendedRight() throws ArgumentNullException as well.
Solution: use Security.UserPassword and Security.OwnerPassword instead to determine the role of the password used this time. A document loaded with the permission password carries all permissions, so Decrypt() can remove the protection directly; a document loaded with the open password needs the permission password supplied separately. To control permissions precisely, set them with PdfDocumentPrivilege while encrypting and keep a record yourself:
const role = doc.Security.UserPassword ? 'open password' : 'permission password';

// Loaded with the permission password: the protection can be removed directly
if (role === 'permission password') {
  doc.Decrypt();
}
Get a Free License
If you want to remove the evaluation message from the resulting documents, or to get rid of the feature limitations, please contact our sales team to obtain a temporary license valid for 30 days.
Encrypting or Decrypting PDF Documents in React with JavaScript
2026-09-17 03:04:45 Written by Nina TangOnce a contract, a quotation or a financial statement leaves the office as a PDF, its content is essentially wide open — anyone can open it, save a copy, edit it and send it on. Setting a password, or allowing reading only while switching off printing and copying, is the most direct way to close that gap at the distribution stage. Doing this used to mean either desktop software, which is hard to embed in a web workflow, or uploading the file to a server, which means the document leaves the user's device.
Spire.PDF for JavaScript loads, modifies and saves PDF documents directly in the browser based on WebAssembly, so the whole encryption process runs locally and reads and writes files through a virtual file system (VFS), with no backend service required.
This article covers three core features:
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The following examples assume Spire.PDF is installed and the WebAssembly module has been initialized.
Encrypting a PDF Document
The constructor of PdfPasswordSecurityPolicy takes two arguments: a user password and an owner password. Whoever receives the document needs the first one to open it; the second stays with the document owner and is used to lift the restrictions later. The algorithm is set through EncryptionAlgorithm, here AES-128; DocumentPrivilege decides which operations are allowed once the document is open, and get_AllowAll() grants all of them.
function App() {
  const encryptPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be encrypted into the VFS
    const inputFileName = 'ContractTemplate.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Create the password security policy: the first argument is the user password, the second the owner password
    const policy = new pdfModule.PdfPasswordSecurityPolicy('spire123', 'owner123');

    // Specify the encryption algorithm
    policy.EncryptionAlgorithm = pdfModule.PdfEncryptionAlgorithm.AES_128;

    // Specify the privileges: get_AllowAll() means no operation is restricted
    policy.DocumentPrivilege = pdfModule.PdfDocumentPrivilege.get_AllowAll();

    // Apply the policy and save the document
    doc.Encrypt(policy);
    const outputFileName = 'Encrypted.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Encrypt a PDF</h1>
      <button onClick={encryptPdf}>
        Start Encrypting
      </button>
    </div>
  );
}

export default App;
The PDF document after a user password and an owner password are set
Restricting the Permissions of a PDF Document
Leave the user password empty and set only an owner password, and the document opens without a password while printing, copying and editing are granted or forbidden item by item — a good fit for distribution scenarios where the file may be read but not taken away. The permissions themselves are described by PdfDocumentPrivilege: start from a fully permissive baseline, then switch off what is not needed. Here printing, copying content and modifying content are switched off.
function App() {
  const restrictPdfPermissions = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be processed into the VFS
    const inputFileName = 'ContractTemplate.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Leave the user password empty: the document opens directly; the owner password lifts the restrictions later
    const policy = new pdfModule.PdfPasswordSecurityPolicy('', 'owner123');
    policy.EncryptionAlgorithm = pdfModule.PdfEncryptionAlgorithm.AES_128;

    // Start from full permissions and switch off the ones that are not needed
    const privilege = pdfModule.PdfDocumentPrivilege.get_AllowAll();
    privilege.AllowPrint = false;
    privilege.AllowContentCopying = false;
    privilege.AllowModifyContents = false;
    policy.DocumentPrivilege = privilege;

    // Apply the policy and save the document
    doc.Encrypt(policy);
    const outputFileName = 'PermissionRestricted.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Restrict PDF Permissions</h1>
      <button onClick={restrictPdfPermissions}>
        Start Restricting
      </button>
    </div>
  );
}

export default App;
A PDF document that opens without a password but whose printing, copying and editing are forbidden
Decrypting a PDF Document
Decryption means removing the existing password protection, and it presupposes that the password is at hand. If only the user password is available, Decrypt needs the owner password as well before the restrictions can be lifted; calling the parameterless Decrypt() with just the user password is rejected.
function App() {
  const decryptPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be decrypted into the VFS
    const inputFileName = 'EncryptedContract.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the encrypted document with its user password
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName, 'spire123');

    // Confirm that the document really is password protected
    if (!doc.IsEncrypted) {
      alert('This document is not encrypted, no decryption needed');
      return;
    }

    // Remove the protection with the owner password
    doc.Decrypt('owner123');

    const outputFileName = 'Decrypted.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Decrypt a PDF</h1>
      <button onClick={decryptPdf}>
        Start Decrypting
      </button>
    </div>
  );
}

export default App;
The PDF document after the password protection is removed, ready to open directly
FAQ
Opening an encrypted document reports an invalid password
Reason: LoadFromFile was called without a password, or the password passed in does not match the user password of the document. In that case Spire.PDF throws Can not open an encrypted document. The password is invalid. instead of returning an empty PdfDocument.
Solution: Pass the user password as the second argument of LoadFromFile:
// The second argument is the user password
doc.LoadFromFile(inputFileName, 'spire123');
Calling Decrypt() reports "Cannot decrypt documents without permission password"
Reason: The document was loaded with the user password, so only reading rights are available. Removing the encryption is an owner-level operation and requires the owner password (also called the permissions password).
Solution: Both forms work — load with the owner password and call the parameterless Decrypt(), or keep the user password for loading and hand the owner password to Decrypt:
// Form 1: load with the owner password, then remove the protection directly
doc.LoadFromFile(inputFileName, 'owner123');
doc.Decrypt();

// Form 2: load with the user password and pass the owner password to Decrypt
doc.LoadFromFile(inputFileName, 'spire123');
doc.Decrypt('owner123');
Which encryption algorithm should I choose
Reason: PdfEncryptionKeySize and PdfEncryptionAlgorithm list RC4_40, RC4_128, AES_128, AES_256 and more, but the WebAssembly build that runs in the browser does not support AES-256 yet — setting EncryptionAlgorithm to AES_256 throws Cryptography_AlgorithmNotSupported.
Solution: Use AES_128 on the web; when a legacy reader that only understands RC4 really has to be supported, switch to RC4_128:
// Recommended on the web: AES-128
policy.EncryptionAlgorithm = pdfModule.PdfEncryptionAlgorithm.AES_128;

// For legacy readers: RC4-128
policy.EncryptionAlgorithm = pdfModule.PdfEncryptionAlgorithm.RC4_128;
Get a Free License
If you wish to remove the evaluation message from the result document or remove feature limitations, please contact sales to obtain a temporary license valid for 30 days.
