
Knowledgebase (2595)
Children categories
How to Flatten a PDF in C#: Form Fields, Annotations & Layers
2026-10-12 06:19:50 Written by Allen Yang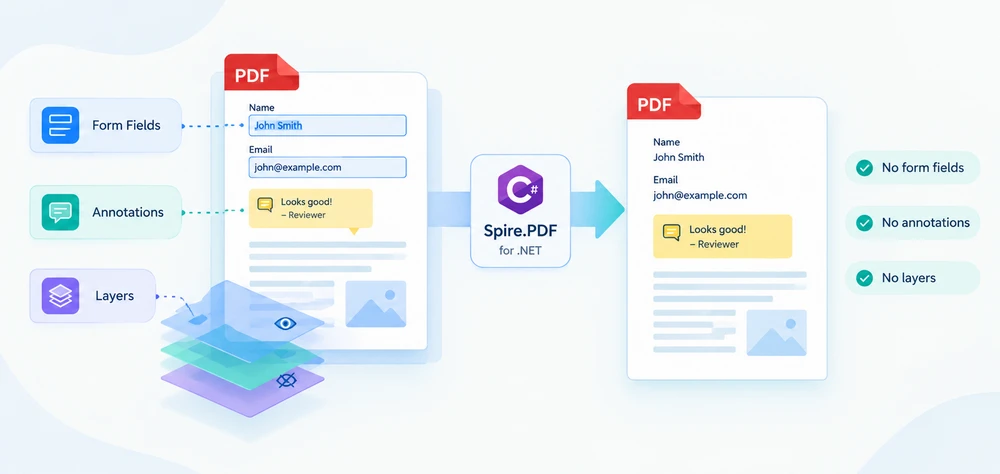
Flattening a PDF converts interactive objects into fixed page content. A filled-in form field loses its input control and keeps its value as text, a reviewer's comment becomes part of the page appearance, and optional-content layers are removed by rebuilding each page from its currently visible content. This makes the document less dependent on the interactive features of individual PDF viewers, although the page content itself can still be edited in a PDF editor.
This guide flattens a PDF in C# with Spire.PDF for .NET: the whole form at once, selected fields only, every annotation on every page, and layers by rebuilding each page through SVG. It closes with a verification step, because a flattened file looks very much like the original — the difference is structural, not visual.
Quick Navigation
- Install Spire.PDF for .NET
- What Flattening a PDF Does
- Flatten the Entire PDF Form
- Flatten Selected PDF Form Fields
- Flatten PDF Annotations and Comments
- Flatten PDF Layers Through SVG
- Flatten a PDF Before Printing
- Verify the Flattened PDF
- Putting It Together
- FAQ
- Conclusion
Install Spire.PDF for .NET
Spire.PDF for .NET is available as a NuGet package. Install it using the .NET CLI:
dotnet add package Spire.PDF
These examples were built with Spire.PDF for .NET 12.9.18.
You can also download Spire.PDF for .NET and add it to your project manually.
Three namespaces matter for flattening:
| Namespace | What lives there |
|---|---|
Spire.Pdf |
PdfDocument, PdfPageBase, FileFormat |
Spire.Pdf.Widget, Spire.Pdf.Fields |
PdfFormWidget and PdfField — the form side |
Spire.Pdf.Interactive.Annotations |
PdfAnnotation, PdfAnnotationCollection — the annotation side, including Flatten() |
What Flattening a PDF Does
Flattening presses the appearance of an interactive object into the page content and removes the object. The goal is to preserve the visible appearance while removing the interactivity — which is why this guide counts the objects left in the saved file instead of comparing screenshots.
Each object type needs its own call:
| Object | Flattened with |
|---|---|
| Form fields (text boxes, check boxes, list boxes, combo boxes) | PdfForm.IsFlatten for the whole form, PdfField.Flatten for one field |
| Annotations (comments, highlights, stamps, free text) | PdfAnnotation.Flatten() on each annotation |
| Layers (optional content groups) | PDF → SVG → PDF conversion, which rebuilds every page from what is visible |
Flatten the Entire PDF Form
Set Form.IsFlatten to true and every field in the document is converted in one pass:
using Spire.Pdf;

PdfDocument pdf = new PdfDocument();
pdf.LoadFromFile("FillableForm.pdf");

// Every field and its current value becomes page content.
pdf.Form.IsFlatten = true;

pdf.SaveToFile("FlattenedForm.pdf");
pdf.Close();
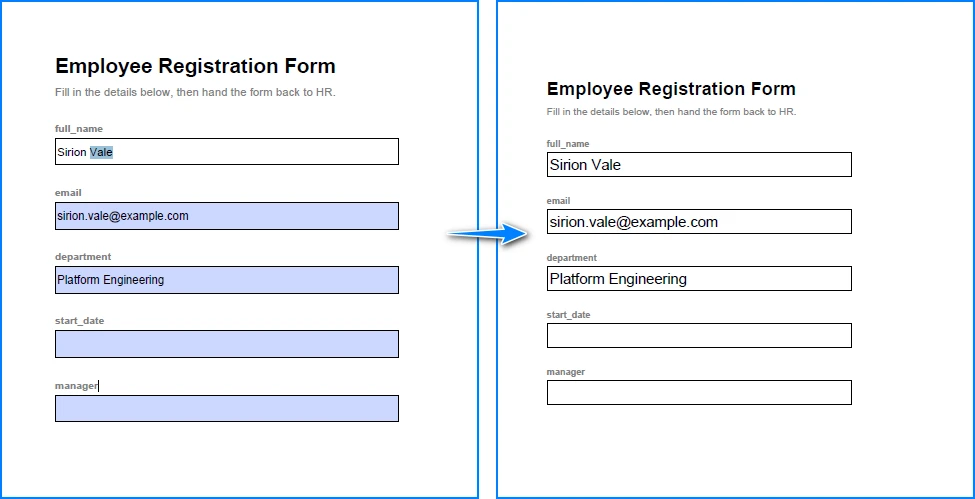
On the registration form used here — five fields, three of them filled — the field count drops from 5 to 0. The values stay on the page as selectable text.
Flatten Selected PDF Form Fields
Locking only the fields that are already final is the more common requirement: a completed section becomes read-only while the rest of the form stays fillable. Fields are reached through the FieldsWidget collection of a PdfFormWidget, and Flatten is a boolean property on each one:
using Spire.Pdf;
using Spire.Pdf.Fields;
using Spire.Pdf.Widget;

PdfDocument pdf = new PdfDocument();
pdf.LoadFromFile("FillableForm.pdf");

PdfFormWidget formWidget = pdf.Form as PdfFormWidget;

foreach (PdfField field in formWidget.FieldsWidget)
{
    // Flatten the fields that are final, leave the rest fillable.
    if (field.Name == "full_name" || field.Name == "email" || field.Name == "department")
    {
        field.Flatten = true;
    }
}

pdf.SaveToFile("PartiallyFlattenedForm.pdf");
pdf.Close();
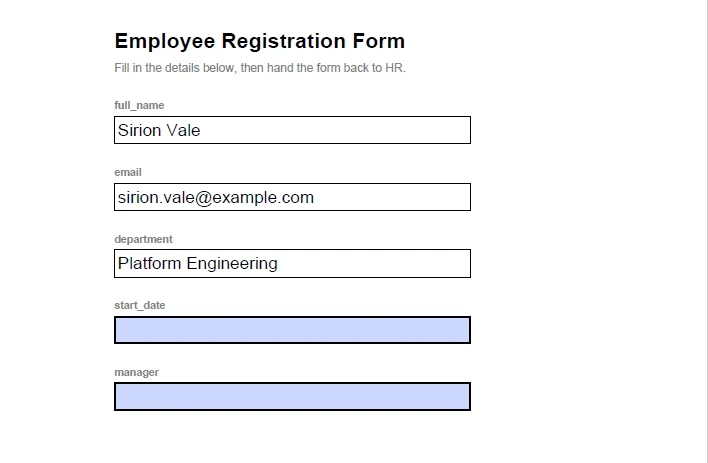
On the sample form this flattens three fields and leaves start_date and manager editable — the count goes from 5 to 2. Filter on the field names your form defines — read them from FieldsWidget so the comparison matches exactly.
Flattening a field vs. removing a field. Flattening keeps a field's visible appearance — including the value typed into it — and removes only the interactivity. Deleting a form field removes the object and its appearance together. If deletion is the actual goal, see Remove/Delete Form Fields from PDF in C# instead.
Flatten PDF Annotations and Comments
Annotations are the objects reviewers leave on top of a page: text comments, highlights, stamps and free text boxes. In Spire.PDF for .NET they are flattened through the interactive annotation model: create a PdfAnnotationCollection for each page and call Flatten() on each annotation.
using Spire.Pdf;
using Spire.Pdf.Interactive.Annotations;

PdfDocument pdf = new PdfDocument();
pdf.LoadFromFile("ReviewedDocument.pdf");

foreach (PdfPageBase page in pdf.Pages)
{
    if (page.Annotations.Count == 0) continue;

    PdfAnnotationCollection annotations = PdfAnnotationCollection.Create(page);

    // Flatten() removes the annotation from the collection, so walk it backwards.
    for (int i = annotations.Count - 1; i >= 0; i--)
    {
        annotations[i].Flatten();
    }
}

pdf.SaveToFile("FlattenedAnnotations.pdf");
pdf.Close();
The reviewed contract page in this guide carries three annotations — a free text note, a rubber stamp and a yellow highlight over a clause. After the loop the annotation count goes from 3 to 0, and all three marks are still drawn on the page: the note keeps its box and colour, the stamp keeps its border, the highlight stays behind the text. Only the interactive objects are gone. The highlight survives because its quad points are read from the saved page rather than from a page still in memory.
Two details in that loop are worth noting. Walk the collection backwards: Flatten() removes each annotation as it is flattened, so a back-to-front loop processes every item exactly once. Flatten() is declared on Spire.Pdf.Interactive.Annotations.PdfAnnotation, the model the annotation collection is created from.
Flatten PDF Layers Through SVG
Optional-content layers are removed by rebuilding each page from its currently visible content: convert each page to SVG and build the PDF back from it. The round trip redraws every page, which drops the layer structure while keeping text as text and graphics as vectors — so the result still selects, searches and scales, unlike a page rendered to an image.
A document with layers converts one page at a time:
using System;
using System.IO;
using System.Linq;
using System.Text.RegularExpressions;
using Spire.Pdf;

// Work in a fresh temp folder for each run.
string workDir = Path.Combine(Path.GetTempPath(),
    "flatten_svg_" + Guid.NewGuid().ToString("N").Substring(0, 8));
Directory.CreateDirectory(workDir);

try
{
    // Step 1 - save every page as its own SVG file. A multi-page document gives
    // page_1.svg, page_2.svg, ...; a single-page document gives page.svg.
    PdfDocument source = new PdfDocument();
    source.LoadFromFile("LayeredDocument.pdf");
    int pageCount = source.Pages.Count;
    source.SaveToFile(Path.Combine(workDir, "page.svg"), FileFormat.SVG);
    source.Close();

    // Sort the files by page number; a single-page document produces page.svg.
    string[] svgFiles = Directory.GetFiles(workDir, "*.svg")
        .OrderBy(f =>
        {
            Match m = Regex.Match(Path.GetFileNameWithoutExtension(f), @"\d+$");
            return m.Success ? int.Parse(m.Value) : 0;
        })
        .ToArray();

    // One SVG per page — the merge below uses that count.
    if (svgFiles.Length != pageCount)
    {
        throw new IOException(
            $"SVG conversion produced {svgFiles.Length} files for {pageCount} pages.");
    }

    // Step 2 - load each SVG back and save it as a one-page PDF.
    string[] pageFiles = new string[svgFiles.Length];
    for (int i = 0; i < svgFiles.Length; i++)
    {
        PdfDocument page = new PdfDocument();
        page.LoadFromSvg(svgFiles[i]);
        pageFiles[i] = Path.Combine(workDir, "page_" + (i + 1) + ".pdf");
        page.SaveToFile(pageFiles[i], FileFormat.PDF);
        page.Close();
    }

    // Step 3 - join the one-page PDFs into a single document, in page order.
    PdfDocument.MergeFiles(pageFiles, "FlattenedLayers.pdf");
}
finally
{
    Directory.Delete(workDir, true);
}
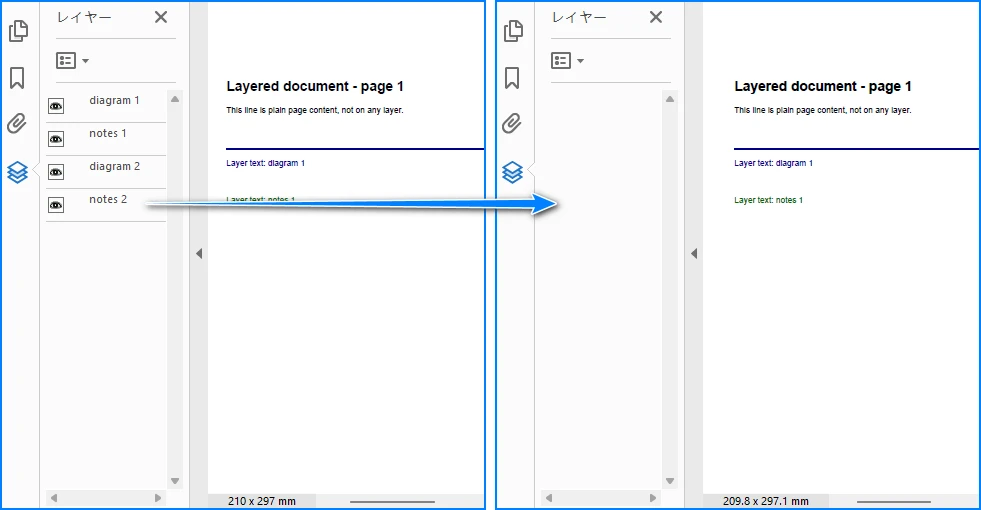
The file names depend on the page count. A two-page layered document saved to page.svg produces page_1.svg and page_2.svg, while a one-page document produces a single page.svg with no number. On the sample document the round trip keeps both pages in order at the original page size, keeps the text that was drawn on each layer, and the layer count goes from 4 to 0. The same workflow on a single-page document returns one page.
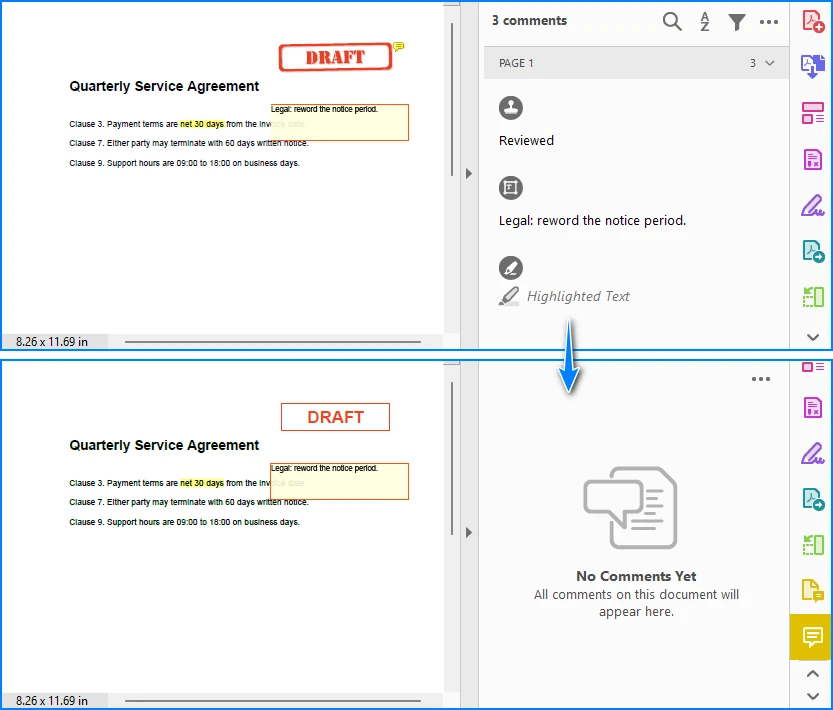
Text and vector graphics survive the round trip, so the rebuilt pages still select, search and scale like the original, and the content that was drawn on each layer stays on the page.
For the two conversion steps on their own, see Convert PDF to SVG in C#, VB.NET and Convert SVG to PDF in C#, VB.NET.
Flatten a PDF Before Printing
Flatten a PDF for printing when the file is going to a printer, a print shop or a viewer you do not control. Once the fields, annotations and layers are ordinary page content, what gets printed is decided by the file rather than by the reader's interactive features.
No separate code is needed. Use the form calls from the form sections when the document has fields, the annotation loop when it has comments, and the SVG workflow when layer visibility could change what lands on paper — then run the output through the checks below before you send it.
Verify the Flattened PDF
A flattened file looks like the original, so confirm the result by counting objects in the saved file rather than by looking at a render:
using Spire.Pdf;
using Spire.Pdf.Fields;
using Spire.Pdf.Widget;

PdfDocument result = new PdfDocument();
result.LoadFromFile("FlattenedForm.pdf");

int fields = 0;
PdfFormWidget form = result.Form as PdfFormWidget;
if (form != null)
{
    foreach (PdfField field in form.FieldsWidget) fields++;
}

int annotations = 0;
foreach (PdfPageBase page in result.Pages)
{
    annotations += page.Annotations.Count;
}

Console.WriteLine($"pages={result.Pages.Count} fields={fields} "
                + $"annotations={annotations} layers={result.Layers.Count}");
result.Close();
Count fields through PdfFormWidget.FieldsWidget. On the sample files this reports:
| File | Pages | Fields | Annotations | Layers |
|---|---|---|---|---|
FillableForm.pdf (input) |
1 | 5 | 0 | 0 |
FlattenedForm.pdf |
1 | 0 | 0 | 0 |
PartiallyFlattenedForm.pdf |
1 | 2 | 0 | 0 |
ReviewedDocument.pdf (input) |
1 | 0 | 3 | 0 |
FlattenedAnnotations.pdf |
1 | 0 | 0 | 0 |
LayeredDocument.pdf (input) |
2 | 0 | 0 | 4 |
FlattenedLayers.pdf |
2 | 0 | 0 | 0 |
Then check the visual result: open the file in a reader and confirm nothing can be clicked or toggled, compare page count and page size with the original, and select or extract text to confirm it is still real text.
Putting It Together
The snippets above solve one concern each. Here they are as a single method that flattens the form fields and the annotations of any document in one pass:
using Spire.Pdf;
using Spire.Pdf.Interactive.Annotations;

/// <summary>
/// Flatten the form fields and annotations of a PDF in one pass.
/// </summary>
public static void FlattenDocument(string inputFile, string outputFile)
{
    PdfDocument pdf = new PdfDocument();
    pdf.LoadFromFile(inputFile);

    // 1. Form fields: one flag covers every field in the document.
    if (pdf.Form != null)
    {
        pdf.Form.IsFlatten = true;
    }

    // 2. Annotations: Flatten() removes each one, so walk backwards. Skip pages
    //    that carry no annotations.
    foreach (PdfPageBase page in pdf.Pages)
    {
        if (page.Annotations.Count == 0) continue;

        PdfAnnotationCollection annotations = PdfAnnotationCollection.Create(page);
        for (int i = annotations.Count - 1; i >= 0; i--)
        {
            annotations[i].Flatten();
        }
    }

    pdf.SaveToFile(outputFile);
    pdf.Close();
}
The guard keeps the loop on pages that carry annotations, so the same method also works for documents that only have form fields. With it, the method takes the five-field form to 0 fields and the reviewed contract from 3 annotations to 0. Layered documents go through the SVG workflow from the previous section instead.
FAQ
What is the difference between flattening and removing form fields?
Flattening keeps the field's visible appearance, including any entered value, and removes only the interactivity. Removing a form field deletes the field object and its appearance together.
Can I flatten only some form fields?
Yes. Cast pdf.Form to PdfFormWidget, walk FieldsWidget, and set Flatten = true on the fields you name. The rest stay fillable.
Does flattening keep the text selectable and searchable?
Yes. A flattened text field keeps its value in the page's text layer, and the SVG round trip keeps the text it redraws, so the values stay selectable, copyable and searchable.
Is flattening reversible?
Flattening writes the fields and annotations into the page, so keep the source PDF if you may need to edit them later.
Do I need to flatten before printing?
Not always, but it removes the dependency on the reader. Flattening can make the output more consistent across PDF viewers, because the visible content no longer depends on interactive fields, annotations or layer visibility settings.
Conclusion
Flattening a PDF in C# is one call per object type:
pdf.Form.IsFlatten = trueflattens every field in the document;PdfField.Flattenflattens the ones you name.PdfAnnotationCollection.Create(page)plusFlatten()on each item, walked backwards, flattens every comment, highlight and stamp on the page.- Layers are flattened by saving each page as SVG, loading it back and merging the pages with
PdfDocument.MergeFiles.
The page keeps its appearance either way, so verify by counting the objects left in the saved file — not by comparing screenshots.
If you need to test Spire.PDF for .NET in a real business environment, you can apply for a temporary license.
Add Hyperlinks to Pictures in Excel with JavaScript in React
2026-10-10 09:24:23 Written by liu taliaA picture in Excel is more than decoration. Put a logo or a product shot on a worksheet and give it a hyperlink, and the file stops being a plain description and becomes something a reader can click through. A picture is not a cell, though, and its hyperlink lives on the picture object, so both setting and reading one go through the worksheet's picture collection rather than its cell hyperlink collection. Spire.XLS for JavaScript does this in the browser on WebAssembly, handling input and output files through a virtual file system (VFS) with no backend service.
This article covers two core feature points:
For installation and project setup, see Integrating Spire.XLS for JavaScript in a React Project. The examples below assume Spire.XLS is installed and the WebAssembly module has been initialised.
Set a hyperlink on a picture
Setting a hyperlink on a picture is what turns it into a clickable entry point: a reader who clicks the picture on the worksheet opens the address it points at. The link belongs to the picture itself rather than to a cell, so the picture object has to be taken from the worksheet's picture collection first, and the address handed to that object. The steps are:
- Load the font, the picture and the test data file into the VFS.
- Load the workbook with
workbook.LoadFromFile. - Insert the picture into the space left for it with
sheet.Pictures.Add. - Set the hyperlink on the picture with
picture.SetHyperLink, passingtrueas the second argument. - Save the workbook with
workbook.SaveToFile. - Dispose of the workbook with
workbook.Disposeto free resources.
The complete code example below shows how to set a hyperlink on a picture in Excel in React:
function App() {
  const pictureHyperlink = async () => {
    // get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // check that the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // load the font, the picture and the test data file into the VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    await window.spire.FetchFileToVFS('logo.png', '', `${process.env.PUBLIC_URL}data/`);
    const inputFileName = 'PictureLink.xlsx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}data/`);

    // load the workbook
    const workbook = new xlsModule.Workbook();
    workbook.LoadFromFile({ fileName: inputFileName });

    // take the first worksheet and drop the picture into the space left for it
    const sheet = workbook.Worksheets.get(0);
    const picture = sheet.Pictures.Add({ topRow: 10, leftColumn: 1, fileName: 'logo.png' });

    // set the hyperlink on the picture; the second argument being true means it points outside the workbook
    picture.SetHyperLink('https://www.e-iceblue.com/Misc/about-us.html', true);

    // save the workbook
    const outputFileName = 'PictureHyperlink.xlsx';
    workbook.SaveToFile({ fileName: outputFileName, fileFormat: xlsModule.FileFormat.Version2010 });

    // dispose of the workbook to free resources
    workbook.Dispose();

    // read the result file from the VFS and start the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.spreadsheetml.sheet' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add Hyperlinks to Pictures in Excel</h1>
      <button id="picture-hyperlink" onClick={pictureHyperlink}>Set a hyperlink on the picture</button>
    </div>
  );
}

export default App;
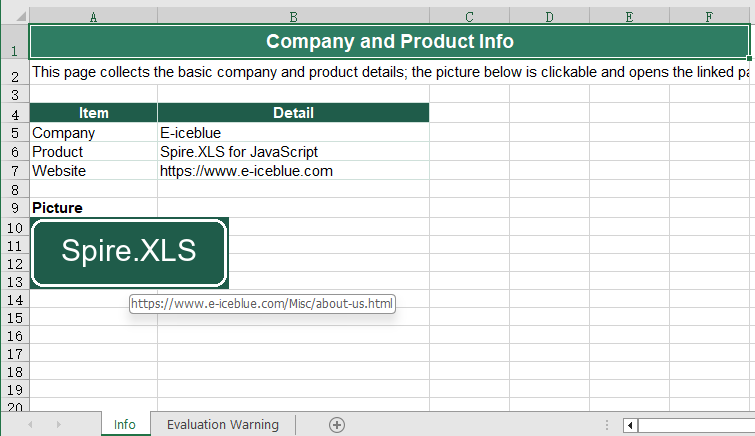
After running, the effect of setting a hyperlink on a picture:
Read the hyperlink from a picture
Reading the hyperlink off a picture is how a finished workbook is checked over: whether the links are all there, and whether they point at the right addresses. The addresses that come back are written out as a text file, which makes them easy to line up against a list of links. Picture hyperlinks are not kept in the cell hyperlink collection, so the pictures have to be taken from the worksheet one by one, and each one asked for its own link object. The steps are:
- Load the font and the test data file into the VFS.
- Load the workbook with
workbook.LoadFromFile. - Take the picture count from
sheet.Pictures.Countand walk every picture on the worksheet with it. - Take this picture's hyperlink object with
picture.GetHyperLink. - Read the target address from the link object's
Address, collecting the addresses as you go. - Write the collected addresses into a text file with
FS.writeFile, one address per line. - Dispose of the workbook with
workbook.Disposeto free resources.
The complete code example below shows how to read the hyperlink from a picture in Excel in React:
function App() {
  const readPictureHyperlink = async () => {
    // get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // check that the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // load the font and the test data file into the VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'PictureHyperlinks.xlsx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}data/`);

    // load the workbook
    const workbook = new xlsModule.Workbook();
    workbook.LoadFromFile({ fileName: inputFileName });

    // walk the pictures of the worksheet and read the hyperlink off each one
    const sheet = workbook.Worksheets.get(0);
    const pictures = sheet.Pictures;
    const addresses = [];
    for (let i = 0; i < pictures.Count; i++) {
      const link = pictures.get(i).GetHyperLink();
      addresses.push(link.Address);
    }

    // write the addresses that were read into a text file
    const outputFileName = 'ReadPictureHyperlink.txt';
    window.dotnetRuntime.Module.FS.writeFile(outputFileName, addresses.join('\n'));

    // dispose of the workbook to free resources
    workbook.Dispose();

    // read the result file from the VFS and start the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/plain' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add Hyperlinks to Pictures in Excel</h1>
      <button id="read-picture-hyperlink" onClick={readPictureHyperlink}>Read the hyperlink from the picture</button>
    </div>
  );
}

export default App;
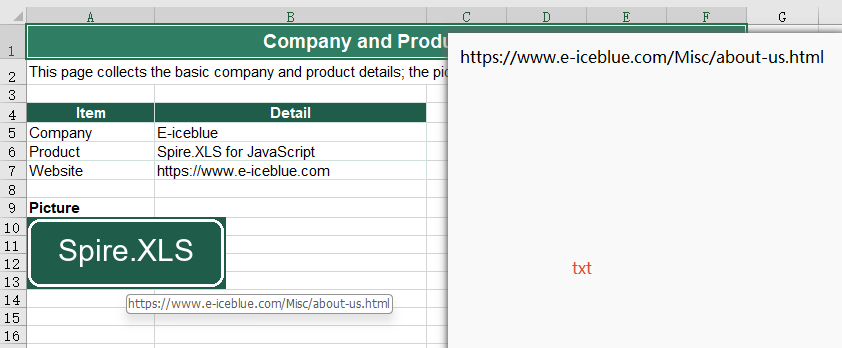
After running, the effect of reading the hyperlink from a picture:
FAQ
Why does a picture's hyperlink not show up in sheet.HyperLinks?
Cause: sheet.HyperLinks collects cell hyperlinks only. A picture is not a cell; it belongs to the worksheet's picture collection, and the link hangs on the picture object itself.
Solution: Go through the picture collection. In this example, after a hyperlink was set on the picture, sheet.HyperLinks.Count was still 0, and it was still 0 after the file was saved and opened again. Read a picture's link with sheet.Pictures.get(i).GetHyperLink(), then read the Address off the link object.
When should the second argument of SetHyperLink be false?
Cause: The second argument of picture.SetHyperLink(address, isExternal) says whether the target lies outside the workbook.
Solution: Pass true for a web page or an external file, and the link type comes out as HyperLinkType.Url; pass false for a position inside the same workbook, write the address as a cell reference such as Sheet1!A1, and the type comes out as HyperLinkType.Workbook. In this example both forms were saved, and after the file was opened again the Address and Type read back matched what had been set.
Get a Free License
Spire.XLS for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Delete Annotations from a PDF Document in React with JavaScript
2026-10-10 09:00:05 Written by Nina TangA PDF moving through a workflow carries markup from the previous review round: a highlighted point, a change request, a sticky note that says "to confirm". Passing those traces on as-is invites misreading, and can leak internal discussion along with them. Deleting them one by one in a reader does not scale once there are many documents.
This article uses Spire.PDF for JavaScript to delete annotations from a PDF document. It loads, modifies, and saves PDF documents in the browser with WebAssembly; everything runs locally, files are read and written through a virtual file system (VFS), and no backend is involved. Deletion works on the PdfPage.Annotations collection: remove one entry by index, or clear a whole page in a single call.
This article covers two core features:
For installation and project setup, see How to Integrate Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Delete a Specific Annotation
Spire.PDF for JavaScript exposes the PdfPage.Annotations collection for managing a page's annotations. RemoveAt() removes one entry by index, starting at 0. the collection is ordered, so once an entry is removed the indices of the annotations after it shift down by one.
function App() {
  const deleteSpecificAnnotation = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF with annotations into the VFS
    const inputFileName = 'DocumentWithAnnotations.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Delete the annotation at index 0 on page 1
    doc.Pages.get_Item(0).Annotations.RemoveAt(0);

    const outputFileName = 'DeleteSpecificAnnotation.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Delete a Specific Annotation</h1>
      <button onClick={deleteSpecificAnnotation} id="btn-1">
        Delete
      </button>
    </div>
  );
}

export default App;
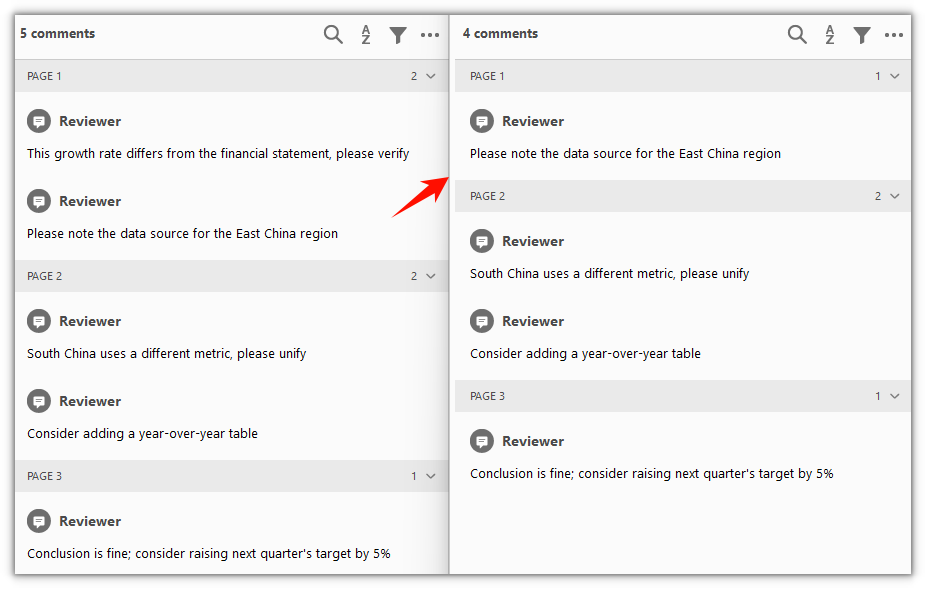
The annotation at index 0 on page 1 is removed and the remaining annotations are unchanged
Delete All Annotations from the Document
Spire.PDF for JavaScript also provides the PdfAnnotationCollection.Clear() method, which wipes every annotation on a page at once. It does not distinguish by type or count — the whole page is cleared together. To clear an entire document, walk doc.Pages and call it once per page.
function App() {
  const deleteAllAnnotations = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF with annotations into the VFS
    const inputFileName = 'DocumentWithAnnotations.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Walk every page and clear all its annotations
    for (let i = 0; i < doc.Pages.Count; i++) {
      doc.Pages.get_Item(i).Annotations.Clear();
    }

    const outputFileName = 'DeleteAllAnnotations.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Delete All Annotations from the Document</h1>
      <button onClick={deleteAllAnnotations} id="btn-2">
        Clear
      </button>
    </div>
  );
}

export default App;
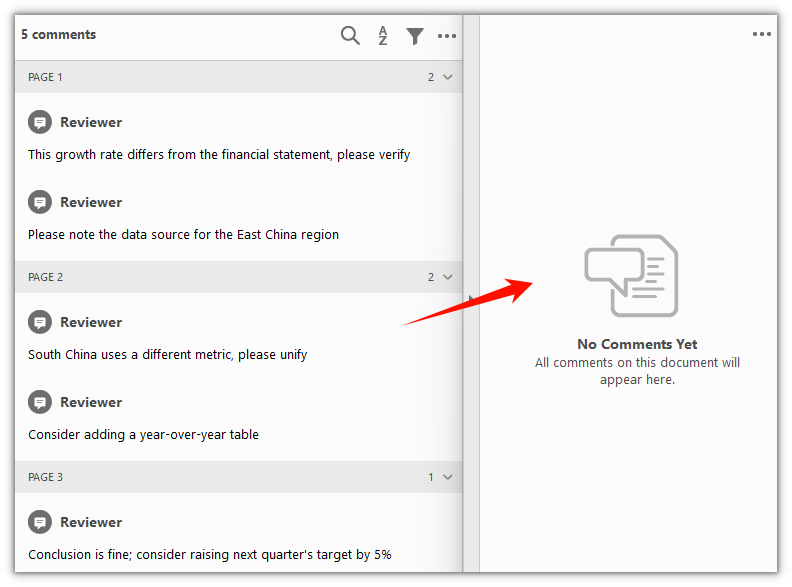
Annotations are cleared from every page and the body content is left untouched
FAQ
The wrong annotation got deleted
Cause: RemoveAt(index) locates an entry by index, and a text annotation or free-text annotation often generates a popup child annotation automatically. Both count in the Annotations collection, so the actual index does not line up with the number of notes you see on the page.
Solution: Walk the collection first, check each entry's index and type, then decide which one to remove. To remove only the text annotation itself, skip the popup child:
const annotations = doc.Pages.get_Item(0).Annotations;
for (let i = 0; i < annotations.Count; i++) {
  // A popup annotation is a child derived from a text annotation; skip it
  if (annotations.get_Item(i) instanceof pdfModule.PdfPopupAnnotationWidget) continue;
  annotations.RemoveAt(i);
  break;
}
Forward loop deletion skips half the annotations
Cause: After RemoveAt() removes one entry, the indices of every annotation after it drop by one. Deleting with a forward loop for (let i = 0; i < annotations.Count; i++) skips the entry right after each removed one.
Solution: Delete in reverse order, or just call Clear() on the page:
// Delete in reverse to avoid skipping entries as indices shift down
const annotations = doc.Pages.get_Item(0).Annotations;
for (let i = annotations.Count - 1; i >= 0; i--) {
  annotations.RemoveAt(i);
}
Does Clear() wipe the body content too
Cause: Clear() operates on the current page's Annotations collection, and that collection holds annotation objects only — no body text, images, or form fields.
Solution: Clear() removes annotations only and leaves the page body as it is. To clear just some pages, call it per page instead of walking the whole document:
// Clear annotations on page 2 (index 1) only
doc.Pages.get_Item(1).Annotations.Clear();
Get a Free License
If you want to remove the evaluation message from the resulting documents, or to get rid of the functional limitations, please contact sales for a temporary license valid for 30 days.
