Get and Replace PDF Fonts in React with JavaScript
The same PDF can look different when opened on different machines: if the font a document references is not installed locally, the viewer substitutes another one. Conversely, when brand standards or legal requirements say an outgoing file may only use specified fonts, you first need to know which fonts the original uses. Common browser-side PDF libraries mostly draw pages; they do not expose font resources.
This article uses Spire.PDF for JavaScript to read and replace the fonts in a PDF: first list the document's fonts with PdfDocument.UsedFonts, then replace the standard and non-embedded TrueType fonts with a new TrueType font via PdfUsedFont.Replace(). Everything runs in the browser; files are read and written through a virtual file system (VFS) and never uploaded to a server.
This article covers two core features:
For installation and project configuration, see Integrate Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Get the Fonts Used in a PDF
Spire.PDF for JavaScript provides the PdfDocument.UsedFonts property for reading every font used in a document. Each item in the collection is a PdfUsedFont, whose Name, Size, Style, and Type give the font name, size, style, and font type.
The steps are:
- Get the Spire.PDF WASM module and confirm it is ready.
- Load the sample PDF into the VFS, create a
PdfDocumentobject, and load the file. - Read
PdfDocument.UsedFontsand take eachPdfUsedFontfrom the collection. - Put together each font's name, size, style, and type, and write them to a text file.
- Read the result file from the VFS and trigger a browser download.
The code for getting the fonts in a PDF is as follows:
function App() {
  const getFonts = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the sample PDF into the VFS
    const inputFileName = 'Font_Sample.pdf';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the document
    const doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // UsedFonts lists the fonts the document currently uses
    const fonts = doc.UsedFonts;

    const styleNames = new Map([
      [pdfModule.PdfFontStyle.Regular.value, 'Regular'],
      [pdfModule.PdfFontStyle.Bold.value, 'Bold'],
      [pdfModule.PdfFontStyle.Italic.value, 'Italic'],
      [pdfModule.PdfFontStyle.Underline.value, 'Underline'],
      [pdfModule.PdfFontStyle.Strikeout.value, 'Strikeout'],
    ]);
    const typeNames = new Map([
      [pdfModule.PdfFontType.Standard.value, 'Standard'],
      [pdfModule.PdfFontType.TrueType.value, 'TrueType'],
      [pdfModule.PdfFontType.TrueTypeEmbedded.value, 'Embedded TrueType'],
    ]);

    // Collect each font's name, size, style, and type
    let report = `Document: ${inputFileName}\r\nFont count: ${fonts.length}\r\n\r\n`;
    for (let i = 0; i < fonts.length; i++) {
      const font = fonts.get(i);
      report += `${i + 1}. ${font.Name}\r\n`;
      report += `   Size: ${font.Size}\r\n`;
      report += `   Style: ${styleNames.get(font.Style.value)}\r\n`;
      report += `   Type: ${typeNames.get(font.Type.value)}\r\n\r\n`;
    }

    // Write the font list into the VFS
    const outputFileName = 'FontList.txt';
    window.dotnetRuntime.Module.FS.writeFile(outputFileName, report);
    doc.Close();

    // Read the result file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/plain;charset=utf-8' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Get the Fonts Used in a PDF</h1>
      <button onClick={getFonts}>
        Get fonts
      </button>
    </div>
  );
}

export default App;
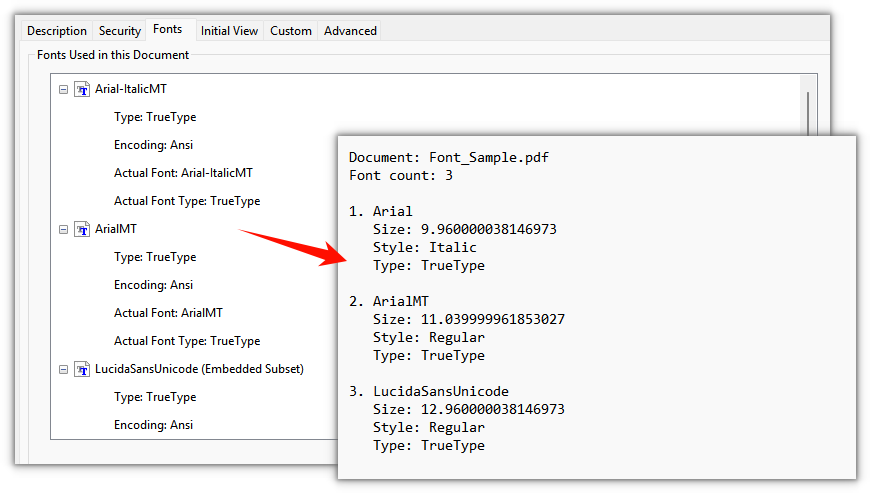
The font list is written to a text file, listing each font's name, size, style, and type:
Replace the Fonts Used in a PDF
Spire.PDF for JavaScript also provides the PdfUsedFont.Replace() method, which swaps one font in a document for another font object. It works only with standard Type1 fonts and non-embedded TrueType fonts; embedded fonts (such as subset-embedded CJK fonts) cannot be replaced and must be skipped.
The steps are:
- Get the Spire.PDF WASM module and confirm it is ready.
- Load the sample PDF and the replacement font file into the VFS, with the font file placed under
/Library/Fonts/. - Create a
PdfDocumentobject, load the PDF, and readPdfDocument.UsedFonts. - Create a
PdfTrueTypeFontobject, iterate overUsedFonts, skip embedded fonts, and callPdfUsedFont.Replace()on standard and non-embedded TrueType fonts. - Save the result with
PdfDocument.SaveToFile()and trigger a browser download.
The code for replacing the fonts in a PDF is as follows:
function App() {
  const replaceFonts = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the replacement font and the sample PDF
    await window.spire.FetchFileToVFS('ARIALUNI.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'Font_Sample.pdf';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the document
    const doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // UsedFonts returns the fonts used in the document
    const fonts = doc.UsedFonts;
    const newFont = new pdfModule.PdfTrueTypeFont({
      fontFamily: 'Arial Unicode MS',
      size: 12,
      style: pdfModule.PdfFontStyle.Regular,
      unicode: true
    });

    // Replace one by one: Replace() supports only standard Type1 and non-embedded TrueType fonts
    for (let i = 0; i < fonts.length; i++) {
      const font = fonts.get(i);
      // Embedded fonts cannot be replaced; skip them
      if (font.Type.value === pdfModule.PdfFontType.TrueTypeEmbedded.value) {
        continue;
      }
      font.Replace(newFont);
    }

    // Save the result file
    const outputFileName = 'ReplacedFonts.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Replace the Fonts Used in a PDF</h1>
      <button onClick={replaceFonts}>
        Replace fonts
      </button>
    </div>
  );
}

export default App;
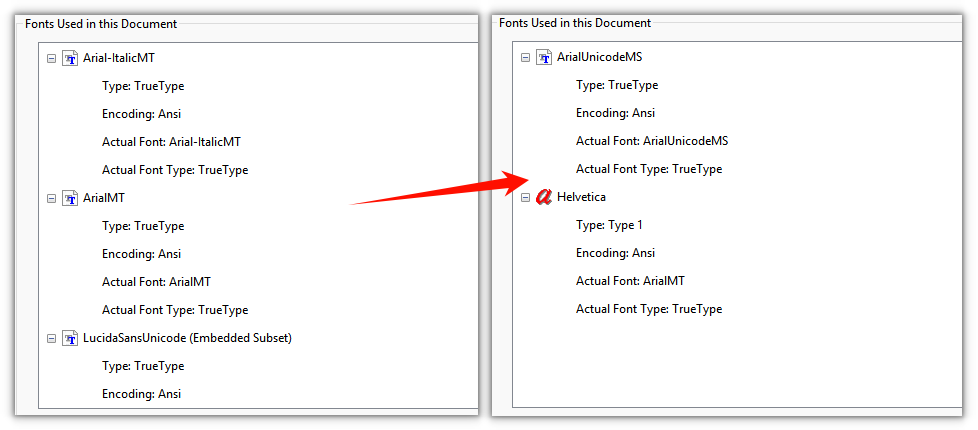
After replacement, the text in the standard font uses the new TrueType font while embedded fonts stay unchanged:
FAQ
Why do the text size and style change after replacement
Reason: Replace() takes a complete font object, and replacement applies the new object's own size and style; the original sizes of individual text runs are not preserved.
Solution: Set the target font's size and style to the values you want in the result. For example, to make everything 12 pt regular, pass size: 12 and style: PdfFontStyle.Regular to PdfTrueTypeFont.
Why do Chinese or Japanese characters turn into boxes or question marks after replacement
Reason: The target font has no glyphs for those characters, or PdfTrueTypeFont was created without Unicode enabled.
Solution: Use a font that covers the target language (such as Arial Unicode MS) and pass unicode: true when creating it. The font file must first be loaded into /Library/Fonts/ in the VFS so Spire.PDF can embed it.
Can I replace only one of the fonts
Reason: UsedFonts lists each font in the document, and Replace() acts on a single PdfUsedFont.
Solution: Check Name while iterating and replace only the matching font:
for (let i = 0; i < fonts.length; i++) {
  const font = fonts.get(i);
  if (font.Name === 'ArialMT') {
    font.Replace(newFont);
  }
}
Font names of subset-embedded fonts may carry prefixes such as BCDEEE+, so write the comparison against the Name you actually read from the list.
Why does Replace() report that the font is not a standard Type 1 or non-embedded TrueType font
Reason: PdfUsedFont.Replace() only works on standard Type1 fonts and non-embedded TrueType fonts. CJK fonts in PDFs are often subset-embedded TrueType fonts (UsedFonts reports them as Embedded TrueType), and Spire.PDF cannot replace them directly.
Solution: Check Type while iterating UsedFonts and call Replace() only on standard and non-embedded TrueType fonts; skip the rest, or prepare a document that uses standard or non-embedded fonts first.
Get a Free License
To remove the evaluation message from result documents or lift the feature limits, contact sales for a 30-day temporary license.
Create PDF Booklets in React with JavaScript
When a product manual or conference handout is printed as a booklet, the pages of a multi-page document have to be rearranged onto facing sheets in saddle-stitch order. In desktop software that means dragging pages by hand, which goes wrong easily once the page count grows, and every new document starts over. Hand it to a server, and the file has to leave the user's device first.
This article uses Spire.PDF for JavaScript to create PDF booklets. It loads, imposes, and saves PDFs in the browser via WebAssembly, reading and writing every file through a virtual file system (VFS) with no backend involved.
This article covers two core features:
For installation and project configuration, see Integrate Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Impose a PDF as a Two-Sided Booklet Automatically
Spire.PDF for JavaScript provides the PdfDocument.CreateBooklet() method, which imposes the pages of an existing PDF onto facing pages in saddle-stitch order. The width and height parameters set the sheet size of the finished product; when bothSides is true, the layout is arranged for double-sided printing.
The steps are:
- Get the Spire.PDF WASM module and confirm it is ready.
- Load the source PDF into the VFS.
- Create a
PdfDocumentobject and callCreateBooklet()with a width equal to two A4 pages side by side and the height of one A4 page. - Save the result with
SaveToFile(). - Read the result file from the VFS and trigger a browser download.
The code for creating a booklet by automatic imposition is as follows:
function App() {
  const createBooklet = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the source PDF into the VFS
    const inputFileName = 'CMS-Technical-Manual.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Spread size: width is two A4 pages side by side, height is one A4 page
    const width = pdfModule.PdfPageSize.A4().Width * 2;
    const height = pdfModule.PdfPageSize.A4().Height;

    // Create a document and impose the pages in saddle-stitch order
    const doc = new pdfModule.PdfDocument();
    doc.CreateBooklet({ fileName: inputFileName, width: width, height: height, bothSides: true });

    // Save the result file
    const outputFileName = 'Booklet_Auto.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Create a Two-Sided Booklet</h1>
      <button onClick={createBooklet}>
        Create Booklet
      </button>
    </div>
  );
}

export default App;
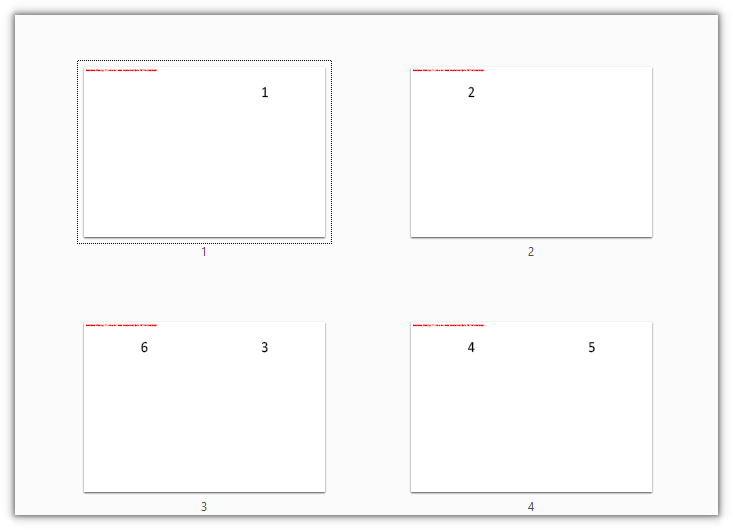
The source pages are imposed onto spreads two at a time in saddle-stitch order:
Build Facing Pages in a Custom Page Order
Spire.PDF for JavaScript also provides the PdfPageBase.CreateTemplate() method, which extracts the content of a page into a template that PdfTemplate.Draw() can draw at a given position on a new page. A page-order array decides which two pages land on each sheet; the example puts consecutive pages side by side in reading order.
The steps are:
- Get the Spire.PDF WASM module and confirm it is ready.
- Load the source PDF into the VFS.
- Create a
PdfDocumentobject and load the source document; then create an output document whose width is two A4 pages side by side and whose height is one A4 page. - For each pair in the page order, take a page template with
CreateTemplate()and draw it onto the left or right half of the spread withDraw(). - Save the result with
SaveToFile(), then read it from the VFS and trigger a download.
The code for building facing pages manually is as follows:
function App() {
  const createCustomBooklet = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the source PDF into the VFS
    const inputFileName = 'CMS-Technical-Manual.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the source document
    const srcDoc = new pdfModule.PdfDocument();
    srcDoc.LoadFromFile(inputFileName);
    const pageCount = srcDoc.Pages.Count;
    const a4 = pdfModule.PdfPageSize.A4();

    // Output document: width is two A4 pages side by side, height is one A4 page
    const bookletDoc = new pdfModule.PdfDocument();
    bookletDoc.PageSettings.Margins.All = 0;
    bookletDoc.PageSettings.Width = a4.Width * 2;
    bookletDoc.PageSettings.Height = a4.Height;

    // Two consecutive pages per sheet: 1|2, 3|4, 5|6, ...
    for (let i = 0; i < pageCount; i += 2) {
      const sheet = bookletDoc.Pages.Add();

      // Left half
      const leftTemplate = srcDoc.Pages.get_Item(i).CreateTemplate();
      leftTemplate.Draw({ page: sheet, location: new pdfModule.PointF(0, 0) });

      // Right half; with an odd page count the last sheet leaves the right side blank
      if (i + 1 < pageCount) {
        const rightTemplate = srcDoc.Pages.get_Item(i + 1).CreateTemplate();
        rightTemplate.Draw({ page: sheet, location: new pdfModule.PointF(a4.Width, 0) });
      }
    }

    // Save the result file
    const outputFileName = 'Booklet_CustomOrder.pdf';
    bookletDoc.SaveToFile(outputFileName);
    bookletDoc.Close();
    srcDoc.Close();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Custom Page Order Imposition</h1>
      <button onClick={createCustomBooklet}>
        Build Facing Pages
      </button>
    </div>
  );
}

export default App;
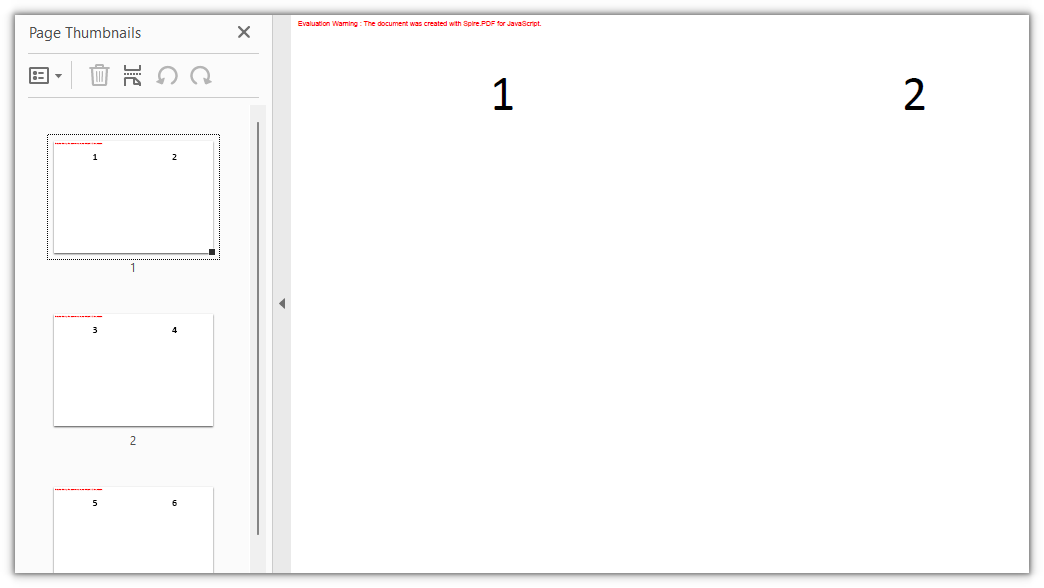
Two consecutive pages sit side by side on one sheet; a 6-page document produces 3 spreads:
FAQ
What determines the paper size of the booklet
Reason: The width and height passed to CreateBooklet() describe the sheet size of the finished spread, not the size of a single page in the source document. This article uses "A4 width × 2" and "A4 height", which gives an A3-sized spread with one A4 page on each half.
Solution: To print on A4 paper, set the sheet to A4 landscape — width equal to the A4 height, height equal to the A4 width; each half then holds an A5 page, and the source pages are scaled down to half a sheet.
// A4 landscape: one A5 page on each half
const width = pdfModule.PdfPageSize.A4().Height;
const height = pdfModule.PdfPageSize.A4().Width;
What does the bothSides parameter do
Reason: bothSides tells CreateBooklet() whether the result will be printed double-sided. true groups pages into front and back pairs in saddle-stitch order and pads the page count to a multiple of 4; false lays pages out for single-sided printing and adds no blank pages.
Solution: Pass true when you print on a duplex printer and fold and staple the result; pass false for single-sided printing only. The print mode must match the imposed layout, or the page order will not line up.
How is the booklet arranged when the page count is not a multiple of 4
Reason: A saddle-stitch sheet holds four pages (two on each side); when the pages run out, the last sheet has blank positions.
Solution: With automatic imposition, CreateBooklet() pads the required spreads. With manual imposition, the loop checks i + 1 < pageCount before drawing the right half, so an unpaired page simply leaves the right side blank.
In manual imposition the content drifts to one side or runs off the sheet
Reason: PdfTemplate.Draw() draws at the template's original size by default. If a source page is wider than half a sheet, the right-hand page crosses the center line or extends past the edge.
Solution: Make the source page size match half the sheet. In this article the source pages are A4 and the spread is two A4 pages wide, so placing them at x = 0 and x = A4.Width aligns exactly. If the source size differs, use PdfCanvas.DrawTemplate() with size set to the half-sheet size; the template is scaled to fit.
sheet.Canvas.DrawTemplate({
  template: rightTemplate,
  location: new pdfModule.PointF(a4.Width, 0),
  size: new pdfModule.SizeF(a4.Width, a4.Height)
});
Get a Free License
If you want to remove the evaluation message from the result document or lift the feature limits, contact sales for a temporary license valid for 30 days.
Set PDF Image Transparency with JavaScript in React
When a contract or report needs a supporting image or a logo, a fully opaque image covers the body text, so it gets pushed into a corner. If an image has already been placed and needs to be faded, the usual fix is to go back to the source file and redo the layout, and without that file you are stuck with what is on the page. Both tasks are manual in desktop software and hard to fit into a batch Web workflow; handled on a server, the file has to leave the user's device first.
This article uses Spire.PDF for JavaScript to do the work in the browser. A new image is drawn at a given alpha with PdfCanvas.SetTransparency(); images already on the page are located with PdfImageHelper, deleted, and redrawn semi-transparent inside their original bounds. The library runs on WebAssembly and reads and writes PDF files through a virtual file system (VFS), so no backend is required.
This article covers two core features:
- Add an image with transparency to a PDF document
- Adjust the transparency of existing images on a PDF page
For installation and project setup, see How to Integrate Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module has been initialized.
Add an Image with Transparency to a PDF Document
Spire.PDF for JavaScript provides the PdfCanvas.SetTransparency() method to set transparency on the canvas. When only alpha is passed, fill and stroke share that value. It ranges from 0 to 1: 0 is fully transparent and 1 is fully opaque. The setting applies to all drawing that follows the call, so wrap it in Save() and Restore() to keep other page content from fading as well.
Follow these steps:
- Get the Spire.PDF WebAssembly module and confirm it is ready.
- Load the PDF file and the image into the VFS.
- Create a
PdfDocumentobject, load the PDF, take the first page, and load the image withPdfImage.FromFile(). - Save the canvas state with
PdfCanvas.Save(), callSetTransparency(), and draw the image withDrawImage(). - Restore the canvas state with
Restore(), save the result withSaveToFile(), and trigger the download.
The code for adding a semi-transparent image:
function App() {
  const addTransparentImage = async () => {
    // Get the Spire.PDF WebAssembly module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF and the image into the VFS
    const inputFileName = 'Business_Data_Overview.pdf';
    const imageFileName = 'scenery.jpg';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS(imageFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Take the first page and load the image to draw
    let page = doc.Pages.get_Item(0);
    let image = pdfModule.PdfImage.FromFile(imageFileName);

    // Save the canvas state so the transparency applies only to this block
    const state = page.Canvas.Save();

    // An alpha of 0.35 makes the image semi-transparent while the content below stays visible
    page.Canvas.SetTransparency({ alpha: 0.35 });
    page.Canvas.DrawImage({ image: image, x: 145, y: 400, width: 300, height: 173 });

    // Restore the canvas state so later drawing is not affected
    page.Canvas.Restore({ state: state });

    // Save the result file
    const outputFileName = 'TransparentImage.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add a Semi-Transparent Image</h1>
      <button onClick={addTransparentImage}>
        Add Image
      </button>
    </div>
  );
}

export default App;
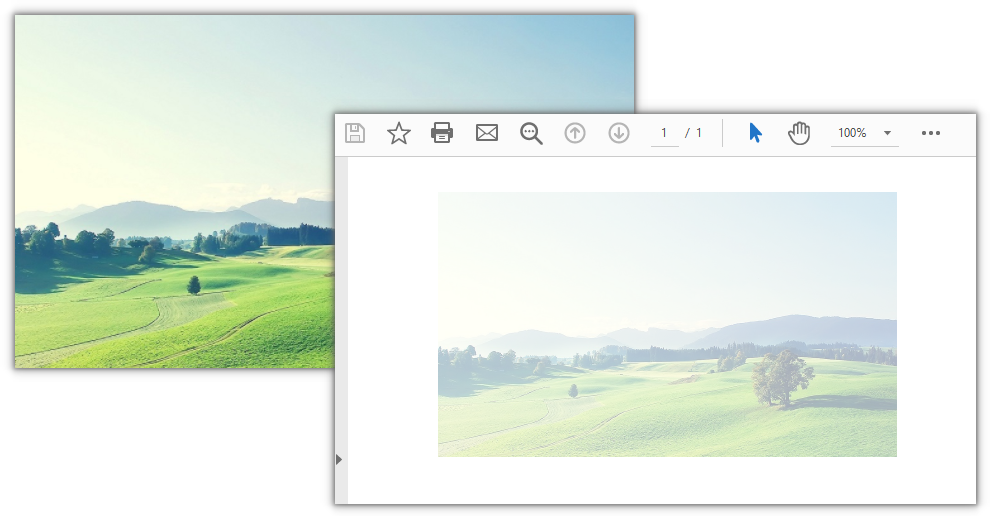
With the image drawn at 35% opacity, the content underneath still shows through:
Adjust the Transparency of Existing Images on a PDF Page
Spire.PDF for JavaScript also provides the PdfImageHelper class to read, delete, and replace images on a page. GetImagesInfo() returns the bounds and image stream of each image. Recreate a PdfImage from each stream, delete the original with DeleteImage(), and redraw it at the specified transparency inside its Bounds.
Follow these steps:
- Get the Spire.PDF WebAssembly module and confirm it is ready.
- Load the PDF file into the VFS.
- Create a
PdfDocumentobject, load the PDF, get the page, and read all images on it withPdfImageHelper.GetImagesInfo(). - Recreate each image from
PdfImageInfo.ImagewithPdfImage.FromStream()and record itsBounds. - Delete all original images with
DeleteImage(), redraw them at the specified transparency inside their original bounds, then save withSaveToFile()and trigger the download.
The code for adjusting the transparency of existing images:
function App() {
  const adjustImageTransparency = async () => {
    // Get the Spire.PDF WebAssembly module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF into the VFS
    const inputFileName = 'Business_Data_Overview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Take the first page and read the image information on it
    let page = doc.Pages.get_Item(0);
    let helper = new pdfModule.PdfImageHelper();
    let images = helper.GetImagesInfo(page);

    // Collect each image stream and bounds first, for redrawing after deletion
    let items = [];
    for (let i = 0; i < images.length; i++) {
      items.push({
        info: images[i],
        image: pdfModule.PdfImage.FromStream(images[i].Image),
        bounds: images[i].Bounds
      });
    }

    // Delete all original images first, then redraw them together; redrawing right after each delete gets overwritten by the next delete
    for (let i = 0; i < items.length; i++) {
      helper.DeleteImage({ imageInfo: items[i].info });
    }

    // Redraw each image at 40% opacity inside its original bounds
    for (let i = 0; i < items.length; i++) {
      const { image, bounds } = items[i];
      const state = page.Canvas.Save();
      page.Canvas.SetTransparency({ alpha: 0.4 });
      page.Canvas.DrawImage({
        image: image,
        x: bounds.X,
        y: bounds.Y,
        width: bounds.Width,
        height: bounds.Height
      });
      page.Canvas.Restore({ state: state });
    }

    // Save the result file
    const outputFileName = 'ExistingImageTransparency.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Adjust Existing Image Transparency</h1>
      <button onClick={adjustImageTransparency}>
        Adjust Transparency
      </button>
    </div>
  );
}

export default App;
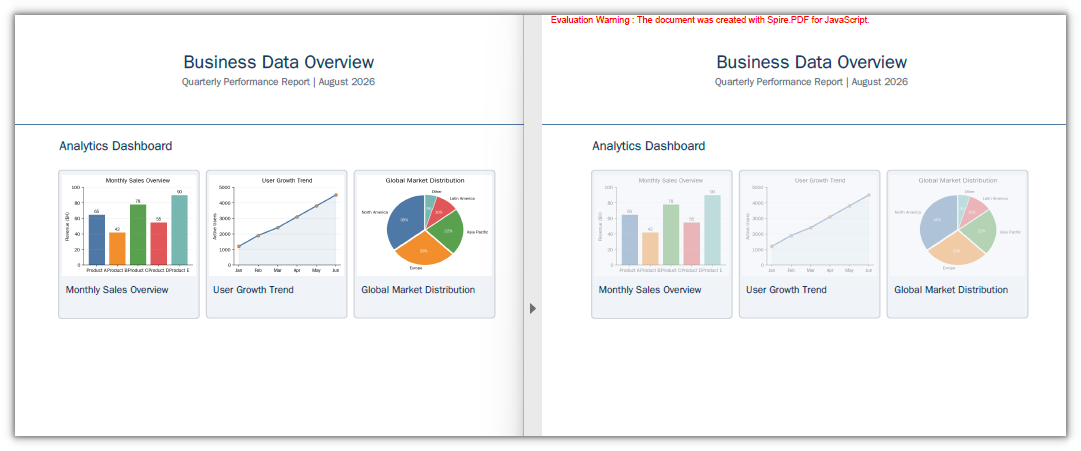
The three images on the page are redrawn at their original positions with 40% opacity, while the body text is unaffected:
FAQ
Why does content drawn after the image also become semi-transparent?
Cause: Transparency is part of the canvas state. Every drawing call after SetTransparency() keeps using that value until the state is restored or set again.
Solution: Wrap the setting in Save() and Restore() so the transparency applies only to the drawing in between:
const state = page.Canvas.Save();
page.Canvas.SetTransparency({ alpha: 0.35 });
page.Canvas.DrawImage({ image: image, x: 145, y: 400, width: 300, height: 173 });
page.Canvas.Restore({ state: state });
When adjusting existing images, why does only the last image become transparent?
Cause: DeleteImage() rewrites the page content stream. If you redraw right after each delete, the next delete overwrites the previous drawing, and often only the last image remains.
Solution: Split the work into three passes: read every image stream and bounds, delete all original images, then redraw them all.
// Delete all original images first
for (let i = 0; i < items.length; i++) {
  helper.DeleteImage({ imageInfo: items[i].info });
}

// Then redraw all of them
for (let i = 0; i < items.length; i++) {
  const { image, bounds } = items[i];
  const state = page.Canvas.Save();
  page.Canvas.SetTransparency({ alpha: 0.4 });
  page.Canvas.DrawImage({
    image: image,
    x: bounds.X,
    y: bounds.Y,
    width: bounds.Width,
    height: bounds.Height
  });
  page.Canvas.Restore({ state: state });
}
How do I adjust only one image on the page?
Cause: GetImagesInfo() returns all images on the page in order, each as a PdfImageInfo whose bounds are available from Bounds.
Solution: Skip the loop and process only the item you need. The following adjusts just the first image:
let images = helper.GetImagesInfo(page);
let info = images[0];
let image = pdfModule.PdfImage.FromStream(info.Image);
let bounds = info.Bounds;

helper.DeleteImage({ imageInfo: info });

const state = page.Canvas.Save();
page.Canvas.SetTransparency({ alpha: 0.4 });
page.Canvas.DrawImage({ image: image, x: bounds.X, y: bounds.Y, width: bounds.Width, height: bounds.Height });
page.Canvas.Restore({ state: state });
What do alpha values of 0 and 1 do?
Cause: alpha represents opacity and takes a linear value from 0 to 1.
Solution: At 0 the image is fully transparent and invisible on the page; at 1 it is fully opaque and looks exactly like a direct draw. For a faded effect, 0.2 to 0.5 is the usual range.
Get a Free License
If you want to remove the evaluation message from result documents or lift feature limits, contact sales for a temporary 30-day license.
Convert PowerPoint to Markdown in Python
PowerPoint locks content inside slides. Each page is a canvas, and titles and body text sit in separate shape frames. To move that content into documents, a knowledge base, or a large language model, you first need to turn it back into editable plain text. Markdown works well for that layer, and in a Git repository it also shows line-by-line diffs.
This article uses Spire.Presentation for Python to convert PowerPoint presentations to Markdown. You can also export only one slide, or export several slides in a loop. The process runs without Microsoft PowerPoint installed.
This article covers:
- Install the Python PowerPoint to Markdown library
- Convert a whole PowerPoint presentation to Markdown
- Export a specific slide to Markdown
- Summary
- FAQ
Install the Python PowerPoint to Markdown Library
Install Command
Before converting, install the library with pip:
pip install Spire.Presentation
For installation help, see How to Install Spire.Presentation for Python in VS Code.
Convert a Whole PowerPoint Presentation to Markdown
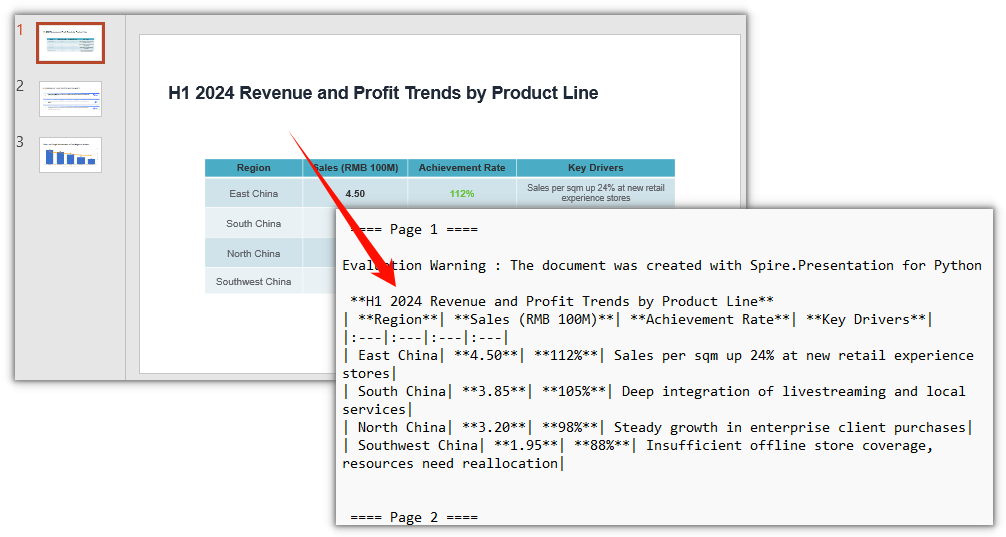
Presentation.SaveToFile with FileFormat.Markdown converts a whole PowerPoint presentation to Markdown in one call. Titles, paragraphs and tables keep their original hierarchy, and slides are separated by ==== Page N ==== page markers.
Steps:
- Create a
Presentationobject. - Load the PPT/PPTX file with
Presentation.LoadFromFile. - Save the whole presentation as Markdown with
Presentation.SaveToFileandFileFormat.Markdown. - Release resources.
from spire.presentation import *

# Create a Presentation object
presentation = Presentation()

# Load the PowerPoint file
presentation.LoadFromFile("DataBriefing.pptx")

# Save the whole presentation as a Markdown file
presentation.SaveToFile("DataBriefing.md", FileFormat.Markdown)

# Release resources
presentation.Dispose()
The Markdown file produced by converting the whole PowerPoint presentation:
Export a Specific Slide to Markdown
When you need just one page, there is no need to export the whole deck and trim it afterward. ISlide.SaveToFile exports a specific slide to Markdown: get the target page with Slides[index], then save it as Markdown on its own.
Steps:
- Create a
Presentationobject. - Load the PPT/PPTX file with
Presentation.LoadFromFile. - Get the target slide with
Presentation.Slides[index]. - Save that slide as Markdown with
ISlide.SaveToFileandFileFormat.Markdown. - Release resources.
from spire.presentation import *

# Create a Presentation object
presentation = Presentation()

# Load the PowerPoint file
presentation.LoadFromFile("DataBriefing.pptx")

# Get the second slide (index starts at 0)
slide = presentation.Slides[1]

# Save the specified slide as a Markdown file
slide.SaveToFile("Slide-2.md", FileFormat.Markdown)

# Release resources
presentation.Dispose()
The Markdown file produced by exporting a specific slide:
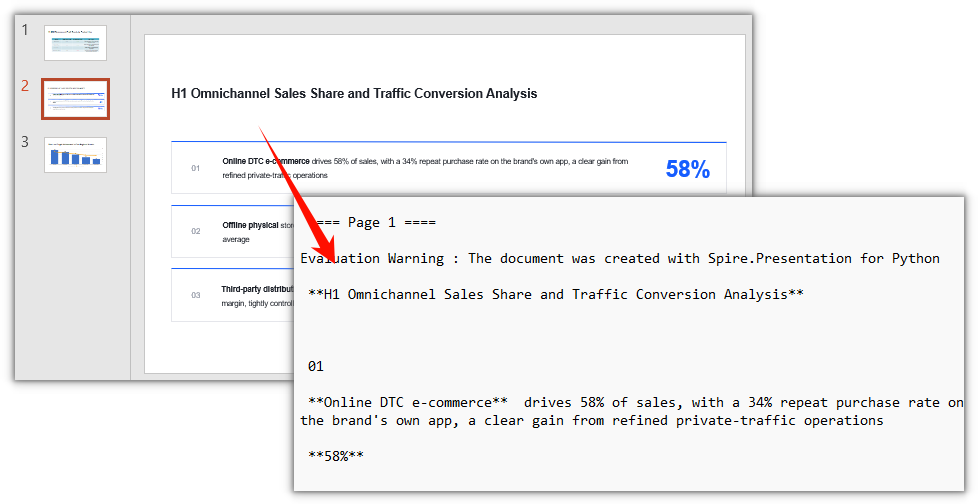
Export Multiple Slides to Markdown at Once
When you need more than one page, put the slide indexes in a loop and call Slides[index].SaveToFile page by page. Each slide is saved as its own Markdown file:
from spire.presentation import *

# Create a Presentation object
presentation = Presentation()

# Load the PowerPoint file
presentation.LoadFromFile("DataBriefing.pptx")

# Export the first and second slides in order
for index in (0, 1):
    slide = presentation.Slides[index]
    slide.SaveToFile(f"Slide-{index + 1}.md", FileFormat.Markdown)

# Release resources
presentation.Dispose()
Each slide is exported separately, so page numbers in the Markdown restart from Page 1.
Summary
Whole-deck conversion and single-slide export both work on the same Presentation object. LoadFromFile reads the file, FileFormat.Markdown sets the output format, and SaveToFile writes it out. Export the whole deck directly when that is what you need. To take only a few pages, pull out the target slides and save them individually, or put them in a loop.
FAQ
Do I need Microsoft PowerPoint installed to convert
Reason: Spire.Presentation for Python parses the PPT/PPTX file structure itself and does not call Office components.
Solution: No. Install the Python library and the conversion runs.
Can I convert multiple PowerPoint files at once
Reason: One Presentation object maps to one presentation, so it handles one file at a time.
Solution: Put the conversion logic in a loop and process each PPT/PPTX in a directory:
import os
from spire.presentation import *

for name in os.listdir("presentations"):
    if name.endswith(".pptx"):
        presentation = Presentation()
        presentation.LoadFromFile(os.path.join("presentations", name))
        base = os.path.splitext(name)[0]
        presentation.SaveToFile(os.path.join("markdown", base + ".md"), FileFormat.Markdown)
        presentation.Dispose()
Why does each page in the exported Markdown start with a warning line
Reason: Without a license applied, Spire.Presentation for Python inserts an Evaluation Warning line into the exported content.
Solution: Apply a temporary license and the line no longer appears. See "Get a Free License" below.
Get a Free License
If you want to remove the evaluation message from the result document or lift the feature limits, contact sales for a temporary license valid for 30 days.
Add or Delete PowerPoint Slides Using JavaScript in React
The same deck often needs more or fewer slides for different occasions: add two case-study pages for a client meeting, then drop the outdated ones after the previous version has been used. Doing this by hand in desktop software means someone babysitting the file, and it is hard to fold into a batch Web workflow; doing it server-side means uploading the file first, which takes it off the user's device.
This article shows how to add and delete PowerPoint slides directly in the browser with Spire.Presentation for JavaScript. Everything runs in the browser on WebAssembly — no Office install, no backend, and the file stays on the user's device.
The article covers three features:
- Add PowerPoint slides at the end
- Insert PowerPoint slides at a specific position
- Delete PowerPoint slides
For installation and project setup, see How to Integrate Spire.Presentation for JavaScript in a React Project. The examples below assume Spire.Presentation is installed and the WebAssembly module is initialized.
Add PowerPoint Slides at the End
Spire.Presentation for JavaScript adds a new slide at the end of a presentation with the Slides.Append() method. What gets added depends on the arguments:
| Call | What it appends |
|---|---|
Slides.Append() |
A new slide with the default (blank) layout |
Slides.Append({ template: <layout object> }) |
A new slide built from the given layout |
Slides.Append({ slide }) |
A copy of an existing slide |
To build a slide from a specific layout, get the layout object first: ppt.Masters.get_Item(0).Layouts.get_Item(i) — the i-th layout under the first slide master (i is 0-based).
The steps are as follows:
- Get the Spire.Presentation WASM module and confirm it is ready.
- Read the sample presentation and the font into the VFS, create a
Presentationobject, and load the file. - Add slides at the end with
Presentation.Slides.Append()(passtemplateorslideto choose the content). - Save the result with
Presentation.SaveToFile(). - Read the result back from the VFS and trigger a browser download.
The code for adding PowerPoint slides:
function App() {
  const addSlides = async () => {
    // Get the Spire.Presentation WASM module
    const pptModule = window.wasmModule?.spirepresentation;

    // Check whether the module is ready
    if (!pptModule) {
      alert('Spire.Presentation is not ready yet');
      return;
    }

    // Load the sample presentation and the font
    await window.spire.FetchFileToVFS('SamplePresentation.pptx', "", `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS('ARIALUNI.TTF', "/Library/Fonts/", `${process.env.PUBLIC_URL}/font/`);

    // Create a Presentation instance and load the presentation
    const ppt = new pptModule.Presentation();
    ppt.LoadFromFile('SamplePresentation.pptx');

    // Append in turn: default layout, a chosen layout, a clone of the first slide
    ppt.Slides.Append();
    ppt.Slides.Append({ template: ppt.Masters.get_Item(0).Layouts.get_Item(1) });
    ppt.Slides.Append({ slide: ppt.Slides.get_Item(0) });

    // Save the result
    const outputFileName = 'SlidesAdded.pptx';
    ppt.SaveToFile({ file: outputFileName, fileFormat: pptModule.FileFormat.Pptx2013 });
    ppt.Dispose();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.presentationml.presentation' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add PowerPoint Slides</h1>
      <button onClick={addSlides}>
        Add Slides
      </button>
    </div>
  );
}

export default App;
After appending three slides to the end:
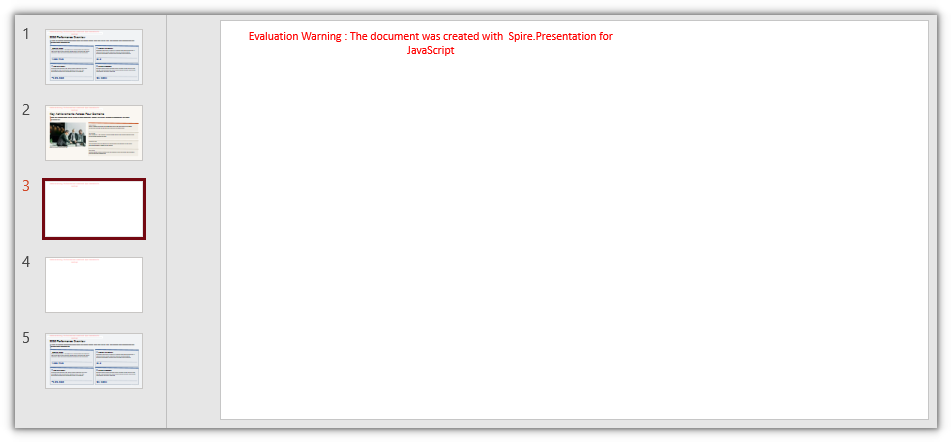
Insert PowerPoint Slides at a Specific Position
Slides.Insert() takes an index that sets where the slide goes: it is inserted at that index and the slides after it shift back. The content is again decided by the arguments:
| Call | What it inserts |
|---|---|
Slides.Insert({ index, template: <layout object> }) |
A new slide built from the given layout, inserted at index |
Slides.Insert({ index, slide }) |
A copy of an existing slide inserted at index |
The layout object is obtained the same way as for Slides.Append().
The steps are as follows:
- Get the Spire.Presentation WASM module and confirm it is ready.
- Read the sample presentation and the font into the VFS, create a
Presentationobject, and load the file. - Insert slides at the given positions with
Presentation.Slides.Insert(). - Save the result with
Presentation.SaveToFile(). - Read the result back from the VFS and trigger a browser download.
The code for inserting PowerPoint slides:
function App() {
  const insertSlides = async () => {
    // Get the Spire.Presentation WASM module
    const pptModule = window.wasmModule?.spirepresentation;

    // Check whether the module is ready
    if (!pptModule) {
      alert('Spire.Presentation is not ready yet');
      return;
    }

    // Load the sample presentation and the font
    await window.spire.FetchFileToVFS('SamplePresentation.pptx', "", `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS('ARIALUNI.TTF', "/Library/Fonts/", `${process.env.PUBLIC_URL}/font/`);

    // Create a Presentation instance and load the presentation
    const ppt = new pptModule.Presentation();
    ppt.LoadFromFile('SamplePresentation.pptx');

    // Insert in turn: a chosen layout, a clone of the first slide
    ppt.Slides.Insert({ index: 1, template: ppt.Masters.get_Item(0).Layouts.get_Item(1) });
    ppt.Slides.Insert({ index: 2, slide: ppt.Slides.get_Item(0) });

    // Save the result
    const outputFileName = 'SlidesInserted.pptx';
    ppt.SaveToFile({ file: outputFileName, fileFormat: pptModule.FileFormat.Pptx2013 });
    ppt.Dispose();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.presentationml.presentation' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Insert PowerPoint Slides</h1>
      <button onClick={insertSlides}>
        Insert Slides
      </button>
    </div>
  );
}

export default App;
After inserting two slides in the middle:
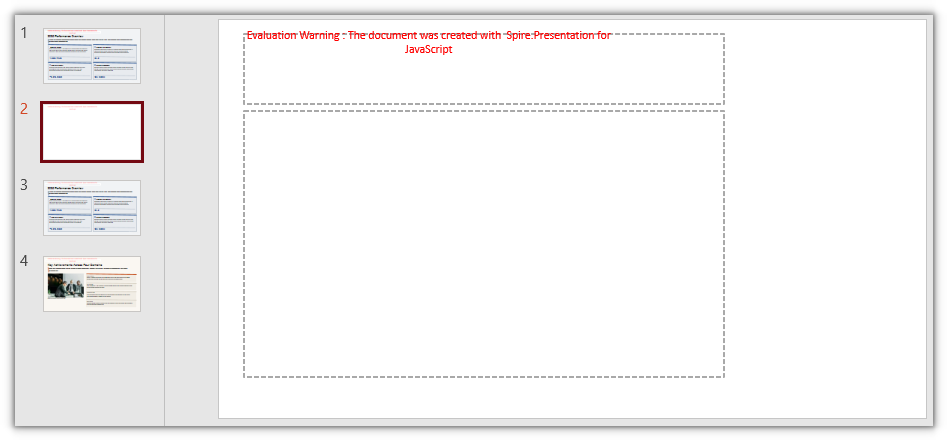
Delete PowerPoint Slides
Spire.Presentation for JavaScript can delete slides too, with Slides.RemoveAt() or Slides.Remove(). They target a slide differently:
| Method | Based on |
|---|---|
Slides.RemoveAt(index) |
The position of the slide (0-based index) |
Slides.Remove(slide) |
The slide object itself |
Each removal shifts the index of every later slide back by one.
The steps are as follows:
- Get the Spire.Presentation WASM module and confirm it is ready.
- Read the sample presentation and the font into the VFS, create a
Presentationobject, and load the file. - Delete a slide by index with
Presentation.Slides.RemoveAt(). - Save the result with
Presentation.SaveToFile(). - Read the result back from the VFS and trigger a browser download.
The code for deleting PowerPoint slides:
function App() {
  const removeSlides = async () => {
    // Get the Spire.Presentation WASM module
    const pptModule = window.wasmModule?.spirepresentation;

    // Check whether the module is ready
    if (!pptModule) {
      alert('Spire.Presentation is not ready yet');
      return;
    }

    // Load the sample presentation and the font
    await window.spire.FetchFileToVFS('SamplePresentation.pptx', "", `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS('ARIALUNI.TTF', "/Library/Fonts/", `${process.env.PUBLIC_URL}/font/`);

    // Create a Presentation instance and load the presentation
    const ppt = new pptModule.Presentation();
    ppt.LoadFromFile('SamplePresentation.pptx');

    // RemoveAt deletes by index: once the first slide is gone, the slides after it shift back
    ppt.Slides.RemoveAt(0);

    // Save the result
    const outputFileName = 'SlidesRemoved.pptx';
    ppt.SaveToFile({ file: outputFileName, fileFormat: pptModule.FileFormat.Pptx2013 });
    ppt.Dispose();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.presentationml.presentation' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Delete PowerPoint Slides</h1>
      <button onClick={removeSlides}>
        Remove Slides
      </button>
    </div>
  );
}

export default App;
After deleting a slide:
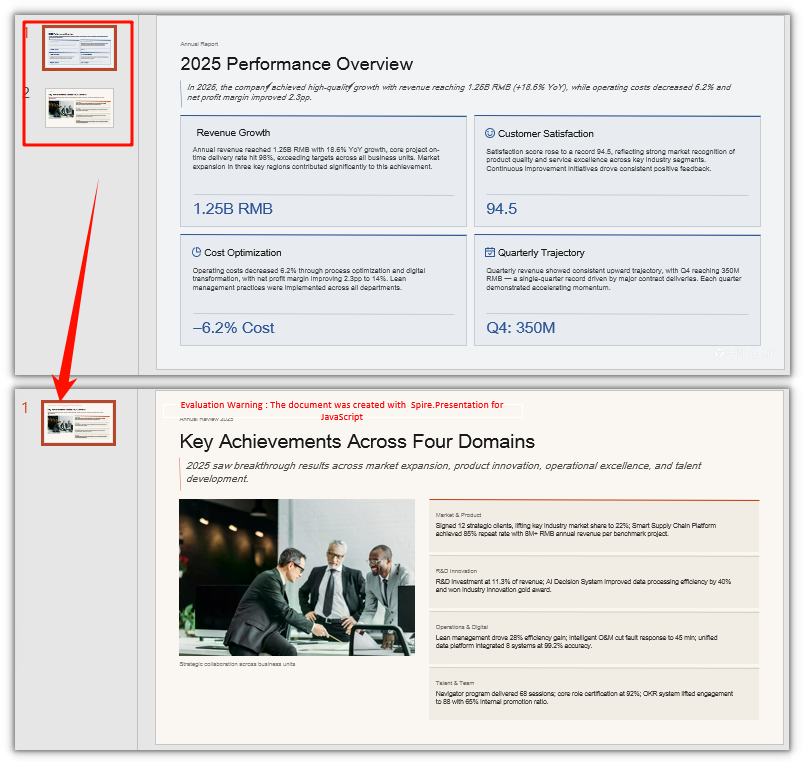
Delete a Slide by Object
Slides.RemoveAt() above deletes by index; Slides.Remove() takes a slide object instead. To point at a page, fetch it with Slides.get_Item(index) and hand it to Slides.Remove():
// Delete by object: fetch the second slide, then remove it
ppt.Slides.Remove(ppt.Slides.get_Item(1));
FAQ
Do the files need to be uploaded to a server
Not with the usage in this article. Spire.Presentation for JavaScript runs in the browser on WebAssembly, and presentations are read and written locally through a virtual file system (VFS) — adding, deleting, and saving all happen locally, and the library itself does not send files to a server. Whether a file leaves the device in the end depends on the other code you add to the page.
Can I add or delete several slides at once
Yes, just call in a loop: call Slides.Append() / Slides.Insert() several times to add or insert; when deleting several slides, handle the indices in order, or it is easy to delete the wrong slide or go out of range (see the last question).
Why does a new Presentation already contain a blank slide
Cause: A presentation created with new Presentation() already contains one blank slide; Append() only adds to the end and does not replace it.
Fix: To start from empty, remove it first, then append the slides you need:
let ppt = new pptModule.Presentation();

// Remove the blank slide it comes with
ppt.Slides.RemoveAt(0);

// Then append as needed
ppt.Slides.Append({ template: ppt.Masters.get_Item(0).Layouts.get_Item(1) });
Why is Append() without arguments a blank page
Cause: With no arguments it creates a slide with the default (blank) layout, so there are no ready-made title or body placeholders and it looks like an empty page.
Fix: To get ready-made placeholders, pass a layout that has them, or clone an existing slide; you can also add content yourself on the new page with Shapes.AppendShape():
// Build from a layout, so the page comes with title and content placeholders
ppt.Slides.Append({ template: ppt.Masters.get_Item(0).Layouts.get_Item(1) });

// Clone the first slide, and its content comes along
ppt.Slides.Append({ slide: ppt.Slides.get_Item(0) });
Why do I delete the wrong slide, or hit an index-out-of-range error, when removing several slides
Cause: Slides is indexed by position, and every removal shifts the index of the slides after it back by one. When you delete "front to back" with fixed indices (RemoveAt(0), RemoveAt(1), …), the second step no longer deletes the slides you meant; and once an index goes past the current count (Slides.Count - 1), RemoveAt throws.
Fix: Do not use increasing fixed indices for several deletions; delete the current first slide (index 0) every time — the slides after it fill in automatically:
// Delete the first three slides: always remove index 0 and the following slides shift up
for (let i = 0; i < 3; i++) {
  ppt.Slides.RemoveAt(0);
}
Get a Free License
If you want to remove the evaluation message from the result document or lift the feature limits, contact sales for a temporary license valid for 30 days.
Convert SVG to PDF in React with JavaScript
The charts, flow diagrams, and logos exported on the web are mostly SVG, yet printing, archiving, or an approval workflow usually asks for PDF. Saving them one by one in office software takes a person sitting through it, and batch-converting on a server means uploading the files first.
This article uses Spire.PDF for JavaScript to bridge SVG and PDF. It is built on WebAssembly, loading and saving documents in the browser, and it reads and writes files through a virtual file system (VFS), with no backend involved. There are two paths: turn an SVG into a PDF file on its own, or draw the SVG as vector graphics onto a chosen page of an existing PDF.
This article covers two core features:
For installation and project configuration, refer to Integrate Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is already installed and the WebAssembly module is initialized.
Convert an SVG to PDF
Spire.PDF for JavaScript provides the PdfDocument.LoadFromSvg method, which loads an SVG as a PDF document. The loaded document has a single page, and the page size is taken from the width/height on the SVG root element.
The steps are as follows:
- Get the Spire.PDF WASM module and make sure it is ready.
- Read the SVG file into the virtual file system (VFS).
- Create a
PdfDocumentobject and load the SVG with theLoadFromSvg()method. - Use the
PdfDocument.SaveToFile()method to save the result file. - Read the result file from the VFS and trigger a browser download.
The code to convert an SVG to PDF is as follows:
function App() {
  const convertSvgToPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the SVG to convert into the VFS
    const inputFileName = 'VectorChart.svg';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Load the SVG: the document has a single page, the size of the SVG
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromSvg({ fileName: inputFileName });

    // Save the result file
    const outputFileName = 'VectorChart.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert SVG to PDF</h1>
      <button onClick={convertSvgToPdf}>
        Convert to PDF
      </button>
    </div>
  );
}

export default App;
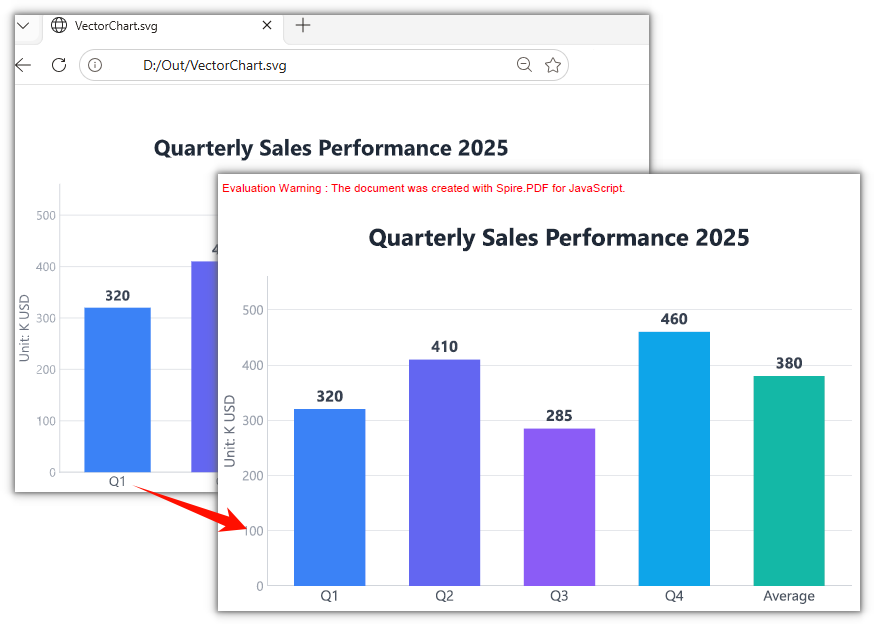
The result is a single-page PDF whose page size matches the SVG:
Draw an SVG onto an Existing PDF
Spire.PDF for JavaScript also provides the PdfPageBase.CreateTemplate method and the PdfCanvas.DrawTemplate method, which overlay an SVG onto an already laid-out PDF. Load the SVG, turn its single page into a template, then draw it onto the target page at a chosen position and size — the original document's page count, page size, and existing content are untouched.
The steps are as follows:
- Get the Spire.PDF WASM module and make sure it is ready.
- Read the existing PDF and the SVG logo into the virtual file system (VFS).
- Create a
PdfDocumentobject for each and load the existing PDF and the SVG. - Use the
CreateTemplate()method to turn the SVG's first page into a template, then draw it onto the target page with theCanvas.DrawTemplate()method, at a given position and size. - Use the
SaveToFile()method to save the PDF that was drawn on, then read the result file from the VFS and trigger a browser download.
The code to draw an SVG onto an existing PDF is as follows:
function App() {
  const drawSvgOnPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load both the existing PDF and the SVG logo into the VFS
    const pdfFileName = 'ProductManual.pdf';
    const svgFileName = 'VectorLogo.svg';
    await window.spire.FetchFileToVFS(pdfFileName, '', `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS(svgFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Load the existing PDF
    let existingPdf = new pdfModule.PdfDocument();
    existingPdf.LoadFromFile(pdfFileName);

    // Load the SVG and turn its single page into a template
    let svgDoc = new pdfModule.PdfDocument();
    svgDoc.LoadFromSvg({ fileName: svgFileName });
    const template = svgDoc.Pages.get_Item(0).CreateTemplate();

    // Draw the template on page 1: position and size are in points, origin at the top-left of the page
    const location = new pdfModule.PointF(390, 50);
    const size = new pdfModule.SizeF(130, 60);
    existingPdf.Pages.get_Item(0).Canvas.DrawTemplate({ template, location, size });

    // Save the PDF that was drawn on
    const outputFileName = 'ProductManual_WithLogo.pdf';
    existingPdf.SaveToFile(outputFileName);
    svgDoc.Close();
    existingPdf.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Draw SVG on Existing PDF</h1>
      <button onClick={drawSvgOnPdf}>
        Insert SVG
      </button>
    </div>
  );
}

export default App;
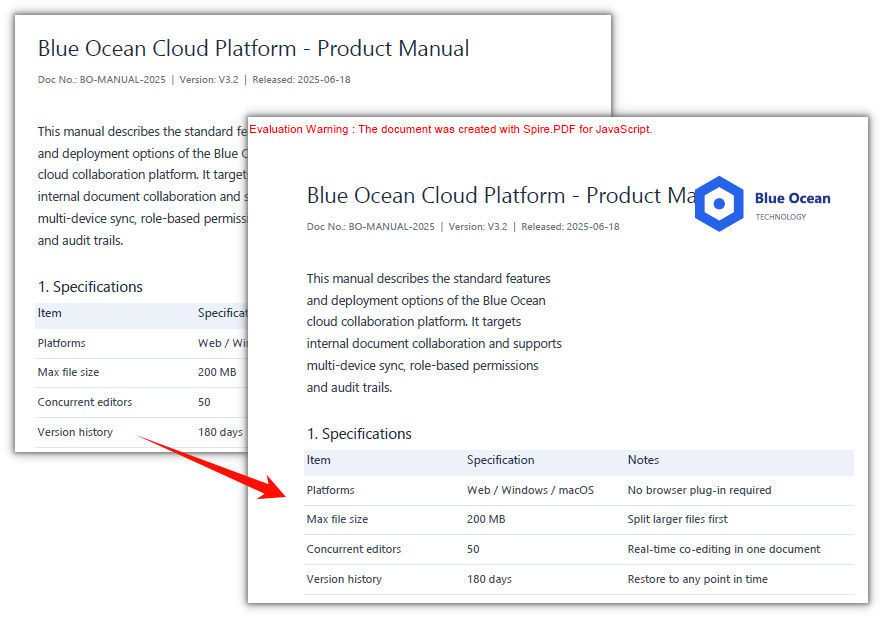
The original manual content is unchanged, with a vector logo added at the top right:
Frequently Asked Questions
Why isn't the output PDF A4-sized
Cause: When LoadFromSvg creates the page it takes the width/height from the SVG root element, converting pixels to points at 75%. In the example, a 760 × 520 SVG becomes a single page of 570 × 390 points — nothing to do with A4.
Solution: To use another size, change the width, height, or viewBox on the SVG root element and convert again.
How do I draw the SVG on another page or at another position
Cause: Which page DrawTemplate draws on is decided by how the page is fetched, and which corner it lands in is decided by location; both are passed in explicitly by the caller.
Solution: Switch pages with Pages.get_Item(index) (0-based), change the position via PointF, and the size via SizeF — all in points, with the origin at the top-left of the page:
// Draw on page 2, bottom left, at a size of 100 × 46 points
existingPdf.Pages.get_Item(1).Canvas.DrawTemplate({
  template: template,
  location: new pdfModule.PointF(40, 760),
  size: new pdfModule.SizeF(100, 46),
});
Is the inserted SVG vector or a bitmap
Cause: What CreateTemplate returns is a PDF template corresponding to the SVG content, and DrawTemplate draws it into the page as vectors, without going through a bitmap.
Solution: Nothing extra to set. Zoom in on the page afterwards and the logo's edges stay crisp; it prints without blurring either.
Get a Free License
If you would like to remove the evaluation message from the result document or lift feature restrictions, please contact sales for a 30-day temporary license.
Convert PDF to SVG in React with JavaScript
When charts and diagrams inside a PDF are reused on the web, the usual approach is to render them to PNG first — a bitmap blurs when scaled up, and a different resolution means taking a new screenshot. Web illustrations, vector icons, and print layouts that need to scale to any size really call for SVG.
This article uses Spire.PDF for JavaScript to convert PDF to SVG. It loads and saves PDF documents in the browser on top of WebAssembly, and the whole conversion runs locally: files are read and written through a virtual file system (VFS), with no backend involved. Output has two forms — the whole document merged into one SVG, or one SVG per page.
This article covers two core features:
For installation and project configuration, refer to Integrate Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is already installed and the WebAssembly module is initialized.
Convert the Whole PDF to a Single SVG
Spire.PDF for JavaScript provides the PdfDocument.ConvertOptions.OutputToOneSvg property, which decides whether the whole document is written to one SVG or to one file per page. It defaults to false, so each page becomes its own file; set it to true and the pages are stacked vertically on a single canvas in their original order, then written out by SaveToFile with FileFormat.SVG.
The steps are as follows:
- Get the Spire.PDF WASM module and make sure it is ready.
- Load the sample PDF and the Arial font, create a
PdfDocumentobject, and load the file. - Set
PdfDocument.ConvertOptions.OutputToOneSvgtotrueso all pages go into one SVG. - Use the
PdfDocument.SaveToFile()method to save the result file. - Read the result file from the VFS and trigger a browser download.
The code to convert the whole PDF to a single SVG is as follows:
function App() {
  const convertPdfToOneSvg = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Converting to SVG restores the page text, so put the Arial font into the VFS font directory first
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Load the PDF to convert into the VFS
    const inputFileName = 'Chapter_Document.pdf';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Output file name: the whole document merged into one SVG
    const outputFileName = 'Chapter_Document.svg';

    // Load the PDF and send all pages into a single SVG
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);
    doc.ConvertOptions.OutputToOneSvg = true;
    doc.SaveToFile(outputFileName, pdfModule.FileFormat.SVG);
    doc.Close();

    // Read the generated file from the VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'image/svg+xml' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF to SVG</h1>
      <button onClick={convertPdfToOneSvg}>
        Convert to a single SVG
      </button>
    </div>
  );
}

export default App;
The result is a single SVG file with the five pages joined top to bottom:
Convert Each PDF Page to a Separate SVG
Spire.PDF for JavaScript also provides the PdfToSvgConverter class, which converts a document to SVG page by page. It is a second, equivalent entry point to PdfDocument, and SvgOptions carries OutputToOneSvg as well. This section keeps the default per-page output and downloads the files one by one.
The steps are as follows:
- Get the Spire.PDF WASM module and make sure it is ready.
- Load the sample PDF and the Arial font.
- Create a
PdfToSvgConverterobject, passing the path of the PDF to convert. - Use the
PdfToSvgConverter.Convert()method to convert page by page, one SVG per page. - Read each page's file from the VFS and trigger a download for each.
The code to convert each PDF page to a separate SVG is as follows:
function App() {
  const convertPdfPagesToSvg = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Converting to SVG restores the page text, so put the Arial font into the VFS font directory first
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Load the PDF to convert into the VFS
    const inputFileName = 'Chapter_Document.pdf';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Output file name prefix: pages are written as Chapter_Document_1.svg, Chapter_Document_2.svg, ...
    const outputFileName = 'Chapter_Document.svg';

    // Convert page by page with the converter
    const converter = new pdfModule.PdfToSvgConverter(inputFileName);
    converter.Convert(outputFileName);

    // Read each page's file from the VFS and trigger a download for each
    const fs = window.dotnetRuntime.Module.FS;
    const prefix = outputFileName.replace(/\.svg$/i, '_');
    const pageFiles = fs.readdir('/').filter((name) => name.startsWith(prefix) && name.endsWith('.svg'));

    for (const pageFile of pageFiles) {
      const blob = new Blob([fs.readFile(pageFile)], { type: 'image/svg+xml' });
      const url = URL.createObjectURL(blob);
      const a = document.createElement('a');
      a.href = url;
      a.download = pageFile;
      a.click();
      URL.revokeObjectURL(url);
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF to SVG</h1>
      <button onClick={convertPdfPagesToSvg}>
        Convert page by page
      </button>
    </div>
  );
}

export default App;
Each page becomes its own SVG file, named with the page number:
Set the SVG Size
The converter also exposes the SvgOptions.ScaleX and ScaleY properties, which scale the output size by a factor; both default to 1. Setting them to 2 doubles the size. The SVG content is vector, so — unlike a bitmap — it stays sharp when scaled.
// Scale the output size up by 2x
const converter = new pdfModule.PdfToSvgConverter('Chapter_Document.pdf');
converter.SvgOptions.ScaleX = 2;
converter.SvgOptions.ScaleY = 2;
converter.Convert('Chapter_Document.svg');
Frequently Asked Questions
Why do I get a bunch of xxx_1.svg, xxx_2.svg files instead of one .svg
Cause: When PdfDocument.SaveToFile converts to SVG it writes page by page, and ConvertOptions.OutputToOneSvg defaults to false, so the file name becomes "prefix_page.svg". A single-page PDF hides the difference; with more pages it shows up.
Solution: To get a single file, turn the property on before saving:
doc.ConvertOptions.OutputToOneSvg = true;
doc.SaveToFile('Chapter_Document.svg', pdfModule.FileFormat.SVG);
With PdfToSvgConverter, the matching switch is converter.SvgOptions.OutputToOneSvg — the two entry points use an equivalent switch and produce identical output.
How do I fix the error Cannot found font(Arial) installed on the system.
Cause: Converting to SVG restores page text as <text> elements, and the converter looks the font up by name in /Library/Fonts/ of the virtual file system. If that directory is empty, it throws this error.
Solution: Put the font into the VFS before LoadFromFile:
await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
Arial and Arial Unicode MS are two different files; supplying only the latter still raises the same error.
Is the text in the converted SVG still selectable
Cause: <text> and stroked paths are different things. The converter keeps page text as <text> elements and turns only graphics and lines into vector paths (<path>), so the text stays selectable and searchable.
Solution: No extra settings. Open the generated SVG in an editor and you will see <text> nodes; zoom it in a browser and neither the text nor the lines blur.
What if I only want to convert a few pages
Cause: SaveToFile also has an overload that takes a page range, working on the same per-page files that are saved in the VFS.
Solution: Pass the start and end page indexes; the index is 0-based and inclusive:
// Write only pages 1 and 2, producing first_two_pages_1.svg and first_two_pages_2.svg
doc.SaveToFile('first_two_pages.svg', 0, 1, pdfModule.FileFormat.SVG);
Get a Free License
If you would like to remove the evaluation message from the result document or lift feature restrictions, please contact sales for a 30-day temporary license.
Set an Expiry Date for a PDF Document Using JavaScript in React
Once a contract, quote, or trial document goes out as a PDF, the content is essentially in the recipient's hands, and when it stops being valid is left to their discretion. To make a document announce its expiry automatically after a set date, desktop software means opening each file and setting it by hand, which is hard to fit into a batch Web workflow; doing it server-side means uploading the files first, taking them off the user's device.
This article shows how to set an expiry date for a PDF document with Spire.PDF for JavaScript. Built on WebAssembly, it loads, modifies, and saves PDF documents directly in the browser. Everything runs locally, reading and writing files through a virtual file system (VFS), with no backend involved.
For installation and project setup, see How to Integrate Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Set an Expiry Date for a PDF Document
Spire.PDF for JavaScript provides the PdfJavaScriptAction class, which wraps a JavaScript snippet as a PDF action. Assign it to PdfDocument.AfterOpenAction and the reader runs the snippet every time the document is opened — the snippet compares the current time with the configured date and, once past it, shows an alert and closes the document.
Step 1: Load the PDF to Process
First get the Spire.PDF WASM module and confirm it is ready, then read the PDF into the virtual file system (VFS) and hand it to PdfDocument to load.
// Get the Spire.PDF WASM module
const pdfModule = window.wasmModule?.spirepdf;

// Check whether the module is ready
if (!pdfModule) {
  alert('Spire.PDF is not ready yet');
  return;
}

// Load the PDF into the VFS
const inputFileName = 'ContractTemplate.pdf';
await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

// Create a PdfDocument object and load the document
const doc = new pdfModule.PdfDocument();
doc.LoadFromFile(inputFileName);
Step 2: Write the Expiry Check Script
The expiry date lives in the script itself: new Date() captures the system time at the moment of opening and compares it with the configured deadline; if it is later, the two actions — alert and close — run. Both the alert text and the deadline are strings in this snippet, so changing the date or the wording happens here.
// Expiry check: alert and close the document once the current time is past the set date
const script =
  "var rightNow = new Date();" +
  "var endDate = new Date('January 1, 2026 23:59:59');" +
  "if (rightNow.getTime() > endDate.getTime()) {" +
  "app.alert('This document has expired, please contact us for a new one.', 1);" +
  "this.closeDoc();" +
  "}";
Step 3: Attach It to the Document's After-Open Action
The script does not run on its own; wrap it in a PdfJavaScriptAction and assign it to PdfDocument.AfterOpenAction. This is a document-level action that the reader runs when the document is opened, and it is written to disk along with the document on save.
// Wrap the script as a JavaScript action and attach it to the document's after-open action
doc.AfterOpenAction = new pdfModule.PdfJavaScriptAction(script);

// Save the document
const outputFileName = 'SetExpiryDate.pdf';
doc.SaveToFile(outputFileName);
doc.Close();
Step 4: Read the Result and Trigger the Download
The saved file is still in the VFS; read its bytes out, wrap them in a Blob, and hand a temporary link to the browser to download.
// Read the generated file from the VFS and trigger a download
const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
const blob = new Blob([fileArray], { type: 'application/pdf' });
const url = URL.createObjectURL(blob);
const a = document.createElement('a');
a.href = url;
a.download = outputFileName;
a.click();
URL.revokeObjectURL(url);
Complete Code
Put the four steps back into a single App component and you have a complete, runnable example.
function App() {
  const setExpiryDate = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF into the VFS
    const inputFileName = 'ContractTemplate.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the document
    const doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Expiry check: alert and close the document once the current time is past the set date
    const script =
      "var rightNow = new Date();" +
      "var endDate = new Date('January 1, 2026 23:59:59');" +
      "if (rightNow.getTime() > endDate.getTime()) {" +
      "app.alert('This document has expired, please contact us for a new one.', 1);" +
      "this.closeDoc();" +
      "}";

    // Wrap the script as a JavaScript action and attach it to the document's after-open action
    doc.AfterOpenAction = new pdfModule.PdfJavaScriptAction(script);

    // Save the document
    const outputFileName = 'SetExpiryDate.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Set an Expiry Date for a PDF Document</h1>
      <button onClick={setExpiryDate}>
        Set Expiry Date
      </button>
    </div>
  );
}

export default App;
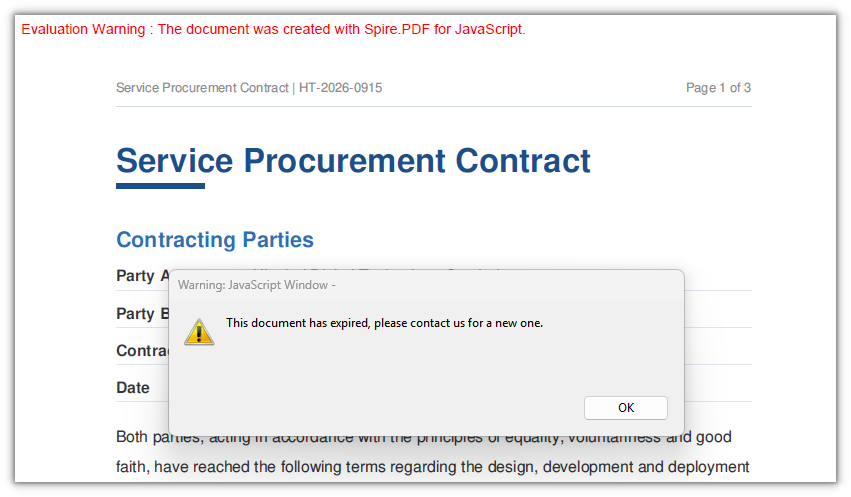
After setting an expiry date on the contract template, opening it in a JavaScript-capable reader shows an alert and then closes the expired document:
FAQ
Why doesn't the alert appear when I open the document after setting the date
Cause: The expiry check depends on the reader running the JavaScript action embedded in the document. Built-in browser PDF viewers and most system preview tools do not execute embedded scripts; only JavaScript-capable readers such as Adobe Acrobat or Acrobat Reader run it when the document opens.
Fix: Open the generated PDF in a JavaScript-capable reader. The script is already written into the document, so switching readers is enough to see it — there is no need to regenerate the file.
Does the content become completely inaccessible once the document expires
Cause: The script shows an alert and closes the current reading session; it does not alter the document's content or encrypt it. The file is still an ordinary PDF and can be opened and text-extracted by any tool that does not run scripts.
Fix: To actually block access, encrypt the document and set an open password or permission restrictions. The expiry script is a reminder and a deterrent, not access control.
How do I change the expiry date or the alert text
Cause: The date and the alert are string literals in the script — the date inside new Date('…') and the text inside app.alert('…'). They are written into the document's open action together with the script, so changing document properties afterward does not affect them.
Fix: Edit these two strings in the script and generate the document again:
const script =
  "var rightNow = new Date();" +
  "var endDate = new Date('December 31, 2026 23:59:59');" +   // new expiry moment
  "if (rightNow.getTime() > endDate.getTime()) {" +
  "app.alert('Your trial has expired. Please purchase the full version.', 1);" +   // new alert text
  "this.closeDoc();" +
  "}";
How do I make the document expire 30 days after it is opened
Cause: The script runs every time the document is opened, and new Date() returns the system time at that moment. If the date is also derived from the opening time — for example new Date() plus 30 days — the computed deadline keeps moving forward on every open and the document never actually expires.
Fix: Write the expiry date as a fixed value: work out the moment 30 days out at generation time and put that in, leaving the script to only compare the current time against it:
// Compute a fixed moment at generation time and put it in the script; do not leave it to be calculated at open time
"var endDate = new Date('October 15, 2026 23:59:59');" +
Get a Free License
If you want to remove the evaluation message from the result document or lift the feature limits, contact sales for a temporary license valid for 30 days.
Modify and Delete Hyperlinks in PDF with JavaScript in React
PDF hyperlinks are supposed to be the easiest part of a document — one click and you are there, with no copying and no typing. But once they have to be maintained in bulk, the situation flips: a product document changes domain and every URL has to be fixed one by one; an old manual is about to be published and its external links have to be cleared first. In desktop software these jobs mean clicking through by hand, or cannot be done in bulk at all.
This article shows how to modify and delete hyperlinks with Spire.PDF for JavaScript. It is built on WebAssembly and loads, modifies and saves PDF documents directly in the browser; the whole process runs locally through a virtual file system (VFS), with no backend required.
This article covers two key operations:
For installation and project setup, refer to How to Integrate Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module has been initialized.
Modify Hyperlinks
When a document's URLs change domain, resetting them one by one is tedious. An existing link annotation can be read and written through PdfUriAnnotationWidget, whose Uri property is the link's target address. Walking the annotation collection page by page and rewriting the matches changes links in bulk.
function App() {
  const updateHyperlinks = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF to be processed into the VFS
    const inputFileName = 'ProductManual.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // The new link address
    const newUrl = 'https://www.e-iceblue.com/Introduce/pdf-for-javascript.html';

    // Walk the annotations page by page and rewrite the URI links
    for (let i = 0; i < doc.Pages.Count; i++) {
      const page = doc.Pages.get_Item(i);
      for (let j = 0; j < page.Annotations.Count; j++) {
        const annotation = page.Annotations.get_Item(j);
        // Handle only link annotations; leave other annotation types as they are
        if (annotation instanceof pdfModule.PdfUriAnnotationWidget) {
          annotation.Uri = newUrl;
        }
      }
    }

    // Save the resulting document
    const outputFileName = 'HyperlinksUpdated.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const downloadUrl = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = downloadUrl;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(downloadUrl);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Modify Hyperlinks</h1>
      <button onClick={updateHyperlinks}>
        Update Hyperlinks
      </button>
    </div>
  );
}

export default App;
The three hyperlinks already in the document now point to the new address:
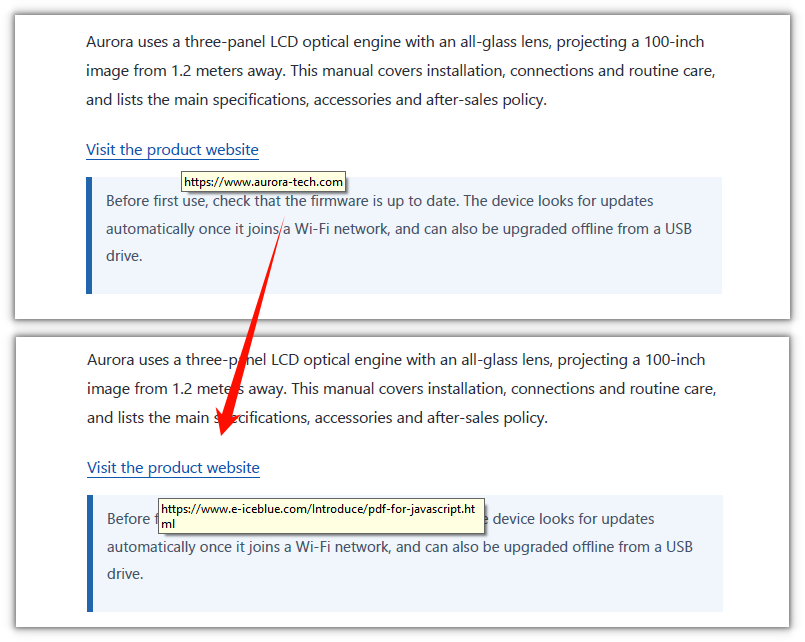
Delete Hyperlinks
Deleting hyperlinks is likewise a walk over the annotation collection, calling Remove on the matches. The difference is collecting first and deleting after: removing during the walk shifts the collection forward, and the loop then skips the entry right after the removed one.
function App() {
  const deleteHyperlinks = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF to be processed into the VFS
    const inputFileName = 'ProductManual.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Collect all link annotations first
    const links = [];
    for (let i = 0; i < doc.Pages.Count; i++) {
      const page = doc.Pages.get_Item(i);
      for (let j = 0; j < page.Annotations.Count; j++) {
        const annotation = page.Annotations.get_Item(j);
        if (annotation instanceof pdfModule.PdfUriAnnotationWidget) {
          links.push({ page, annotation });
        }
      }
    }

    // Remove them all after the collection is complete
    for (const link of links) {
      link.page.Annotations.Remove(link.annotation);
    }

    // Save the resulting document
    const outputFileName = 'HyperlinksRemoved.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const downloadUrl = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = downloadUrl;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(downloadUrl);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Delete Hyperlinks</h1>
      <button onClick={deleteHyperlinks}>
        Delete Hyperlinks
      </button>
    </div>
  );
}

export default App;
All hyperlinks in the document have been removed:
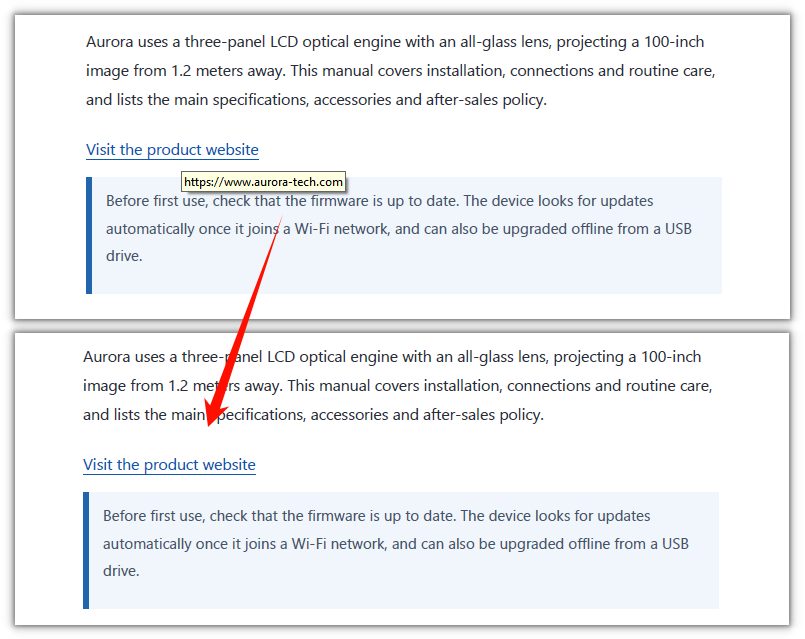
FAQ
I changed Uri, but the address is unchanged after saving
Cause: link annotations are not a single class. The Uri property exists only on PdfUriAnnotationWidget. A hyperlink exported from Word, or produced by Spire's PdfTextWebLink, is another class, PdfTextWebLinkAnnotationWidget, whose address property is called Url. Code that tests only one class skips the other entirely.
Solution: test both classes and set the matching property:
if (annotation instanceof pdfModule.PdfUriAnnotationWidget) {
  annotation.Uri = newUrl;
} else if (annotation instanceof pdfModule.PdfTextWebLinkAnnotationWidget) {
  annotation.Url = newUrl;
}
Why does deleting while iterating remove only some of the links?
Cause: page.Annotations is a mutable annotation collection. After item i is removed, the annotations behind it shift up by one, while the loop's i still increments as usual, so the entry immediately after the removed one is skipped. With several links on a page, several are missed.
Solution: collect the annotations to delete into an array first, then remove them all after the loop:
const links = [];
// ...collect while iterating...

// remove after the collection is complete
for (const link of links) {
  link.page.Annotations.Remove(link.annotation);
}
Does deleting hyperlinks also delete comments?
Cause: page.Annotations holds more than links — text box annotations, popups, form fields and so on all live in the same collection. Calling Clear(), or deleting everything without checking, wipes those out too.
Solution: delete only link annotations and leave the rest untouched:
if (annotation instanceof pdfModule.PdfUriAnnotationWidget) {
  page.Annotations.Remove(annotation);
}
Get a Free License
To remove the evaluation message from the generated documents, or to get rid of the function limitations, please contact sales for a temporary license valid for 30 days.
Add Hyperlinks to a PDF in React Using JavaScript
Hyperlinks in a PDF are meant to save work: one click and you are there, no copying an address, no retyping it. The catch is that they are rarely there when you need them. A brand-new document should come with its download page, a contact address and a product link already in place. An older, already laid-out document should send the product name recurring in its body to the same introduction page. Doing it by hand means dragging a selection and pasting an address at every spot — and on a long document that never ends.
Moving the job into the browser is what Spire.PDF for JavaScript is for: it loads, modifies and saves PDF documents directly on WebAssembly, with PdfTextWebLink drawing visible link text in one step and PdfFileLinkAnnotation attaching a document link. Everything runs locally, reading and writing files through a virtual file system (VFS) with no backend involved.
This article covers two core tasks:
For installation and project setup, see Integrate Spire.PDF for JavaScript in a React project. The example below assumes Spire.PDF is installed and the WebAssembly module is initialized.
Add Hyperlinks to a PDF
When you build a document from scratch, everything on the page is decided by code, and links fall into a few kinds:
- Simple text link: the URL drawn as ordinary text, with no annotation attached; whether it is clickable is up to the viewer — Chrome and others auto-detect the URL and make it clickable — so it is here only for contrast with the explicitly linked ones.
- Hypertext link:
PdfTextWebLinkwithText,Url,FontandBrushset;DrawTextWebLink()draws the underlined link text in one step. - Document link:
PdfFileLinkAnnotation(hotspot rectangle, target file), with the rectangle defined by you.
function App() {
  const addLinksToNewPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Drawing text needs a font; load it into the VFS first
    const fontVfs = '/Library/Fonts/ARIAL UNICODE MS.TTF';
    await window.spire.FetchFileToVFS('ARIAL UNICODE MS.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Create a blank document
    const doc = new pdfModule.PdfDocument();

    // Add a section and set its margins to 0: coordinates then equal page coordinates
    const section = doc.Sections.Add();
    section.PageSettings.Size = pdfModule.PdfPageSize.A4();
    const margins = new pdfModule.PdfMargins();
    margins.Top = 0;
    margins.Bottom = 0;
    margins.Left = 0;
    margins.Right = 0;
    section.PageSettings.Margins = margins;

    const page = section.Pages.Add();

    const font = new pdfModule.PdfTrueTypeFont({ fontFile: fontVfs, size: 13 });
    const linkFont = new pdfModule.PdfTrueTypeFont({ fontFile: fontVfs, size: 13, style: pdfModule.PdfFontStyle.Underline });
    const format = new pdfModule.PdfStringFormat({ alignment: pdfModule.PdfTextAlignment.Left });

    // Draw a plain line of text as a label
    const drawLabel = (text, y) => {
      page.Canvas.DrawString({
        s: text, font: font, brush: pdfModule.PdfBrushes.get_Black(), x: 60, y: y, format: format,
      });
    };

    // Draw a line of underlined text and hand back its rectangle as the hotspot
    const drawLinkText = (text, y) => {
      const size = linkFont.MeasureString({ text: text });
      page.Canvas.DrawString({
        s: text, font: linkFont, brush: pdfModule.PdfBrushes.get_Blue(), x: 160, y: y, format: format,
      });
      return new pdfModule.RectangleF({ x: 160, y: y, width: size.Width, height: size.Height });
    };

    const url = 'https://www.e-iceblue.com/Introduce/pdf-for-javascript.html';

    // 1) Simple text link: just the URL drawn as ordinary text, with no annotation attached (clickability depends on the viewer)
    let y = 80;
    drawLabel('Simple text link:', y);
    drawLinkText(url, y);

    // 2) Hypertext link: DrawTextWebLink draws the text and attaches the link in one step
    y += 34;
    drawLabel('Hypertext link:', y);
    const webLink = new pdfModule.PdfTextWebLink();
    webLink.Text = 'Visit our site';
    webLink.Url = url;
    webLink.Font = linkFont;
    webLink.Brush = pdfModule.PdfBrushes.get_Blue();
    webLink.DrawTextWebLink({ graphics: page.Canvas, location: new pdfModule.PointF(160, y) });

    // 3) Email link: same class, with a mailto: URL
    y += 34;
    drawLabel('Email link:', y);
    const mailLink = new pdfModule.PdfTextWebLink();
    mailLink.Text = 'Contact support';
    mailLink.Url = 'mailto:support@e-iceblue.com';
    mailLink.Font = linkFont;
    mailLink.Brush = pdfModule.PdfBrushes.get_Blue();
    mailLink.DrawTextWebLink({ graphics: page.Canvas, location: new pdfModule.PointF(160, y) });

    // 4) Document link: hotspot rectangle + target file
    y += 34;
    drawLabel('Document link:', y);
    const fileName = 'Report.xlsx';
    const fileBounds = drawLinkText('Open file', y);
    page.Annotations.Add(new pdfModule.PdfFileLinkAnnotation(fileBounds, fileName));

    // Save the result document
    const outputFileName = 'HyperlinkSample.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const downloadUrl = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = downloadUrl;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(downloadUrl);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add Hyperlinks</h1>
      <button onClick={addLinksToNewPdf}>
        Start Creating
      </button>
    </div>
  );
}

export default App;
All four links — simple text, hypertext, email and document — are in place in the new document:
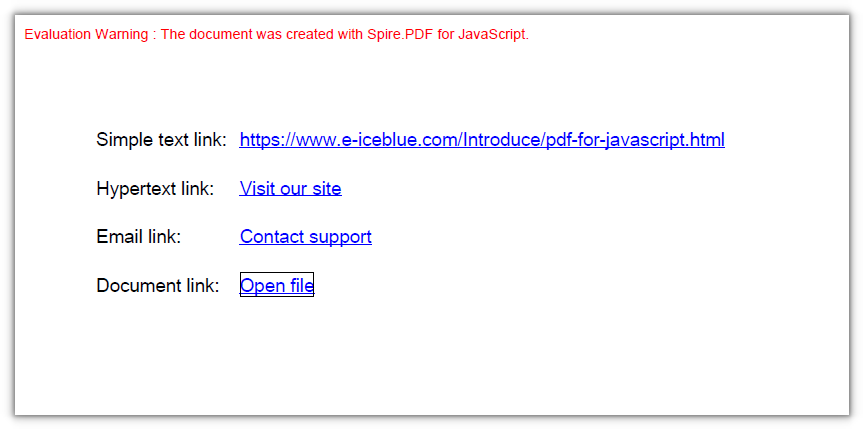
Add Hyperlinks to Text
To add links to an existing document, work the other way round: find the position in the document first, then lay the link over it. PdfTextFinder searches the text of a given page by keyword, and each match carries a bounding rectangle. Build a PdfUriAnnotation from it and add it to the page annotation collection, and the link lands exactly on the original text instead of you doing the measuring.
function App() {
  const addHyperlinksToText = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF to be processed into the VFS
    const inputFileName = 'ProductManual.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Take the first page
    const page = doc.Pages.get_Item(0);

    // Search the page for the keyword; Parameter is case-sensitive by default, so switch to IgnoreCase
    const finder = new pdfModule.PdfTextFinder(page);
    finder.Options.Parameter = pdfModule.TextFindParameter.IgnoreCase;
    const finds = finder.Find('Aurora');

    // Create one link annotation for each match
    const linkUrl = 'https://www.e-iceblue.com/Introduce/pdf-for-javascript.html';
    for (let i = 0; i < finds.length; i++) {
      // The bounding rectangle of a match is the link hotspot
      const annotation = new pdfModule.PdfUriAnnotation({ rectangle: finds.get(i).Bounds[0] });
      annotation.Uri = linkUrl;

      // Attach the annotation to the page annotation collection
      page.Annotations.Add(annotation);
    }

    // Save the result document
    const outputFileName = 'HyperlinksAdded.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const downloadUrl = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = downloadUrl;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(downloadUrl);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add Hyperlinks to Text</h1>
      <button onClick={addHyperlinksToText}>
        Start Adding
      </button>
    </div>
  );
}

export default App;
All three occurrences of Aurora now carry a hyperlink:
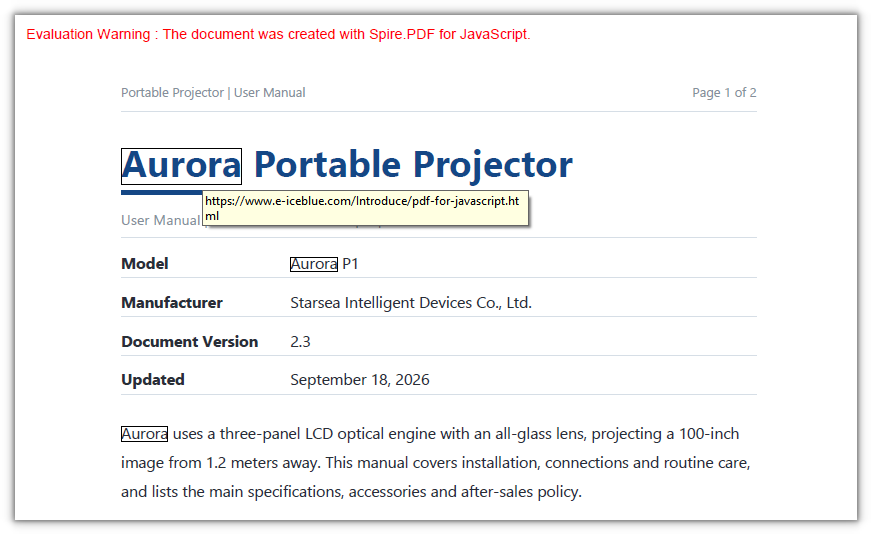
FAQ
Find() returns nothing even though the word is right there in the text
Cause: Options.Parameter defaults to TextFindParameter.None, which is case-sensitive, so searching for aurora will not match the capitalised Aurora; and the finder searches only the single page it was constructed with.
Fix: set it to IgnoreCase; to search the whole document, build one finder per page:
finder.Options.Parameter = pdfModule.TextFindParameter.IgnoreCase;
Measured: Aurora appears three times on page 1, and a case-sensitive search returns 0.
The link is there, but nothing shows up when the file is opened
Cause: this kind of link annotation is only a click hotspot — Spire generates no appearance stream (/AP) for it, and neither Chrome (PDFium) nor PyMuPDF (mupdf) draws a border for it; setting Border/Color only writes into the annotation dictionary (/Border [0 0 1], /C [0 0 1]) and stays invisible on the page.
Fix: the link is still clickable. In task 1 the hypertext, email, simple-text and document links all have their text drawn by the code, so they are visible to begin with; for a hotspot laid over existing text in task 2, do not rely on the annotation border — draw an underline at the link position with page.Canvas.DrawString().
Get a Free License
If you want to remove the evaluation message from the result document, or get past the feature limits, contact our sales team for a temporary 30-day license.